20 Ad-Hoc Production: Routing Trade-offs
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
20.1 Start With the Situation
This section: Start With the Situation — The network finds a short route, a path with few forwarding steps.
The network finds a short route, a path with few forwarding steps. That path may cross a weak battery with little charge left or an unstable link that loses contact. Failover means switching to another path after one fails. The team must compare alternatives, time that switch, and show why the selected path remains useful under change.
20.2 Overview
This section: Overview — This route challenges shortest-path thinking with energy, mobility, multipath, and field validation.
This route challenges shortest-path thinking with energy, mobility, multipath, and field validation.
This is part 2 of 2. Review Ad-Hoc Production: Readiness Checks when you need the first route.
20.3 Learning Objectives
This section: Learning Objectives
By the end of this chapter, you will be able to:
- explain why shortest path may not be best
- compare multipath and energy-aware routing
- validate failover and mobility behavior
The Misconception: Many developers assume shortest-path routing (minimum hop count) is always optimal for ad-hoc networks. After all, fewer hops mean lower latency and less forwarding overhead, right?
In the illustrative wildlife-tracking comparison below, shortest-path routing lasts 28 days while energy-aware routing lasts at least 140 days.
Illustrative wildlife-tracking comparison: Consider 50 sensor nodes across 2 km² of forest.
Shortest-Path Results (Week 1-4):
- In this illustrative comparison, 3 central nodes (high-betweenness) forward 85% of all traffic.
- These 3 nodes depleted batteries in 28 days (4 weeks)
- In this illustrative comparison, battery state falls from 40% to 5%, a 35-percentage-point drop (critical level).
- Network partitioned into 3 disconnected islands
- In this illustrative comparison, the remaining 47 nodes retain 70–85% battery (unused capacity).
- Effective network lifetime: 28 days
Energy-Aware Routing Results (Week 5-24):
- Deployed battery-aware routing (cost = hop_count / remaining_battery^2)
- Traffic distributed across 15 nodes instead of 3
- In this illustrative comparison, minimum battery is 32% after 20 weeks under energy-aware routing, versus 5% after 4 weeks under shortest-path routing; the observation windows differ.
- In this illustrative comparison, network lifetime reaches 140+ days, at least 5× the 28-day baseline.
Quantified Impact:
- In this illustrative comparison, network lifetime rises from 28 days (shortest path) to 140+ days (energy-aware), an increase of at least 400% relative to the 28-day baseline.
- In this illustrative comparison, battery-state standard deviation falls from 23 percentage points (shortest path) to 8 percentage points (energy-aware).
- Latency penalty: +1.2 hops average (acceptable for 1-hour reporting interval)
- Cost savings: Avoided 3 expensive technician visits for battery replacement
The Lesson: For delay-tolerant IoT applications (environmental monitoring, asset tracking, smart agriculture), energy-aware routing significantly outperforms shortest-path routing despite higher hop counts. Always consider application requirements (latency tolerance, battery budget, network lifetime goals) when selecting routing metrics.
Scenario: Industrial control network uses multi-path routing. Primary path fails - calculate total failover time to backup path.
Given:
- Primary path: A -> B -> C -> Gateway (3 hops, 45 ms latency)
- Backup path: A -> D -> E -> F -> Gateway (4 hops, 62 ms latency)
- Link failure detection: 100 ms (ACK timeout)
- Routing table update: 15 ms
- Packet buffering: 50 packets max
Steps:
- Failure detection: 100 ms (first missing ACK)
- Route switch: 15 ms (lookup backup in cache)
- First packet on backup: 62 ms (4-hop transmission)
- Total recovery: 100 + 15 + 62 = 177 ms
Result: <200 ms failover meets industrial control requirements. Without pre-cached backup, would need 2-3 seconds for route discovery.
-
Shortest-path routing
- Lowest delivery latency because it minimizes hop count.
- Baseline network lifetime, because busy relay nodes may drain early.
- Simple to implement.
- Best for latency-critical traffic.
-
Energy-aware routing
- May add latency by choosing less depleted relay nodes.
- Can extend network lifetime when load balancing avoids early relay depletion.
- Requires battery monitoring and route-cost updates.
- Best for long deployments of two years or more.
-
Hybrid routing
- May add latency compared with a simpler route choice.
- Can extend lifetime by balancing latency-critical and battery-sensitive traffic.
- Requires adaptive policy logic.
- Best when critical alerts and delay-tolerant telemetry share the same network.
Example: Wildlife tracking with a two-year battery requirement favors energy-aware routing despite higher latency.
The Mistake: Pre-caching backup paths without checking node battery levels, leading to failover to dying nodes.
Impact in this example: Primary path fails -> switches to backup -> the backup node at 8% battery fails -> both paths down.
Solution: Validate backup path battery levels during periodic health checks, invalidate backups with nodes <20% battery.
This section:
This section:
Common Pitfalls
This section: Common Pitfalls
Students often pick reactive protocols by default without analyzing traffic patterns. Proactive protocols (DSDV/OLSR) outperform reactive ones when traffic rate exceeds about 1 packet per 30 seconds per node because route discovery overhead amortizes. Profile your traffic before selecting a protocol.
Single-path routing fails silently when the primary route breaks, causing 2-5 minute outages while new routes are discovered. Multi-path routing pre-caches backup routes, reducing failure recovery to sub-second. Always implement at least two disjoint paths for critical links.
Deploying shortest-path routing in energy-constrained networks can drain busy relay nodes faster than others, causing premature partition. Energy-aware metrics such as residual battery and path length can distribute load and extend network lifetime.
Default beacon intervals (1-2 seconds) cause excessive control overhead in static scenarios and stale routes in fast-moving scenarios. Adaptive beaconing (increase rate on link-quality changes, decrease when stable) can reduce overhead while preserving useful route freshness under tested conditions.
This section:
This section:
20.4 Production Readiness Evidence Record
This section: Production Readiness Evidence Record — Production readiness is not the same as solving one routing exercise.
Production readiness is not the same as solving one routing exercise. A useful ad-hoc assessment asks whether the routing claim still holds when traffic rate, node mobility, relay battery, link quality, interference, gateway placement, or recovery policy changes.
The strategies in Figure 20.1 trade latency and delivery confidence against relay capacity and battery use.
Inspect Figure 20.1 and look for the production evidence that would justify moving traffic away from the shortest path.
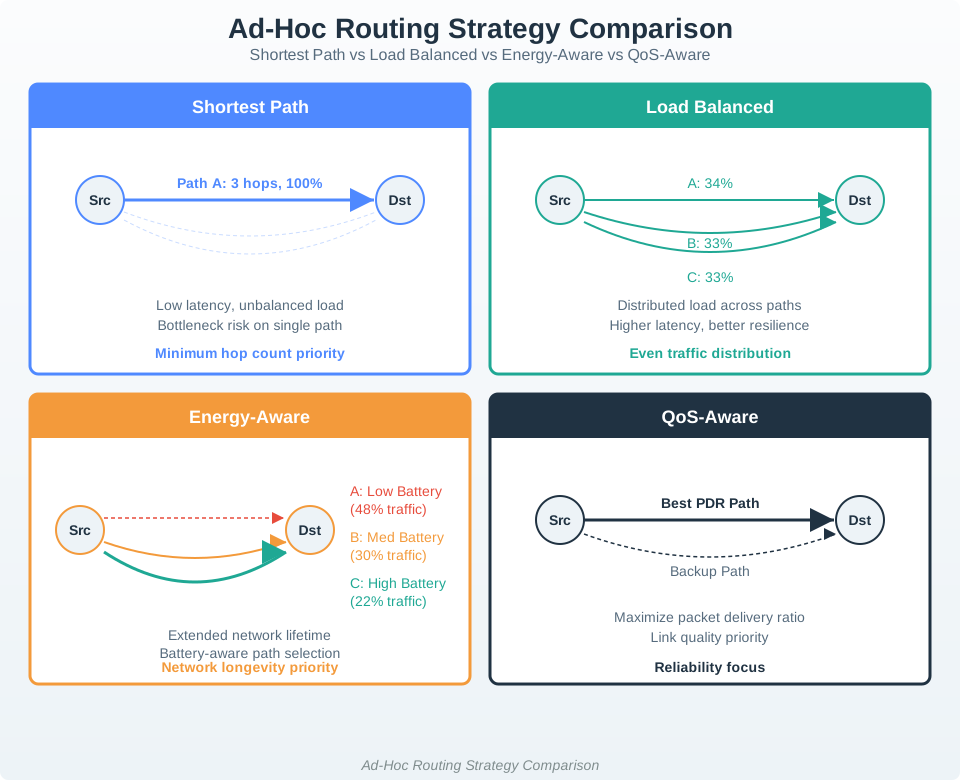
Read the four routes in Figure 20.1 by the cost each choice moves elsewhere. The shortest path cuts delay but loads central relays. Load sharing spreads traffic across several paths. Energy-aware routing avoids weak batteries but may use longer paths. QoS-aware routing chooses measured delivery and a current backup. In the wildlife case, fifteen nodes extend the stated life from 28 to at least 140 days. The ratio is , so life is at least five times greater while the mean path grows by 1.2 hops. Save relay load, battery, delivery, and delay before choosing.
Read Figure 20.1 from shortest path through load-balanced and energy-aware routing to the QoS-aware option. The fastest path can create hotspots; load balancing trades latency for resilience; energy-aware routing preserves weak relays; and QoS-aware routing prioritizes measured delivery with a backup. Production readiness depends on proving which of those consequences fits the observed condition.
| Assessment area | Evidence needed | Reject when |
|---|---|---|
| Routing fit | Traffic pattern, mobility, discovery delay, control overhead, and route-state evidence. | The protocol is chosen from a generic table without measured traffic. |
| Link evidence | PDR, RSSI, latency, and retry behavior for the observed radio condition and time window. | The record classifies a link from one metric while ignoring the others. |
| Failover evidence | Detection time, switch time, backup-path health, and first-packet delivery. | The record claims fast recovery but does not measure the sequence. |
| Energy evidence | Relay-load records, battery thresholds, path count, and route churn. | The route is called energy efficient without battery and forwarding evidence. |
Assessment rule: Accept the routing claim only for the traffic, topology, node energy, link quality, and failure condition that the assessment actually tested.
 Checkpoint: Evidence Before Release
You now know:
- The wildlife example shows why shortest-path routing can drain three central nodes in 28 days while energy-aware routing extends the same deployment to 140+ days.
- The release decision needs routing fit, link evidence, failover evidence, and energy evidence; a diagram alone is not enough.
- A production claim must name the retest trigger, such as node movement, battery threshold, gateway relocation, seasonal obstruction, firmware, or traffic change.
20.5 Selection Workflow: Ad-Hoc Release Record
This section: Selection Workflow: Ad-Hoc Release Record — The release record turns quiz-style answers into a maintainable production decision.
The release record turns quiz-style answers into a maintainable production decision. It keeps the chosen routing strategy, rejected alternatives, measured limits, operations owner, and retest trigger together.
| Record item | Question | Evidence to attach | Reject when |
|---|---|---|---|
| Traffic class | How often does each node send, and what happens if a packet is late or lost? | Message interval, payload type, alarm priority, stale-data rule, and loss budget. | The protocol is chosen before traffic is measured. |
| Route choice | Why does proactive, reactive, hybrid, multipath, or DTN behavior fit this deployment? | Control overhead, discovery delay, route age, path count, and mobility evidence. | The decision says “shortest path” without relay load, failure, or energy evidence. |
| Failover window | How long is the path unavailable after the specific failure? | Detection time, switch time, backup-path health, first packet on backup, and loss count. | The record skips one stage of the failover sequence. |
| Operations trigger | When must the routing assessment be rerun? | Node movement, battery threshold, gateway relocation, seasonal obstruction, firmware, or traffic change. | The team reuses old results after topology or traffic changed. |
Use this release workflow:
- State the deployment claim. Name the traffic, area, node count, gateway, mobility, and recovery requirement.
- Test the weak path. Use the worst likely relay, battery, obstruction, or mobility condition as the release gate.
- Record rejected routes. Explain which paths were excluded for latency, battery, PDR, security, or stale-route risk.
- Set the recheck trigger. Name the exact field change that invalidates the current assessment.
20.6 Failover State Machine Review
This section: Failover State Machine Review — Energy-aware routing has the same structure.
Fast recovery depends on the sequence of events, not the label “multi-path.” A node must detect the failed link, reject unsafe alternatives, choose a backup path with enough link and battery evidence, update forwarding state, and deliver the first packet under the new path. Each stage can fail or add delay.
Energy-aware routing has the same structure. It is not enough to avoid low-battery nodes once. The review must track relay duty, route churn, battery thresholds, link quality, and whether a backup path quietly moves the bottleneck to a different node.
| State | What to verify |
|---|---|
| Detection | ACK timeout, missed beacons, neighbor aging, and route expiry define when the node knows a path failed. |
| Candidate | Backup paths need current PDR, latency, battery, hop count, and loop-avoidance evidence. |
| Commit | The switch is complete only after forwarding state changes and the first packet succeeds on the backup path. |
| Decay | Cached routes decay as nodes move, batteries drain, radios change, and seasonal obstructions appear. |
Failure-analysis rule: When a recovery calculation looks strong, ask which state transition was measured and which was assumed. The unmeasured transition is usually where the production claim is weakest.
20.7 Checkpoint: Summary
This section: Checkpoint: Summary — This chapter consolidated key concepts for production ad-hoc network management through assessments and practice problems.
This chapter consolidated key concepts for production ad-hoc network management through assessments and practice problems.
Key Takeaways:
-
Protocol Selection Depends on Traffic Patterns: Proactive for frequent traffic, reactive for sparse traffic, hybrid for mixed patterns
-
Link Quality Classification Enables Smart Routing: PDR, RSSI, and latency thresholds classify links into four tiers for routing decisions
-
Multi-Path Redundancy Needs Measured Failover: Pre-cached backup paths can reduce recovery time when detection, switch, and first-packet delivery are recorded
-
Energy-Aware Routing Extends Lifetime: Distributing load across nodes prevents premature battery depletion and network partition
-
Shortest Path is Not Always Best: For delay-tolerant applications, measured relay load and battery state can justify energy-aware routing
-
Adaptive Strategies Beat Static Ones: Mobility-aware cache timeouts, priority-based path selection, and proactive link prediction outperform fixed configurations
20.8 Related Chapters: Further Reading
This section: Related Chapters: Further Reading
Foundational Papers:
- Perkins, C. E., & Bhagwat, P. (1994). “Highly dynamic destination-sequenced distance-vector routing (DSDV) for mobile computers.” ACM SIGCOMM.
- Johnson, D. B., & Maltz, D. A. (1996). “Dynamic source routing in ad hoc wireless networks.” Mobile Computing, Springer.
- Haas, Z. J., et al. (2002). “The zone routing protocol (ZRP) for ad hoc networks.” IETF Draft.
DTN and Epidemic Routing:
- Vahdat, A., & Becker, D. (2000). “Epidemic routing for partially connected ad hoc networks.” Duke University Technical Report.
- Fall, K. (2003). “A delay-tolerant network architecture for challenged internets.” ACM SIGCOMM.
Context-Aware and Social Routing:
- Musolesi, M., et al. (2005). “CAR: Context-aware adaptive routing for delay-tolerant mobile networks.” IEEE Transactions on Mobile Computing.
- Costa, P., et al. (2008). “Socially-aware routing for publish-subscribe in delay-tolerant mobile ad hoc networks.” IEEE JSAC.
IoT-Specific:
- RPL: IETF RFC 6550 - Routing Protocol for Low-Power and Lossy Networks
- Al-Karaki, J. N., & Kamal, A. E. (2004). “Routing techniques in wireless sensor networks: A survey.” IEEE Wireless Communications.
20.9 Related Chapters: References
This section: Related Chapters: References
-
Perkins, C. E. (2001). Ad Hoc Networking. Addison-Wesley.
-
Abolhasan, M., Wysocki, T., & Dutkiewicz, E. (2004). “A review of routing protocols for mobile ad hoc networks.” Ad Hoc Networks, 2(1), 1-22.
-
Zhang, Z. (2006). “Routing in intermittently connected mobile ad hoc networks and delay tolerant networks: Overview and challenges.” IEEE Communications Surveys & Tutorials, 8(1), 24-37.
-
Spyropoulos, T., et al. (2008). “Efficient routing in intermittently connected mobile networks: The multi-copy case.” IEEE/ACM Transactions on Networking.
-
IoT Routing Survey: Rajandekar, A., & Sikdar, B. (2015). “A survey of MAC layer issues and protocols for machine-to-machine communications.” IEEE Internet of Things Journal.
20.12 Visual Reference Gallery
This section: Visual Reference Gallery
Before comparing protocols, use Figure 20.2 to establish what the routing system must control. Look for the absence of a fixed coordinator, then identify the wireless neighbours and the multi-hop path that lets a node reach beyond its own radio range.
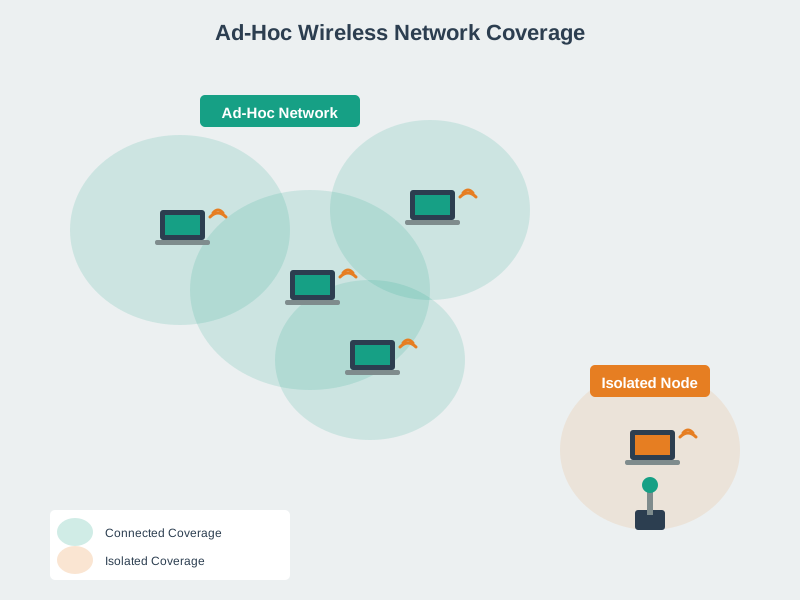
Read Figure 20.2 from an originating node through its immediate neighbour and onward to the remote node. Every relay is both a participant and part of the path, so movement, loss, or battery depletion changes the topology the protocol sees. That dependence is why production assessment begins with route formation and repair rather than assuming a permanent network backbone.
Once the network boundary is clear, inspect Figure 20.3 to decide when route knowledge should be paid for. Move from proactive to reactive to hybrid, comparing the control overhead incurred before traffic with the discovery delay incurred when traffic begins.
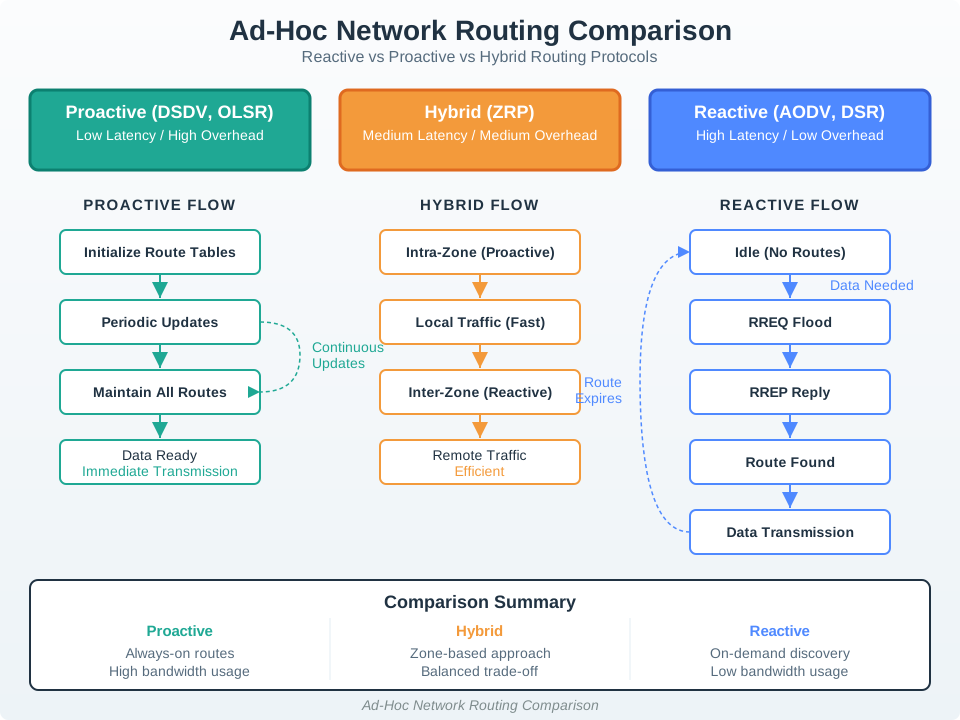
In Figure 20.3, the proactive branch keeps routes ready by spending periodic control traffic, while the reactive branch saves that idle work but discovers paths on demand. The hybrid branch limits proactive knowledge to a local zone and searches beyond it. The comparison turns the architecture into a workload decision: traffic frequency, mobility, and acceptable first-packet delay determine which cost is defensible.
Use Figure 20.4 to stress the previous protocol choice with fast three-dimensional movement. Start with the airborne peers, follow their changing inter-aircraft links, and then locate the air-to-ground boundary where mission data leaves the swarm.
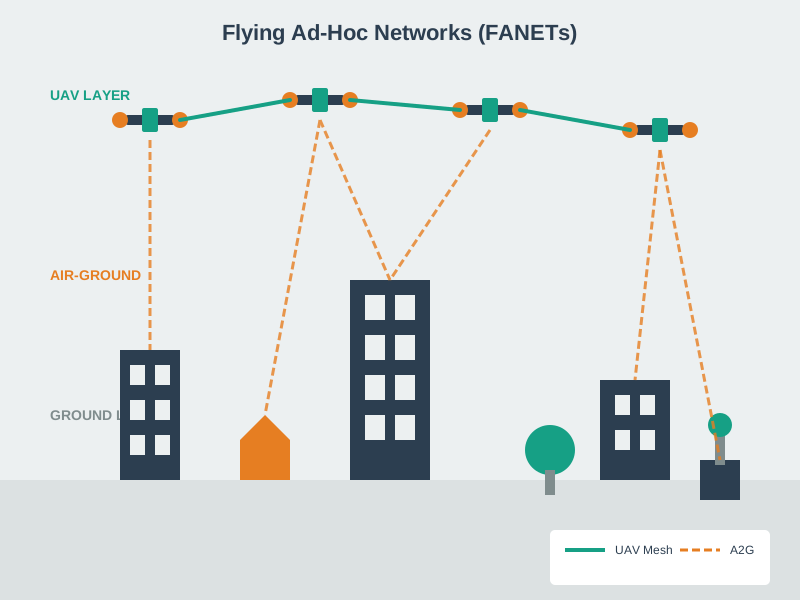
Figure 20.4 shows why a route that is valid at one instant can age quickly: aircraft separation and orientation alter both neighbour reachability and the path to the ground station. The production lesson is to assess route freshness, handoff behaviour, and degraded operation together; a protocol label alone does not prove that the swarm can preserve its mission traffic.
After choosing a routing family, inspect Figure 20.5 to see why its path metric must include deployment lifetime. Read the shortest-path case first, tracking which central relays carry repeated traffic, and then compare the battery distribution in the energy-aware case.
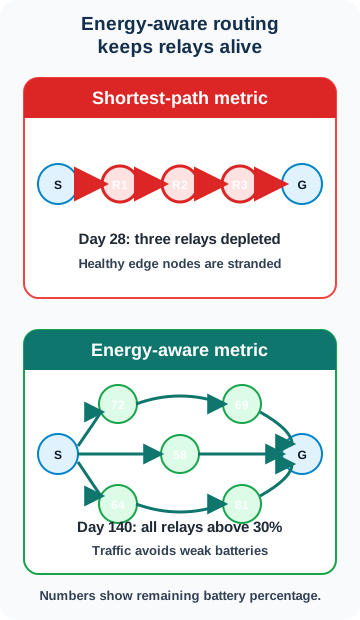
Read Figure 20.5 from “Traffic avoids weak batteries” to “Day 140: all relays above 30%”. In the illustrated 140-day comparison, “Traffic avoids weak batteries” and “Day 140: all relays above 30%” show how shortest-path routing concentrates traffic on high-betweenness nodes, depleting their batteries. In the illustrated comparison, energy-aware routing sacrifices average path length to spread load across more nodes and extends the modelled lifetime from 28 to at least 140 days. This visualization helps operators understand why “optimal” paths may be suboptimal for network longevity. For the illustrated Energy-Aware vs Shortest-Path comparison, the “Traffic avoids weak batteries” and “Day 140: all relays above 30%” labels connect load distribution to the next routing decision.
In Figure 20.5, minimizing hop count repeatedly selects the same high-betweenness relays, so those batteries become the partition point even while other nodes retain energy. The energy-aware strategy accepts longer paths to spread work and keep the topology connected. This connects path selection to the earlier production objective: the best route is the one that meets latency and delivery needs without silently shortening the useful life of the network.
Finally, use Figure 20.6 to turn the single-metric comparison into an explicit policy choice. Follow each source-to-destination path from left to right, noting whether traffic is concentrated, split, steered away from depleted nodes, or assigned according to delivery quality.
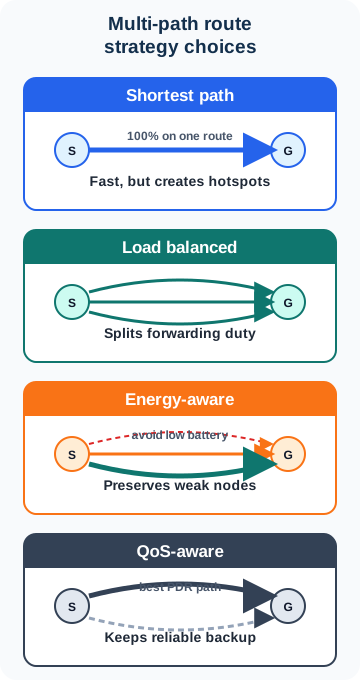
Figure 20.6 makes the consequence of each policy visible: shortest path optimizes immediate latency, load balancing reduces hotspots, energy-aware routing protects weak relays, and QoS-aware routing favours measured delivery with a backup. None is universally best. The running assessment therefore needs traffic priority, battery state, link evidence, and failover acceptance criteria before it can justify a production route policy.
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed