10 ZRP Routing: Tuning and Deployment
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
10.1 Start With the Situation
This section: Start With the Situation — A campus route now reaches beyond its local zone, the nearby nodes kept on known routes.
A campus route now reaches beyond its local zone, the nearby nodes kept on known routes. Its radius is the hop limit of that zone. Working once does not prove the limit is right. Test movement, control overhead, the extra route messages, and delivery, whether data reaches its target. Count battery cost before accepting the design. A radius that is too small repeatedly discovers distant routes; a radius that is too large spends airtime maintaining neighbors the application rarely uses. Record both control packets and delivered data on the same moving route so the chosen radius can be defended.
10.2 Overview
This section: Overview — This route turns ZRP mechanics into a measured tuning and deployment decision.
This route turns ZRP mechanics into a measured tuning and deployment decision.
This is part 2 of 2. Review ZRP Routing: Zones and Bordercast when you need the first route.
10.3 Learning Objectives
This section: Learning Objectives
By the end of this chapter, you will be able to:
- compare ZRP benefits and costs for IoT traffic
- tune zone radius with measured network evidence
- identify degeneration risks and field validation checks
This chapter connects to multiple learning resources:
Simulations Hub:
- Network Simulations - Interactive ZRP zone visualization and bordercast simulation tools
Videos Hub:
- Routing Protocol Videos - Visual explanation of ZRP operation and zone configuration
Quizzes Hub:
- Ad-hoc Routing Quizzes - Self-assessment on hybrid routing concepts
Knowledge Gaps Hub:
- Common Routing Misconceptions - Addressing confusion between proactive, reactive, and hybrid approaches
Misconception: Students often believe that increasing zone radius always improves ZRP performance by reducing route discovery overhead.
Reality: Zone radius selection involves critical trade-offs:
Zone Radius Too Large (ρ=5-7):
- Risk: high proactive overhead from maintaining routes to 50-100 nodes continuously.
- Risk: excessive update traffic as periodic routing updates flood the zone.
- Risk: large routing tables on resource-constrained IoT nodes.
- Risk: the protocol approaches pure DSDV overhead and loses its hybrid purpose.
Zone Radius Too Small (ρ=1):
- Risk: frequent reactive discoveries because most destinations are outside the zone.
- Risk: high bordercast overhead from constant route requests.
- Risk: increased latency because even nearby nodes may require discovery.
- Risk: the protocol approaches pure DSR behavior and loses its hybrid purpose.
Optimal Zone Radius (ρ=2-3):
- Benefit: balances proactive maintenance for nearby nodes with reactive discovery for distant nodes.
- Benefit: keeps latency low for frequent local communication inside the zone.
- Benefit: discovers occasional distant destinations efficiently through bordercast.
- Benefit: matches clustered IoT traffic, where sensors often report through a nearby gateway.
The Math: In a mesh network with average degree d=5:
- ρ=1: ~5 nodes in zone (very reactive)
- ρ=2: ~10-15 nodes in zone (balanced) ← Optimal
- ρ=3: ~25-50 nodes in zone (mostly proactive)
- ρ=4: ~75-125 nodes in zone (approaching DSDV overhead)
Key Insight: ZRP’s advantage comes from matching zone size to communication patterns, not maximizing zone size. Analyze your network’s traffic locality before choosing ρ!
10.4 Visual Reference Gallery
This section: Visual Reference Gallery — With the risks named, the final quizzes check component names, route-discovery order, and the right action from routing state.
Before focusing on zones, inspect Figure 10.1 to recover the network assumption ZRP must manage. The nodes organize through peer links without a fixed routing authority, so every zone and border decision is derived from changing neighbour relationships.
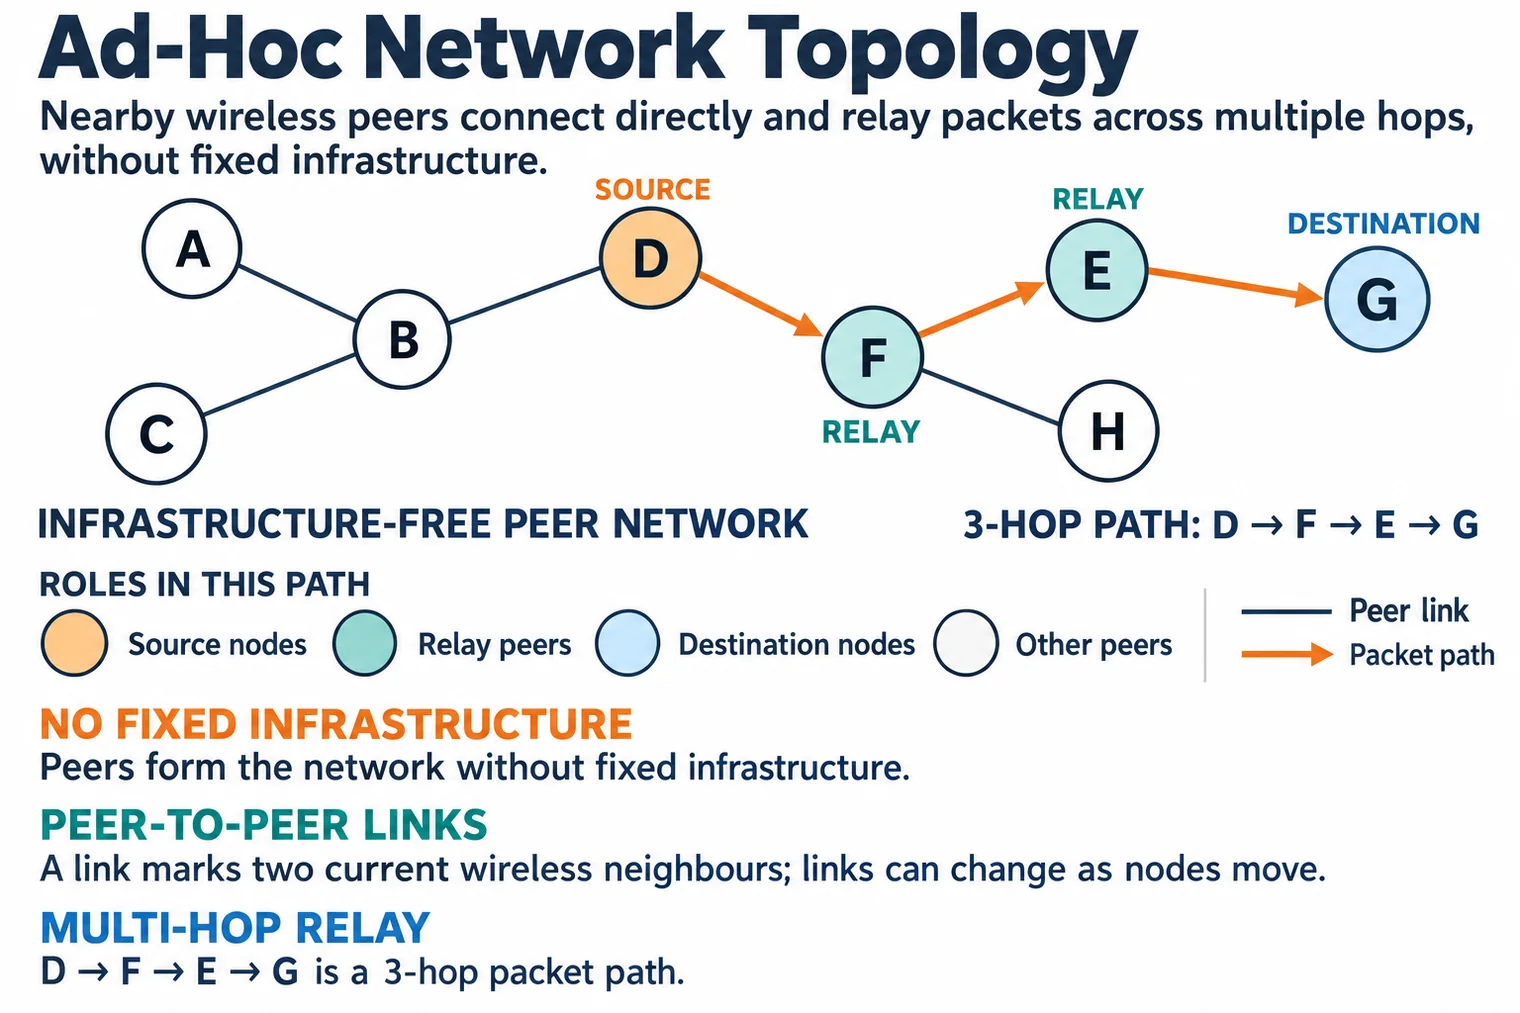
Read Figure 10.1 outward from a chosen node. Its nearby peers are candidates for proactive intra-zone state; nodes beyond that neighbourhood require a reactive search through border nodes. Then imagine one link disappearing as a node moves: the zone membership and useful border paths change with it. This returns the gallery to the running argument that zone radius must be justified from measured density, mobility, traffic, and control cost rather than fixed by habit.
ZRP only makes sense relative to the costs paid by the two routing families it combines. Inspect Figure 10.2 before choosing a radius, using the taxonomy to locate which work happens continuously and which work begins only when a route is needed.
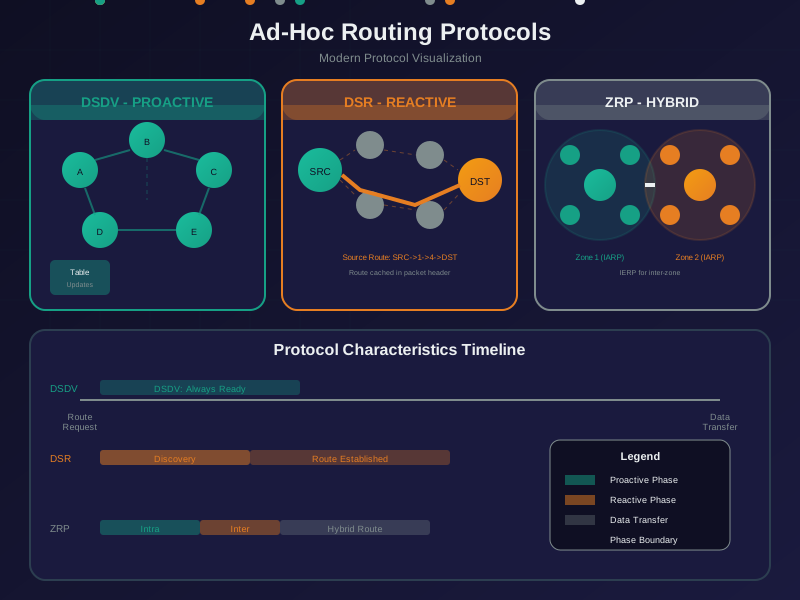
Read Figure 10.2 from proactive to reactive routing, comparing table-maintenance cost with discovery delay. Then locate ZRP between them: IARP keeps nearby routes ready, while IERP searches beyond the zone and BRP directs that search through border nodes. The position is a design contract, not a promise of automatic balance; the later sizing record must prove that both halves are doing useful work under the observed topology.
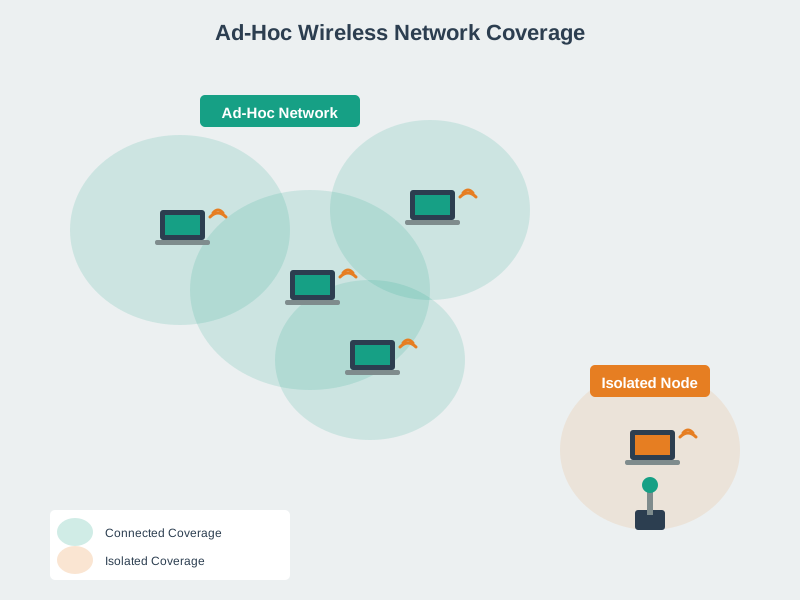
A geometric view of ad hoc network architecture, emphasizing the zone-based structure that ZRP leverages for efficient routing.
Scenario: University campus deploys 150 IoT sensors for environmental monitoring. Calculate optimal ZRP zone radius based on traffic patterns and topology.
Given:
- 150 sensor nodes across 5 buildings
- Building-local traffic: 75% (sensors within same building)
- Cross-building traffic: 25% (sensors to other buildings)
- Average node degree: 5 neighbors
- Typical intra-building path: 2-3 hops
- Inter-building path: 6-8 hops
- Data reporting: Every 2 minutes per sensor
Steps:
-
Calculate zone sizes for different radii:
- ρ=1: ~5 nodes (direct neighbors only)
- ρ=2: ~5 + (5 × 4) = 25 nodes (neighbors of neighbors)
- ρ=3: ~5 + 20 + 60 = 85 nodes (approaching building-wide)
- ρ=4: ~120 nodes (exceeds single building)
-
Analyze traffic locality:
- 75% traffic within building → Want most building covered proactively
- Average building: 30 sensors
- Target: ρ covers ≥80% of building sensors
-
Calculate proactive overhead for each ρ:
ρ=2 (25 nodes/zone):
- Proactive updates: Every 15s = 240/hour
- Per node: 24 routes × 50 bytes = 1,200 bytes
- Per node hourly: 240 × 1,200 = 288 kB
- Network: 150 × 288 kB = 43.2 MB/hour
ρ=3 (85 nodes/zone):
- Per node: 84 routes × 50 bytes = 4,200 bytes
- Per node hourly: 240 × 4,200 = 1,008 kB
- Network: 150 × 1,008 kB = 151.2 MB/hour
-
Calculate reactive traffic and an upper-bound query cost:
Assume each radius-two zone contains 25 other sensors from its 30-sensor building; each source therefore has 29 possible same-building destinations. Assume a radius-three zone contains all 29 local peers plus 56 peers in other buildings (85 peers total); each source has 120 possible other-building destinations. For this upper-bound illustration only, assume every packet to an out-of-zone destination needs a fresh query; real routes can be reused, so actual query counts may be lower.
ρ=2:
- Intra-building reactive share: 75% × (29 - 25) / 29 = 10.34% of all traffic
- Inter-building reactive share: 25% of all traffic
- Total reactive share: 35.34% of traffic
- Upper-bound fresh queries/hour: 150 sensors × 30 packets/hour × 0.353448 = about 1,591
- Assumed bordercast cost: about 30 nodes/query × 60 bytes = 1,800 bytes/query
- Upper-bound reactive overhead: about 1,591 × 1,800 = 2.86 MB/hour
ρ=3:
- Intra-building reactive share: 0% (all 29 local peers are in-zone)
- Inter-building reactive share: 25% × (120 - 56) / 120 = 13.33% of all traffic
- Upper-bound fresh queries/hour: 150 × 30 × 0.133333 = 600
- Upper-bound reactive overhead: 600 × 1,800 = 1.08 MB/hour
-
Compare overhead under those assumptions:
- ρ=2: 43.2 MB/hour proactive + 2.86 MB/hour reactive = about 46.06 MB/hour; 64.66% of traffic has a proactive route.
- ρ=3: 151.2 MB/hour proactive + 1.08 MB/hour reactive = 152.28 MB/hour; 86.67% of traffic has a proactive route.
-
Decision analysis:
- ρ=2: Lower modeled overhead, with 35.34% of traffic going to out-of-zone destinations.
- ρ=3: About 3.3× higher modeled overhead, but 22.01 percentage points more traffic stays in-zone.
- Trade-off: Is about 106 MB/hour of extra modeled overhead worth that additional coverage? Measure route reuse and actual zone membership before deployment.
-
Cost per avoided fresh query in this upper-bound model:
- Extra modeled overhead: 152.28 - 46.06293 = 106.21707 MB/hour
- Upper-bound fresh queries avoided: 1,590.52 - 600 = 990.52/hour
- Ratio: about 107 kB of extra overhead per avoided modeled query. This ratio is not a measured network cost.
Result: Choose ρ=2 (zone radius = 2 hops)
Rationale:
- 75% intra-building traffic mostly covered (2-3 hop paths, zone covers 2 hops)
- Overhead 3.3× lower than ρ=3
- 35.34% of traffic has out-of-zone destinations under the upper-bound model, acceptable for environmental monitoring (not latency-critical)
- Building-scale zones align naturally with campus physical topology
Alternative: If latency were critical (fire alarms), choose ρ=3 despite 3× overhead.
Key Insight: Optimal zone radius depends on traffic locality pattern. Match zone size to your network’s natural clusters (buildings, floors, departments). Oversizing zones (ρ → network diameter) degenerates to pure proactive with no hybrid benefit.
Choose zone radius based on measurable network characteristics and application requirements.
Selection factors:
- Small zone (rho = 1-2): a starting point for 20-50 nodes, sparse local traffic below 50%, network diameter above 10 hops, latency tolerance above 1 second, and tight battery budgets. In this planner example, it covers 5-10% of the network.
- Medium zone (rho = 2-4): a starting point for 50-200 nodes, moderate traffic locality of 50-80%, network diameter of 6-10 hops, latency targets of 200-1000 ms, and moderate overhead budgets. In this medium-zone planner example, it covers 20-40% of the network.
- Large zone (rho = 4-6): best for 200-1000 nodes only when local traffic is above 80%, network diameter is 4-6 hops, latency must stay below 200 ms, and nodes have enough power budget. In this large-zone planner example, it can cover 60-80% of the network, so watch for proactive degeneration.
Zone Radius Selection Algorithm:
def select_optimal_zone_radius(
    network_size: int,
    avg_neighbors: int,
    traffic_locality: float,  # 0.0-1.0, fraction of traffic within 3 hops
    latency_requirement_ms: int,
    overhead_budget_mb_per_hour: float
) -> int:
    """
    Calculate optimal ZRP zone radius.

    Returns: Recommended zone radius (hops)
    """

    # Estimate zone size for each radius
    zone_sizes = {
        1: avg_neighbors,
        2: avg_neighbors * (avg_neighbors - 1),
        3: avg_neighbors * (avg_neighbors - 1) ** 2,
        4: avg_neighbors * (avg_neighbors - 1) ** 3,
    }

    # Calculate overhead for each radius
    UPDATE_SIZE_BYTES = 50
    UPDATES_PER_HOUR = 240  # every 15s

    overheads = {}
    for radius, zone_size in zone_sizes.items():
        # Proactive overhead
        proactive = network_size * zone_size * UPDATE_SIZE_BYTES * UPDATES_PER_HOUR / 1e6  # MB

        # Reactive overhead (simplified)
        reactive_fraction = max(0, 1 - (zone_size / network_size))
        reactive = reactive_fraction * network_size * 30 * 1800 / 1e6  # MB (30 pkt/hr/node)

        total = proactive + reactive
        overheads[radius] = total

        # Check if within budget
        if total > overhead_budget_mb_per_hour:
            continue

        # Check latency coverage
        coverage = zone_size / network_size
        if coverage >= traffic_locality:  # Most local traffic covered proactively
            # Check latency requirement
            discovery_latency = 150  # ms (typical bordercast)
            if discovery_latency * (1 - coverage) < latency_requirement_ms * 0.2:  # 20% budget
                return radius

    # Fallback: Choose smallest radius within overhead budget
    for radius in sorted(overheads.keys()):
        if overheads[radius] <= overhead_budget_mb_per_hour:
            return radius

    return 1  # Minimum zone
Example Application:
optimal_radius = select_optimal_zone_radius(
    network_size=150,
    avg_neighbors=5,
    traffic_locality=0.75,  # 75% local
    latency_requirement_ms=500,
    overhead_budget_mb_per_hour=60
)
# Returns: 2 (for smart campus scenario above)
Tuning Rules:
- Start conservative: Begin with ρ = 2, measure actual traffic locality
- Monitor overhead: If overhead <50% of budget, consider ρ+1
- Track discovery rate: If >20% of packets require discovery, consider ρ+1
- Watch for degeneration: If zone_size > 60% of network, reduce ρ (becoming pure proactive)
Key Insight: Zone radius is not a fixed protocol parameter - it should be dynamically tuned based on observed traffic patterns and network density.
Read the warning as a diagnosis, not as a collection of tuning tips. Begin with geometry: compare the configured zone radius with the measured network diameter and the share of nodes reached inside one zone. If the radius covers almost every destination, IARP is maintaining nearly a complete routing table. At that point the reactive half of ZRP has little useful work left, because IERP rarely discovers an inter-zone route and BRP has few meaningful border nodes through which to direct a query.
Next connect that geometry to the measurements. High periodic control traffic with almost no reactive discoveries is evidence that the hybrid has collapsed toward proactive operation. Discovery latency may still remain because topology changes and implementations impose work of their own; the presence of three protocol components does not guarantee that their costs balance. Compare route-table entries per node, update bytes, discovery count, forwarding delay, memory, CPU activity, and energy under the same trace. A useful comparison keeps node positions, traffic, radio assumptions, and observation window fixed while changing only the radius.
Then test a smaller radius rather than accepting a formula as proof. The worked values below illustrate the intended direction: fewer destinations stay in the proactive zone, some distant traffic genuinely exercises IERP, and the control cost falls. The exact radius is deployment evidence, not a universal constant; density, mobility, traffic locality, and link asymmetry can all move the useful boundary. Re-run the same trace across candidate radii and reject settings that merely transfer too much cost from periodic maintenance into repeated discovery.
Finish with an operating rule that can be monitored after deployment. Record the chosen radius, observed zone-size distribution, fraction of traffic requiring inter-zone discovery, control bytes per delivered data byte, route-repair delay, and energy proxy. Add a recheck trigger for topology or traffic change. This keeps the running ZRP narrative intact: hybrid routing earns its complexity only while proactive local readiness and reactive distant discovery both contribute measurable value.
The Mistake: Configuring ZRP with zone radius ρ ≥ (network diameter / 2), causing hybrid protocol to behave like pure DSDV with all its overhead but none of ZRP’s benefits.
Real-World Example: A 2021 industrial IoT deployment set ZRP zone radius to ρ=8 in a 20-node factory network with 6-hop diameter. After 2 months:
- Routing overhead: 95 MB/hour (expected: 30 MB/hour)
- Discovery latency: Still 200 ms average (expected: <50 ms for local)
- In the illustrative factory scenario, battery life is 45% worse than in the DSDV-only comparison.
Root Cause Analysis:
-
Zone radius vs network diameter:
- ρ=8, network diameter=6 hops
- Zone covers entire network! (8 hops ≥ 6-hop max distance)
-
IARP behavior (intra-zone proactive):
- Each node maintains routes to ALL 19 other nodes proactively
- This is identical to DSDV (pure proactive)
-
IERP behavior (inter-zone reactive):
- No inter-zone traffic exists (all destinations within zone)
- IERP component never used (wasted complexity)
-
Bordercast optimization:
- Border nodes = nodes with neighbors outside zone
- With ρ ≥ diameter, zero border nodes (everyone’s zone covers network)
- Bordercast benefit: 0%
Quantified Waste:
ZRP (ρ=8) vs DSDV:
- Overhead: Both maintain 19 routes per node → Identical 95 MB/hour
- Complexity: ZRP has 3 protocol components (IARP, IERP, BRP) vs DSDV’s 1
- Memory: ZRP stores zone member lists + route tables vs DSDV’s single table
- CPU: ZRP runs 3 protocols vs 1
Result: ZRP with oversized zone is strictly worse than DSDV - same overhead, more complexity, more bugs, more maintenance.
How to Detect Oversized Zones:
Monitor these metrics - if ALL are true, zone is too large:
def is_zone_oversized(zone_radius, network_diameter, zone_size, network_size):
    """Returns True if zone radius should be reduced."""
    return all([
        zone_radius >= network_diameter / 2,  # Zone covers >50% of max distance
        zone_size > 0.6 * network_size,       # Zone covers >60% of nodes
        reactive_discovery_rate < 0.05        # <5% of traffic needs discovery
    ])
Correct Configuration for Factory Example:
- Network: 20 nodes, diameter=6 hops
- Optimal ρ: 2-3 hops (covers ~10-15 nodes = 50-75% of network)
- Result:
- Proactive: 10-15 routes per node (vs 19 in oversized)
- Reactive: 5-10 routes discovered on-demand
- Overhead reduction: 55% (from 95 MB/hr to 43 MB/hr)
Design Rules:
-
Maximum zone radius: ρ_max = min(diameter/2, sqrt(network_size)/2)
- For 20-node, 6-hop network: min(3, sqrt(20)/2) = min(3, 2.2) = 2 hops
-
Zone size constraint: Zone should cover 30-50% of network
- For 20 nodes: Target 6-10 nodes/zone → ρ=2-3 with avg_degree=5
-
Reactive traffic target: 20-40% of traffic should require inter-zone discovery
- If <10%, zone too large (degenerating to proactive)
- If >60%, zone too small (degenerating to reactive)
Measured Impact of Right-Sizing (Factory Fix):
- Before (ρ=8): Overhead 95 MB/hr, battery 4.2 months, identical to DSDV
- After (ρ=2): Overhead 43 MB/hr, battery 9.1 months, 55% savings, true hybrid behavior
- Result: 2.2× battery life extension by fixing single configuration parameter
Key Lesson: ZRP’s benefit comes from the hybrid behavior - proactive for common local routes, reactive for rare distant routes. Oversizing zones kills this benefit. Always validate that 20-40% of traffic requires inter-zone discovery; otherwise, reduce zone radius or switch to pure DSDV (simpler).
 Checkpoint: Degeneration Risks
You now know:
- Oversized zones make IERP idle and BRP useless because every destination is already inside the proactive zone.
- The factory example shows the failure mode: rho = 8 in a 20-node, 6-hop network produced 95 MB/hour overhead before right-sizing cut it to 43 MB/hour.
- A healthy design keeps some inter-zone discovery alive, with the chapter’s target range of 20-40% of traffic.
With the risks named, the final quizzes check component names, route-discovery order, and the right action from routing state.
Common Pitfalls
This section: Common Pitfalls
The optimal zone radius ρ depends on network density, mobility, and traffic pattern. Setting ρ too large causes excessive proactive overhead; ρ too small eliminates the benefit of local pre-computed routes. Use analytical models or simulation to find the optimal ρ for your specific deployment scenario.
As nodes move, the composition of each node’s routing zone changes. Nodes entering and leaving zones require updating the IARP routing tables. High mobility causes frequent zone membership changes and associated overhead — ZRP performs worst in high-mobility scenarios where zones are unstable.
ZRP’s bordercast reduces flooding by sending inter-zone route requests only to border nodes. Implementing full flooding instead of bordercast eliminates ZRP’s primary advantage over pure reactive routing. The bordercast mechanism requires identifying border nodes — nodes at exactly ρ hops from the source.
ZRP comparisons are only fair when ρ is tuned to the specific scenario. Comparing ZRP with ρ=1 (effectively pure reactive) to DSDV in a dense, low-mobility network makes ZRP appear worse than a properly configured ZRP would be. Always tune the hybrid parameter before comparing to pure alternatives.
This section:
This section:
10.5 Summary
This section: Summary
This chapter covered ZRP (Zone Routing Protocol) as a hybrid routing approach for ad hoc networks:
- Hybrid Architecture: ZRP combines proactive routing within local zones (IARP) and reactive discovery between distant zones (IERP) to balance overhead and latency
- Zone-Based Design: Each node defines a routing zone with configurable radius ρ, maintaining proactive routes to all nodes within ρ hops while using on-demand discovery beyond
- Protocol Components: IARP handles intra-zone routing using table-driven updates, IERP manages inter-zone reactive discovery, and BRP enables efficient bordercast query propagation
- Zone Radius Selection: Critical parameter ρ determines trade-off between proactive overhead (grows with larger zones) and reactive discovery frequency (increases with smaller zones)
- Bordercast Optimization: Route requests sent only to zone border nodes rather than full network flooding, significantly reducing discovery overhead compared to pure reactive protocols
- Performance Characteristics: ZRP achieves low latency for nearby destinations (proactive), scalable distant communication (reactive), and reduced flooding overhead (bordercasting)
- Optimal Configuration: Typical zone radius ρ = 2-3 hops balances proactive maintenance costs with reactive discovery needs, though optimal value depends on network size, density, and traffic patterns
10.6 What’s Next
This section: What’s Next
- Revisit proactive routing DSDV: DSDV Proactive Routing
- Study reactive routing DSR: DSR Fundamentals and Route Discovery
- Explore DTN for disconnected networks: DTN Store-Carry-Forward
- Learn about ad hoc network applications: Ad-Hoc Network Applications
- Compare ad hoc routing deployment choices: Deploying Ad-Hoc Networks
10.7 Key Takeaway
This section: Key Takeaway — ZRP combines proactive routing inside a local zone with reactive discovery beyond it.
ZRP combines proactive routing inside a local zone with reactive discovery beyond it. The zone radius is the main tradeoff: small zones reduce overhead, while larger zones improve immediate route knowledge.
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed