19 Ad-Hoc Production: Readiness Checks
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
19.1 Overview
This section: Overview — This first route defines production evidence and transfers it across realistic ad-hoc scenarios.
This first route defines production evidence and transfers it across realistic ad-hoc scenarios.
This is part 1 of 2. Continue with Ad-Hoc Production: Routing Trade-offs for the second focused route.
19.2 Start Simple
This section: Start Simple
19.2.1 Test the Network on Its Worst Day
A protocol is an agreed set of rules for how devices exchange information. That name alone cannot prove that a field network is ready.
Picture a search team carrying devices beyond fixed coverage. People move, a relay loses power, and two groups meet after a long break. The system must still carry the right report to the right place without hiding old or copied data.
Choose one mission record. Keep its source, time, location, version, and expiry with it. Break a link, remove a useful relay, fill a queue, and reunite the groups. Check what was stored, copied, dropped, delivered twice, or delivered too late. Name the safe action when current evidence is missing.
Keep the field log plain. Who made the record? When was it made? Who held it next? When did it expire? Who saw it at the end? A missing answer is a test result, not a reason to guess.
Passing this review does not prove every route will work. It proves that the team measured named failures and knows when to reduce the service claim. The deeper material compares routing methods, energy costs, mobility, and release records. Use those details only after the field decision and its evidence are clear.
19.3 Start With the Readiness Question
This section: Start With the Readiness Question — A production-readiness assessment asks a blunt question: would this ad-hoc system still serve users when the field behaves badly?
A production-readiness assessment asks a blunt question: would this ad-hoc system still serve users when the field behaves badly? Mobility, interference, battery limits, node loss, and operator mistakes all count as normal conditions.
Start with one scenario the system claims to survive. The assessment then becomes a chain of evidence: what must be measured, what threshold is acceptable, and what action follows when the evidence fails.
The mathematical gist. If transmit power really scales with hop distance as , splitting a fixed span into equal hops changes ideal transmit energy by . But this chapter’s fixed radio ledger charges every hop 0.5 mJ to transmit and every relay 0.2 mJ to receive, so six hops cost mJ while three cost mJ. Distance physics can favour shorter hops while fixed radio overhead favours fewer hops; a routing claim must state which model its evidence uses.

Temperature Terry needed to send an urgent temperature reading to the Gateway across the farm, but the direct path was blocked by a tractor!
“No worries!” said the microcontroller. “We have THREE different paths planned ahead of time. Think of it like knowing three different ways to get to school — if one road is blocked, you just take another!”
the battery added, “But not all paths are equal! I prefer the one where my friends along the way have plenty of energy left. If we always use the same shortcut, those friends get tired really fast.”
the LED blinked to explain: “Imagine passing a note in class. The shortest row might be fastest, but if those kids pass EVERY note, they get tired of it. Spreading notes across different rows keeps everyone happy and willing to help!”
The lesson: Smart networks plan backup routes BEFORE problems happen, and they share the work so no single helper gets worn out!
19.4 Learning Objectives
This section: Learning Objectives
By the end of this chapter, you will be able to:
- Apply Routing Knowledge: Select appropriate routing strategies for different deployment scenarios
- Analyze Network Trade-offs: Evaluate energy vs latency vs reliability trade-offs
- Solve Production Problems: Work through real-world multi-hop network challenges
- Diagnose Network Issues: Identify bottlenecks, link failures, and routing inefficiencies
- Compare Protocol Behavior: Distinguish between proactive, reactive, and hybrid approaches
- Design Failover Strategies: Implement multi-path redundancy for reliable delivery
19.5 Prerequisites
This section: Prerequisites
Required Chapters:
- Ad Hoc Networks: Production Framework - Framework implementation
- Ad-Hoc Network Basics - Core ad-hoc concepts
- Routing Basics - Routing protocols
Estimated Time: 30 minutes
This chapter tests your understanding of ad-hoc network concepts through quizzes, worked examples, and scenario-based exercises. If you are new to the topic:
- Start with the protocol comparison table at the top to review the three routing approaches (proactive, reactive, hybrid).
- Read the worked examples carefully — they walk through real calculations step by step with numbers you can follow.
- Try the understanding checks by thinking about the scenarios BEFORE reading the answers. Even if you get them wrong, the explanations will deepen your learning.
- If any concept is unfamiliar, revisit the Ad-Hoc Network Basics or Multi-hop Fundamentals chapters first.
19.6 Introduction
This section: Introduction — This chapter consolidates your understanding of production ad-hoc networks through comprehensive knowledge checks, worked examples, and understanding exercises.
This chapter consolidates your understanding of production ad-hoc networks through comprehensive knowledge checks, worked examples, and understanding exercises. Follow the assessment in order: establish the routing family and link-quality evidence first, apply those choices to energy and failover scenarios next, and finish by defending the operational decision and its limits. That sequence keeps each answer tied to an observable network condition rather than protocol recall alone.
- First review protocol families and link-quality thresholds.
- Then test the basics with quick checks.
- Next apply the same logic to failover, alert routing, range, social routing, caching, energy, and mobility.
- After that pressure-test the shortest-path misconception.
- Finally turn quiz answers into a release record with retest triggers.
Checkpoints recap; collapsed depth-l1 and depth-l2 sections are optional slowdowns.
19.7 Ad-Hoc Routing Protocol Comparison
This section: Ad-Hoc Routing Protocol Comparison — Understanding the trade-offs between routing protocol types is essential for production deployments.
Understanding the trade-offs between routing protocol types is essential for production deployments.
Ad-hoc Routing Protocol Comparison
-
Proactive: DSDV and OLSR
- Maintains routes continuously with periodic updates.
- Uses higher control overhead to keep route latency low.
- Best for frequent, predictable traffic where routes are needed often.
-
Reactive: AODV and DSR
- Discovers routes only when traffic needs a path.
- Keeps idle overhead low but adds route-discovery delay.
- Best for sparse or occasional traffic.
-
Hybrid: ZRP
- Maintains proactive routes inside a local zone and discovers distant routes reactively.
- Balances overhead and latency through the configured zone radius.
- Best for mixed traffic patterns.
Inspect Figure 19.1 and look for the shared measurement gate that prevents a protocol-family shortcut.
Start Figure 19.1 with node motion, traffic rate, and the budget for route updates. Frequent, known traffic may suit DSDV or OLSR because their ready routes cut send delay. Sparse traffic may suit AODV or DSR because they avoid idle updates but wait for a search. ZRP splits those costs at a local radius. Every path ends at the same gate. Measure delivery, route and repair delay, control traffic, energy, and scale on the same motion and link trace. A family name hints at behavior; only common test evidence shows which choice meets the site limits.
Protocol Selection Guidelines:
- Connected, static, frequent traffic -> DSDV
- Connected, mobile, sparse traffic -> DSR
- Connected, mixed traffic -> ZRP
- Disconnected, abundant resources -> Epidemic
- Disconnected, constrained resources, predictable -> CAR
19.8 Link Quality Classification
This section: Link Quality Classification — Understanding how to classify and respond to link quality changes is critical for maintaining network reliability.
Understanding how to classify and respond to link quality changes is critical for maintaining network reliability.
Inspect Figure 19.2 and ask whether all three measurements place the worked link in the same quality tier.
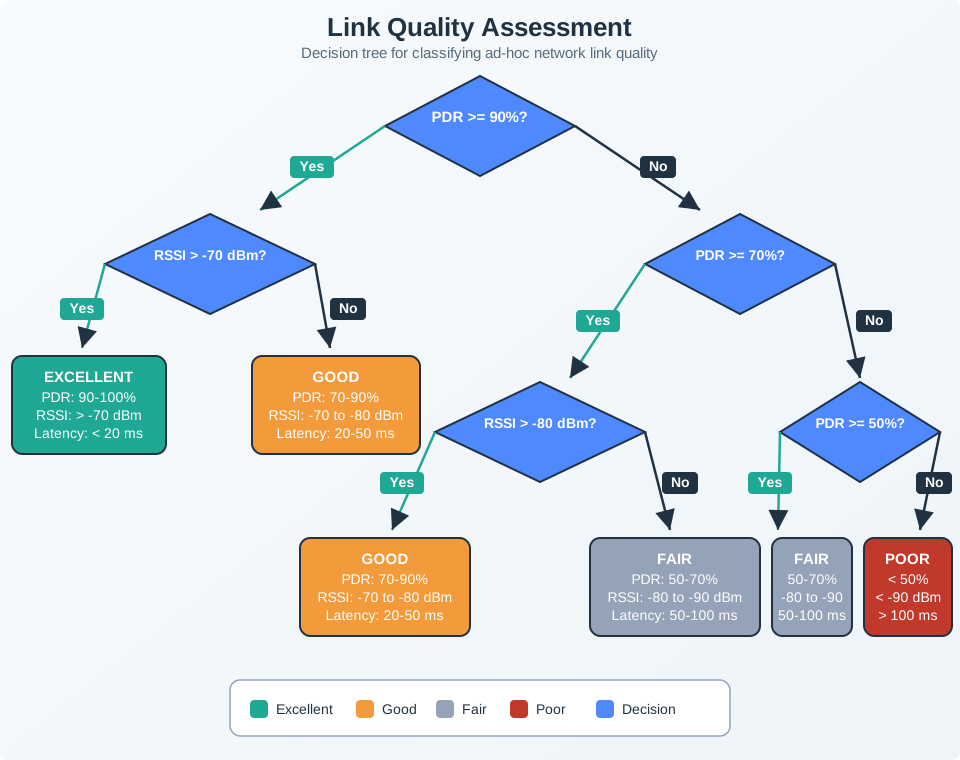
Use Figure 19.2 in the stated order: packet delivery ratio, signal strength, then latency. The worked link reports 82% PDR, -74 dBm RSSI, and 35 ms latency. Its delivery check is , which places that measurement in the Good band; -74 dBm lies between -80 and -70 dBm, and 35 ms lies between 20 and 50 ms, so the other observations agree. Agreement matters because a strong signal alone can coexist with congestion or interference. The tree supports the readiness argument by turning several measurements into a traceable classification, while a mixed result should remain visible rather than being rounded into an optimistic label.
19.9 Inline Knowledge Check
This section: Inline Knowledge Check
19.10 Selection Workflow: Routing Strategy Comparison
This section: Selection Workflow: Routing Strategy Comparison — Different routing strategies optimize for different objectives.
Different routing strategies optimize for different objectives. Understanding when to apply each is essential for production deployments.
Trade-offs Summary:
- Control overhead: proactive is high, reactive is low, and hybrid is medium because the zone radius controls how much state is maintained.
- Route latency: proactive is low because routes are ready, reactive is high because discovery happens on demand, and hybrid is configurable.
- Scalability: proactive scales poorly in large or fast-changing networks; reactive and hybrid approaches scale better.
- Mobility support: proactive handles moderate mobility, while reactive and hybrid approaches usually adapt better to changing links.
 Checkpoint: Protocol Fit and Link Evidence
You now know:
- Proactive, reactive, and hybrid routing differ mainly in control overhead, route latency, and how much route state they keep ready.
- A GOOD link is not a guess: the example classifies 82% PDR, -74 dBm RSSI, and 35 ms latency against the 70-90% PDR, -70 to -80 dBm, and 20-50 ms bands.
- A route choice is ready for production discussion only after traffic pattern, mobility, link quality, energy state, and recovery requirement are connected.
19.11 Knowledge Check
This section: Knowledge Check
19.12 Worked Examples
This section: Worked Examples
Scenario: A smart agriculture deployment monitors 40 hectares of vineyard with soil moisture sensors. The gateway receives data from sensors via multi-hop ad-hoc network. During harvest season, vineyard workers and machinery frequently block wireless paths, causing link failures.
Given:
- Primary path: Sensor S1 -> Node A -> Node B -> Gateway (3 hops, latency 45 ms)
- Backup path 1: S1 -> Node C -> Node D -> Node E -> Gateway (4 hops, latency 62 ms)
- Backup path 2: S1 -> Node F -> Node G -> Gateway (3 hops, latency 58 ms, but G has 35% battery)
- Link A-B failure rate during harvest: 15 failures/day, average recovery time: 8 seconds
- Data transmission frequency: every 5 minutes (288 transmissions/day)
- Maximum acceptable packet loss: 2%
Steps:
-
Calculate expected failures during transmission windows:
- Transmissions per day: 288
- Link failures per day: 15
- Probability of failure during any transmission: 15 x 8s / (24 x 3600s) = 0.14%
- However, failures cluster during work hours (8am-6pm): 15 failures in 10 hours
- During work hours: 15 x 8s / (10 x 3600s) = 0.33% per transmission
-
Evaluate single-path (no backup) outage exposure:
- Each failure blocks 8 seconds of communication
- Expected transmissions overlapping one failure: 8s / 300s = 0.0267
- Across 15 non-overlapping failures: 15 × 0.0267 = 0.4 transmissions/day exposed
- Exposure share: 0.4/288 = 0.14% of daily transmissions (or 0.4/120 = 0.33% during work hours); actual packet loss also depends on retry and queue behavior
-
Design multi-path failover strategy:
- Detect failure: Link-layer ACK timeout (100 ms)
- Switch to backup: Immediate failover to pre-cached alternate path
- Path selection priority:
- Backup path 2 (F->G) rejected: G at 35% battery (below 40% threshold)
- Backup path 1 (C->D->E) selected: All nodes >60% battery
-
Calculate multi-path recovery time:
- Failure detection: 100 ms (ACK timeout)
- Path switch: 5 ms (cache lookup)
- First packet on backup: 62 ms (backup path latency)
- Total recovery: 167 ms (vs 8 seconds without backup)
-
Assess recovery exposure:
- The modeled recovery window falls from about 8 seconds to 167 ms; actual packet loss depends on retry, queueing, and failure timing.
- Retain the 2% packet-loss target as a requirement to test with the deployment’s retry and drop policy.
Result: The modeled recovery window falls from about 8 seconds to 167 ms; actual packet loss depends on retry, queueing, and failure timing. The 2% packet-loss target remains to be tested.
Key Insight: In this example, a pre-cached backup reduces an eight-second route outage to a 167 ms recovery window. The key is pre-computing and caching backup paths, not discovering them after failure. Path selection should consider both latency and node energy to maintain backup availability throughout deployment lifetime.
Scenario: An industrial safety monitoring system detects gas leaks and must deliver alerts to the control room within 500 ms. The default energy-aware routing uses 6-hop paths to preserve battery, but this may violate latency requirements.
Given:
- Network topology: 25 nodes monitoring a chemical plant
- Control room gateway: Central location
- Current routing metric: Energy-aware (minimizes battery drain)
- Current path: Sensor -> 6 hops -> Gateway (typical latency: 420 ms)
- Alternative path: Sensor -> 3 hops -> Gateway (latency: 180 ms)
- Per-hop latency: ~60 ms (transmission + propagation + processing)
- Energy cost per hop: ~0.5mJ transmission, ~0.2mJ reception
- Alert frequency: 2-3 per month (rare)
- Normal telemetry: every 60 seconds
Steps:
-
Analyze latency breakdown for 6-hop path:
- Per-hop delay: 60 ms average
- 6 hops x 60 ms = 360 ms transmission
- Queueing delays at intermediate nodes: ~60 ms
- Total: ~420 ms (within 500 ms budget, but minimal margin)
-
Calculate worst-case latency scenarios:
- Network congestion (2 packets queued): +120 ms
- Retransmission (1 lost packet): +80 ms
- Worst case: 420 + 120 + 80 = 620 ms (exceeds 500 ms!)
-
Design priority-based hop optimization:
- Normal telemetry: Use the 3-hop path; in this model it is both faster and lower-energy than the 6-hop baseline.
- Critical alerts: Switch to 3-hop minimum-latency path
- Path selection trigger: Alert priority flag in packet header
-
Calculate optimized alert latency:
- 3 hops x 60 ms = 180 ms baseline
- Worst case with congestion/retry: 180 + 120 + 80 = 380 ms
- Below 500 ms in the modelled congestion and single-retry case
-
Evaluate energy trade-off:
- 6-hop energy: 6 x 0.5mJ + 5 x 0.2mJ = 4.0mJ per packet
- 3-hop energy: 3 x 0.5mJ + 2 x 0.2mJ = 1.9mJ per packet
- Surprisingly, 3-hop path uses 52% less energy!
-
Calculate annual impact:
- Alerts: 30/year x 1.9mJ = 57mJ (negligible)
- Telemetry on 6-hop: 525,600 packets x 4.0mJ = 2,102,400mJ
- Telemetry on 3-hop: 525,600 x 1.9mJ = 998,640mJ
- 3-hop saves 1,103,760mJ (52.5%) annually
Result: Switching critical alerts to the 3-hop path reduces worst-case latency from 620 ms to 380 ms, guaranteeing compliance with the 500 ms requirement. Unexpectedly, the 3-hop path also uses 52% less energy per packet than the 6-hop baseline path.
Key Insight: “Energy-aware” routing doesn’t always mean more hops. Longer paths consume more cumulative energy (more transmissions + receptions) even if each link is energy-efficient. For rare critical alerts, always use minimum-hop paths - they’re both faster AND more energy-efficient. Reserve complex routing optimizations for bulk data transfer where the overhead is amortized.
This section:
Checkpoint: Worked Failover Claims
You now know:
- In the vineyard example, the modeled recovery window falls from about 8 seconds to 167 ms; actual packet loss depends on retry, queueing, and failure timing.
- A backup route must pass both timing and energy checks: the 35% battery path is rejected against the 40% threshold even though it is short.
- For critical alerts, the 3-hop path changes worst-case latency from 620 ms to 380 ms and stays inside the 500 ms budget.
This section:
19.13 Knowledge Check
This section: Knowledge Check — Apply these concepts to real-world deployment scenarios.
Apply these concepts to real-world deployment scenarios.
Scenario: Earthquake destroys cellular infrastructure. 50 rescue workers need communication across 2km disaster zone. Each radio: 500m range, 1W transmit power, battery lasts 8 hours continuous transmission.
Think about:
- Calculate minimum hops for end-to-end connectivity (2000m coverage)
- Why not use a single 2 km-range radio (16× transmit power in this free-space example for the same received-power target)? ITU-R P.525-5
- How does multi-hop extend battery life in energy-constrained scenarios?
Key Insight: Minimum hops = 2000m / 500m = 4 hops. Path: Source -> Node1(500m) -> Node2(1000m) -> Node3(1500m) -> Dest(2000m). In a free-space link model, received power falls with the square of distance; doubling the distance requires four times the transmit power to hold received power constant. ITU-R P.525-5 Under that free-space, equal-antenna link model, a single 2 km link needs 16× the transmit power of a 500 m link (1 W × 16 = 16 W in this example), compared with four 500 m hops transmitting at 1 W each. ITU-R P.525-5 Battery impact: 16W transmission = 30 minutes runtime vs 1W multi-hop = 8 hours. Multi-hop isn’t just about range - it’s about energy efficiency. Disaster response networks prioritize battery life over latency.
Scenario: University campus deploys delay-tolerant messaging app for 5,000 students. Epidemic routing floods 50+ message copies per message. SocialCast analyzes: contact frequency (Alice-Bob meet daily), recency (last contact 2 hours ago), location similarity (both frequent library).
Think about:
- Why does epidemic routing work but waste bandwidth?
- In this illustrative campus scenario, how would SocialCast reduce copies from 50 to 5–10 while targeting 90% delivery?
- What happens when social patterns are unpredictable (random mobility)?
Key Insight: In this campus example, epidemic routing floods copies broadly, but it does not guarantee delivery; compare the assumed copy counts before claiming bandwidth savings. RFC 4838 SocialCast = forward only if carrier’s social metrics > current holder’s. Example: Message for “Bob”. Current holder “Charlie” (meets Bob monthly). Encounters “Alice” (meets Bob daily) -> transfer to Alice (higher contact frequency). Encounters “Dave” (never meets Bob) -> don’t transfer. Result: 5-10 targeted copies follow social graph toward Bob. In this illustrative campus scenario, assume 90% delivery and 5–10 targeted copies instead of 50; measure transmitted bytes before claiming bandwidth savings. Perfect for human mobility (predictable social patterns). Fails for random mobility (no patterns to exploit) - use epidemic instead.
Scenario: Disaster response team uses DSR routing. Command post (stationary) communicates with mobile rescue teams (3-5 m/s). Device caches 5 routes. After 10 minutes, 40% of routes have stale/broken links due to mobility.
Think about:
- Calculate optimal cache timeout balancing freshness vs discovery overhead
- Why not always perform fresh route discovery (zero cache)?
- How does mobility speed affect ideal timeout?
Key Insight: Static timeout fails: 10min timeout -> 40% stale routes -> packet failures. 30sec timeout -> excessive RREQ floods (high overhead). Adaptive solution: Monitor ROUTE_ERROR rate: High errors (>5/min) -> reduce timeout to 2-3min (high mobility). Low errors (<1/min) -> extend timeout to 10min (stable topology). Mobility-aware: Command post to command post: 10min cache (stationary). Rescue team to rescue team: 2min cache (mobile). Mixed: 5min cache. Why not zero cache? Discovery latency: 50-200 ms per RREQ/RREP cycle. Real-time voice needs <100 ms. Cached routes = instant forwarding. Result: Adaptive caching = DSR’s low latency + mobility resilience. Route lifetime inversely proportional to node velocity.
Scenario: 20-node ad-hoc network has 3 paths from source to gateway: Path A (3 hops, nodes at 40% battery), Path B (4 hops, nodes at 80% battery), Path C (5 hops, nodes at 95% battery). Need to route 1000 packets while maximizing network lifetime.
Think about:
- Why doesn’t shortest-path routing (Path A) maximize network lifetime?
- Calculate battery depletion if all traffic uses Path A vs distributed across all paths
- How does energy-aware routing trade latency for longevity?
Key Insight: Shortest-path (Path A only): 1000 packets drain 40% -> 0% battery on 3 nodes -> network partition (other nodes isolated). Energy-aware distribution: 300 packets on A (40% → 28%), 400 packets on B (80% -> 70%), 300 packets on C (95% -> 88%). Minimum battery: 28% (vs 0% shortest-path). Spreading this scenario’s 1,000 packets across three paths leaves the weakest path at 28% battery rather than 0%; estimating lifetime also needs a time and failure model. Trade-offs: Under an equal per-hop-delay assumption, Path C has 67% higher path delay (5 hops versus 3) but uses nodes with abundant energy. Production strategy: Route delay-tolerant traffic on long/high-battery paths, route real-time traffic on short/low-latency paths. Prevents premature node deaths that partition network.
Scenario: Ad-hoc network link between Node A and Node B: current RSSI -65 dBm, PDR 95%, nodes approaching at 2 m/s, will separate in 30 seconds. Link quality monitor must predict when link becomes unusable (RSSI < -85 dBm, PDR < 50%).
Think about:
- Calculate when proactive rerouting should trigger (before link failure)
- Why is prediction better than reactive rerouting after failure?
- How does mobility speed affect prediction accuracy?
Key Insight: Path loss increases with distance: RSSI drops ~3-4 dB per doubling distance. At 2 m/s separation velocity: Distance = 2 m/s x 30s = 60m additional separation. RSSI degrades: -65 dBm (now) -> -75 dBm (15s) -> -85 dBm (30s) -> link fails. Proactive rerouting: Trigger new route discovery at 20s (RSSI -80 dBm, PDR 70%) before complete failure. Gives 10s buffer for RREQ/RREP exchange. Reactive rerouting: Wait until link fails (PDR <50%) -> buffer loss, 200 ms discovery delay, user-visible disruption. Prediction accuracy: High mobility (5 m/s+) -> prediction horizon 10-15s (short). Low mobility (1 m/s) -> horizon 60s+ (plenty of time). Use velocity-aware prediction windows.
This section:
Checkpoint: Scenario Transfer
You now know:
- Range, delivery, cache freshness, battery distribution, and mobility prediction all change the routing answer.
- Multi-hop range planning trades a 2km single link for four 500m hops; social routing cuts epidemic-style 50+ copies down to 5-10 targeted copies when contact patterns help.
- Energy-aware selection can leave the weakest route at 25% battery instead of 0%, while mobility prediction reroutes around the -85 dBm failure point.
This section:
19.14 Common Misconception
This section: Common Misconception
19.15 Continue to Part 2
This section: Continue to Part 2 — Continue with Ad-Hoc Production: Routing Trade-offs.
Continue with Ad-Hoc Production: Routing Trade-offs.
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed