16 Edge Cyber-Foraging: Cost and Energy Calculations
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
16.1 Start With the Decision
This section: Start With the Decision — A 4K transcode can move heat and delay from a phone to a nearby server.
A 4K transcode can move heat and delay from a phone to a nearby server. Compare the local cost with the offload cost.
16.2 Route Overview
This section: Route Overview — This is part 2 of 2.
This is part 2 of 2. Review Edge Cyber-Foraging: Placement and Caching Decisions for the preceding evidence.
16.3 Learning Objectives
This section: Learning Objectives
- Test putting numbers to it with a concrete scenario and pass criteria.
- Validate test your understanding with a concrete scenario and pass criteria.
16.4 Chapter Roadmap
This section: Chapter Roadmap — Read Figure 16.1 from what to where to when.
- Putting Numbers to It
- Mobile Figure Summary: What/Where/When
- Scavenger System Architecture
- Mobile Figure Summary: Scavenger Flow
- Network Topology and Device Mix
- Mobile Figure Summary: Device Capability Ladder
- Virtualization vs Mobile Agents
- Edge Caching Strategies
- Mobile Figure Summary: Three-Tier Caching
- Putting Numbers to It
- Implementation Considerations
- Service Discovery
- Task Profiling
- See Also
- AR Navigation Offloading
- Interactive Quiz: Match Concepts
- Interactive Quiz: Sequence the Steps
- Label the Diagram
- Code Challenge
- Cyber-Foraging Offload Contracts
- Cyber-Foraging Offload Contracts
- Summary
- Key Takeaway
- Knowledge Check
- Test Your Understanding
- Quiz: Cyber-Foraging and Caching
- Concept Relationships
- What’s Next
- See Also
Consider a 4K video transcoding task (H.265 to H.264):
Local execution (smartphone):
Offload to nearby laptop (5 GHz Wi-Fi):
Result: Offloading saves 53% time (320 s to 149 s) and 92% battery (249 mAh to 18.7 mAh). This justifies the What/Where/When framework: offload CPU-heavy tasks to capable nearby devices when the network is fast.
An available surrogate is not automatically a safe offload target. The framework diagram in Figure 16.1 separates the three decisions that must be recorded before computation or data leaves the device.
Use the three columns in the diagram Figure 16.1 as distinct gates. What identifies the Data/computation and its sensitivity or compute burden; Where selects a Device/gateway with acceptable capability, latency, and trust; When applies the Trigger policy and How Long / TTL strategy. This order prevents a nearby node from winning merely because it is present. It also advances the cyber-foraging contract: record the task boundary, chosen surrogate, trigger, expiry, and failure fallback for every offloaded or cached result.
Read Figure 16.1 from what to where to when. First bound the task by compute cost, data sensitivity, and deadline; next choose only a surrogate whose capability, latency, and trust meet that boundary; finally trigger offload when battery, network, and urgency make the transfer worthwhile. The order matters because an available device is not automatically an acceptable destination. This connects cyber-foraging to the chapter’s running placement narrative: opportunistic compute remains a governed decision with explicit data and failure limits.
Mobile Figure Summary: What/Where/When
- Cyber-foraging: A mobile edge computing strategy where resource-constrained devices dynamically offload compute tasks to nearby, more powerful nodes (cloudlets, edge servers) discovered opportunistically on the local network.
- Cloudlet: A trusted, resource-rich compute node located close to mobile or IoT devices, providing low-latency offloading without the round-trip delay of a public cloud data centre.
- Task migration: The process of moving an in-progress computation from one node to another, requiring serialisation of the computation state and transfer of associated data.
- Offload decision algorithm: The logic determining whether to execute a task locally or offload it to a nearby node, typically based on task size, local battery level, network round-trip time, and available remote resources.
- Opportunistic networking: A communication paradigm where connections are established whenever nodes come within range of each other, without requiring persistent infrastructure, used to distribute processing in dense IoT environments.
Decision Framework:
| Question | Considerations | Example |
|---|---|---|
| WHAT? | Task characteristics (CPU/memory/network), data sensitivity, QoS requirements | Video transcoding is CPU-heavy but delay-tolerant — good candidate for offloading |
| WHERE? | Surrogate capabilities, network latency, reliability, trust | Nearby laptop has GPU — offload AR rendering; stranger’s device — avoid for private data |
| WHEN? | Task urgency, network conditions, battery state, surrogate availability | Battery <10% + Wi-Fi available + non-urgent task — offload immediately |
16.5 Scavenger System Architecture
This section: Scavenger System Architecture — The Scavenger system exemplifies cyber-foraging with a distributed architecture enabling mobile devices to discover and utilize nearby computational resources.
The Scavenger system exemplifies cyber-foraging with a distributed architecture enabling mobile devices to discover and utilize nearby computational resources. Use Figure 16.2 to trace the request across the trust and execution boundary before reading the component lists.
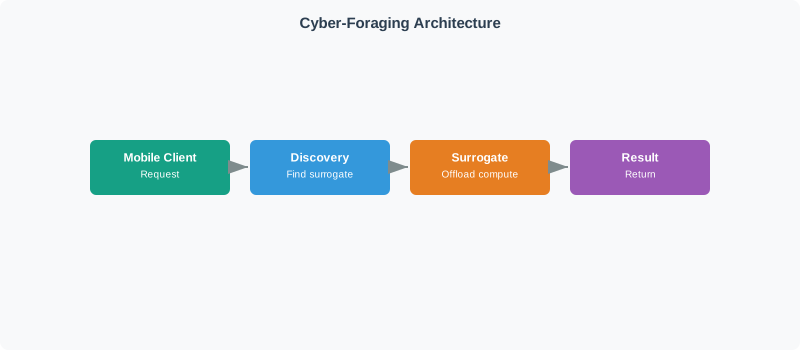
Follow Figure 16.2 from the application into the client library and RPC interface, across the network, and then through the surrogate frontend and IPC layer into sandboxed execution. The return path carries a result, but the boundary must also carry identity, task limits, errors, and provenance. Notice that discovery and selection happen before execution. That ordering advances the running narrative from abstract offload criteria to a concrete system in which capability checks, transport, isolation, and fallback must all support the same task claim.
Mobile Figure Summary: Scavenger Flow
- What: decide whether the data or computation is worth offloading.
- Where: choose a device or gateway based on capability, latency, and trust.
- When: trigger the offload or cache update when battery, urgency, and network conditions line up.
- How long: keep cached results only for an appropriate TTL.
Client-Side Components:
- Application Layer: User application (e.g., photo processing, video transcoding)
- Scavenger Library: Profiles tasks (CPU, memory, network requirements), discovers surrogates, selects optimal target
- RPC Interface: Serializes tasks, transmits to surrogate, receives results
Surrogate-Side Components:
- Frontend: Accepts incoming RPC requests from clients
- IPC Layer: Manages communication between frontend and execution environment
- Execution Environment: Sandboxed environment for running client tasks with resource limits
16.6 Network Topology and Device Mix
This section: Network Topology and Device Mix — Real-world cyber-foraging environments include diverse devices with varying capabilities.
Real-world cyber-foraging environments include diverse devices with varying capabilities. The topology diagram in Figure 16.3 makes that heterogeneity visible before a task is matched to a surrogate.
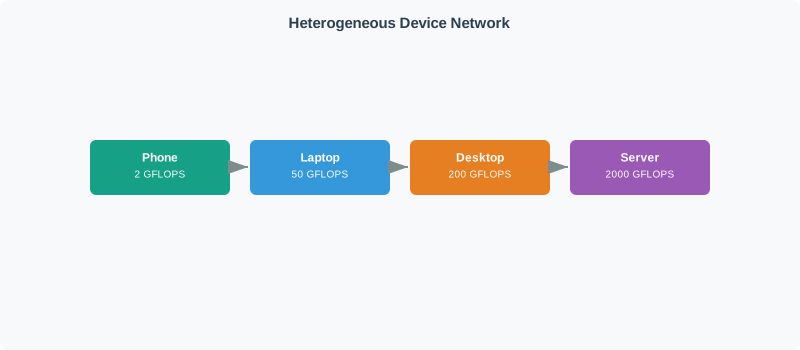
Read Figure 16.3 from the mobile client outward. Each candidate differs in compute, memory, acceleration, energy source, link quality, and trust; proximity alone does not make the phone, laptop, desktop, or gateway interchangeable. Compare the connection indicators with the capability labels, then identify which task constraint rules each candidate in or out. This continues the chapter’s running argument: cyber-foraging selection is a per-task evidence decision, and the chosen node must remain observable enough to detect departure or failure.
Mobile Figure Summary: Device Capability Ladder
- Frontend: Accepts incoming RPC requests from clients
- IPC Layer: Manages communication between frontend and execution environment
- Execution Environment: Sandboxed environment for running client tasks with resource limits
Device Capability Spectrum:
| Device Type | CPU | RAM | GPU | Battery | Network | Best For |
|---|---|---|---|---|---|---|
| Netbook (Client) | 1.6 GHz dual | 2 GB | Integrated | Limited | Wi-Fi | Lightweight tasks only |
| Laptop | 2.8 GHz quad | 16 GB | Integrated | Hours | Wi-Fi/LTE | CPU-bound tasks (compilation, compression) |
| Smartphone | 3.2 GHz hexa | 6 GB | 5-core GPU | Moderate | 5G/Wi-Fi | ML inference, image processing |
| IoT Gateway | 600 MHz ARM | 256 MB | None | Limited | 3G/Wi-Fi | Simple data processing |
| Desktop PC | 3.5 GHz 8-core | 32 GB | RTX 3080 | Unlimited | Gigabit | Video encoding, 3D rendering, ML training |
16.7 Virtualization vs Mobile Agents
This section: Virtualization vs Mobile Agents
Two primary approaches exist for implementing cyber-foraging, each with distinct trade-offs:
| Approach | Pros | Cons | Representative Systems |
|---|---|---|---|
| Virtualization | Strong isolation (sandboxing), no special software on client, standardized VM interfaces, security through hypervisor | VM spin-up delays (30—60 s), resource overhead (hypervisor), fixed VM sizes not adaptable to task | Cloudlets, MAUI, CloneCloud, ThinkAir |
| Mobile Agents | Dynamic deployment (code mobility), autonomous execution (detached operation), fine-grained adaptation to resources | Agent management complexity, security risks (code injection), heterogeneous runtime environments, debugging difficulty | Scavenger, Aglets, IBM Mobile Agents |
When to Use Each:
Virtualization (Cloudlets):
- Best for: Computation-intensive applications with graphical interfaces (AR, gaming, video editing)
- Scenario: Predictable workloads where VM startup time is amortized over long sessions (>5 minutes)
- Example: Mobile AR navigation app running on cloudlet VM for entire campus tour (30 minutes)
Mobile Agents (Scavenger):
- Best for: Short-lived tasks (<1 minute) on opportunistic, heterogeneous devices
- Scenario: Rapidly changing network topology (moving vehicles, crowded spaces)
- Example: Tourist photo processing — offload photo stitching to nearby laptop in coffee shop for 20 seconds, then move on
Hybrid Approach:
- Many modern systems use both: Cloudlets for persistent sessions + Mobile agents for quick offloads
- Example: Smartphone uses cloudlet for continuous AR, but offloads burst photo processing to nearby laptop via Scavenger
16.8 Edge Caching Strategies
This section: Edge Caching Strategies — The hierarchy diagram in Figure 16.4 shows why cache placement and freshness must be considered together before choosing a replacement policy.
Cyber-foraging and edge computing benefit from intelligent caching to minimize latency and bandwidth:
The hierarchy diagram in Figure 16.4 shows why cache placement and freshness must be considered together before choosing a replacement policy.
Cache Placement Hierarchy:
Inspect Figure 16.4 to ask which of the device, gateway, or cloud caches may safely answer a request with a reused result.
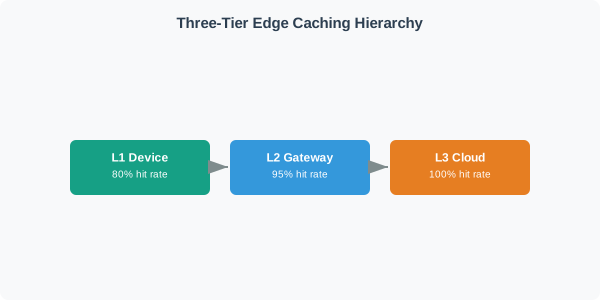
In Figure 16.4, a request checks the device cache first because it is nearest to demand. A miss moves to the gateway, and another miss reaches the broader cloud catalogue. The marked hit rates rise from 80% to 95% to 100%, but those percentages describe where an object is found, not whether it is fit to reuse. Read the validation note after each hit. Version, time to live, privacy scope, and invalidation state still have to match the current request. The useful design is therefore the nearest valid result, not simply the first stored copy returned by the hierarchy.
Trace Figure 16.4 from the device cache through the surrogate or access-point cache to the cloud or CDN. The nearest tier offers the lowest latency but the smallest, most local working set; the middle tier can share neighbourhood results; the cloud tier holds the broadest catalogue at the highest path cost. The hit-rate labels partition served requests rather than guaranteeing freshness. This connects caching to the running cyber-foraging narrative: place reusable work near demand, but carry version, TTL, privacy, and invalidation evidence with every cached result.
Mobile Figure Summary: Three-Tier Caching
- Many modern systems use both: Cloudlets for persistent sessions + Mobile agents for quick offloads
- Example: Smartphone uses cloudlet for continuous AR, but offloads burst photo processing to nearby laptop via Scavenger
Caching Policy Trade-offs:
| Policy | What to Cache | When to Update | Use Case |
|---|---|---|---|
| LRU (Least Recently Used) | Most recently accessed items | On access | General-purpose caching |
| LFU (Least Frequently Used) | Most frequently accessed items | Periodic count reset | Static content (maps, models) |
| TTL (Time-To-Live) | All items with expiration | After TTL expires | Dynamic data (sensor readings, weather) |
| Context-Aware | Items based on location/time/activity | On context change | Predictive prefetch (navigation routes) |
Real-World Example: Mobile Video Streaming
Scenario: User watches YouTube videos on phone while commuting

Tier 1 (Device):

- Recently watched videos cached locally (2 GB)
- Hit rate: 30% (rewatching favorite clips)


Tier 2 (Nearby Wi-Fi AP Cache):

- Popular videos in neighborhood cached on Wi-Fi router (500 GB)
- Hit rate: 40% (trending content)


Tier 3 (CDN/Cloud):

- All videos available from global CDN
- Hit rate: 30% (long-tail content)


Result: 70% of video traffic served from edge (Tier 1+2),
reducing cellular bandwidth by 5 GB/monthQuantify the bandwidth savings of three-tier caching for 10,000 apartment residents:
Without edge caching (all requests to cloud):
With three-tier caching (30% device, 40% AP cache, 30% cloud):
Savings: $1,200 - $360 = $840/month (70% reduction). Edge caching hardware (Wi-Fi AP with 2 TB SSD) costs $600 one-time — payback in 3 weeks.
16.9 Implementation Considerations
This section: Implementation Considerations
16.10 Service Discovery
This section: Service Discovery
Cyber-foraging requires efficient discovery of nearby surrogates:
# Example: mDNS-based surrogate discovery
import zeroconf

class SurrogateDiscovery:
    def __init__(self):
        self.zeroconf = zeroconf.Zeroconf()
        self.surrogates = {}

    def on_service_state_change(self, name, state):
        if state == "added":
            info = self.zeroconf.get_service_info(
                "_cyberforage._tcp.local.", name
            )
            self.surrogates[name] = {
                "address": info.parsed_addresses()[0],
                "port": info.port,
                "capabilities": info.properties,
            }

    def get_best_surrogate(self, task_requirements):
        """Select surrogate matching task needs."""
        for name, surrogate in self.surrogates.items():
            if self.matches_requirements(surrogate, task_requirements):
                return surrogate
        return None
16.11 Task Profiling
This section: Task Profiling
Effective offloading requires understanding task characteristics:
# Example: Task profiler for offloading decisions
class TaskProfile:
    def __init__(self, task):
        self.cpu_intensity = self.estimate_cpu(task)       # in cycles
        self.memory_requirement = self.estimate_memory(task)  # in bytes
        self.input_size = len(task.input_data)               # in bytes
        self.expected_output_size = self.estimate_output(task)
        self.deadline_ms = task.deadline

    def should_offload(self, local_cpu, surrogate_cpu,
                       network_bandwidth, network_latency):
        """Decide whether offloading benefits this task."""
        # CPU rates are cycles/s, bandwidth is B/s, and latency is seconds.
        local_time = self.cpu_intensity / local_cpu
        transfer_time = (
            (self.input_size + self.expected_output_size)
            / network_bandwidth
        )
        remote_time = (
            self.cpu_intensity / surrogate_cpu
            + transfer_time
            + network_latency * 2  # round-trip overhead
        )
        return remote_time < local_time and remote_time * 1000 < self.deadline_ms
16.12 See Also
- All videos available from global CDN
- Hit rate: 30% (long-tail content)
16.13 Illustrative Station AR Wayfinding
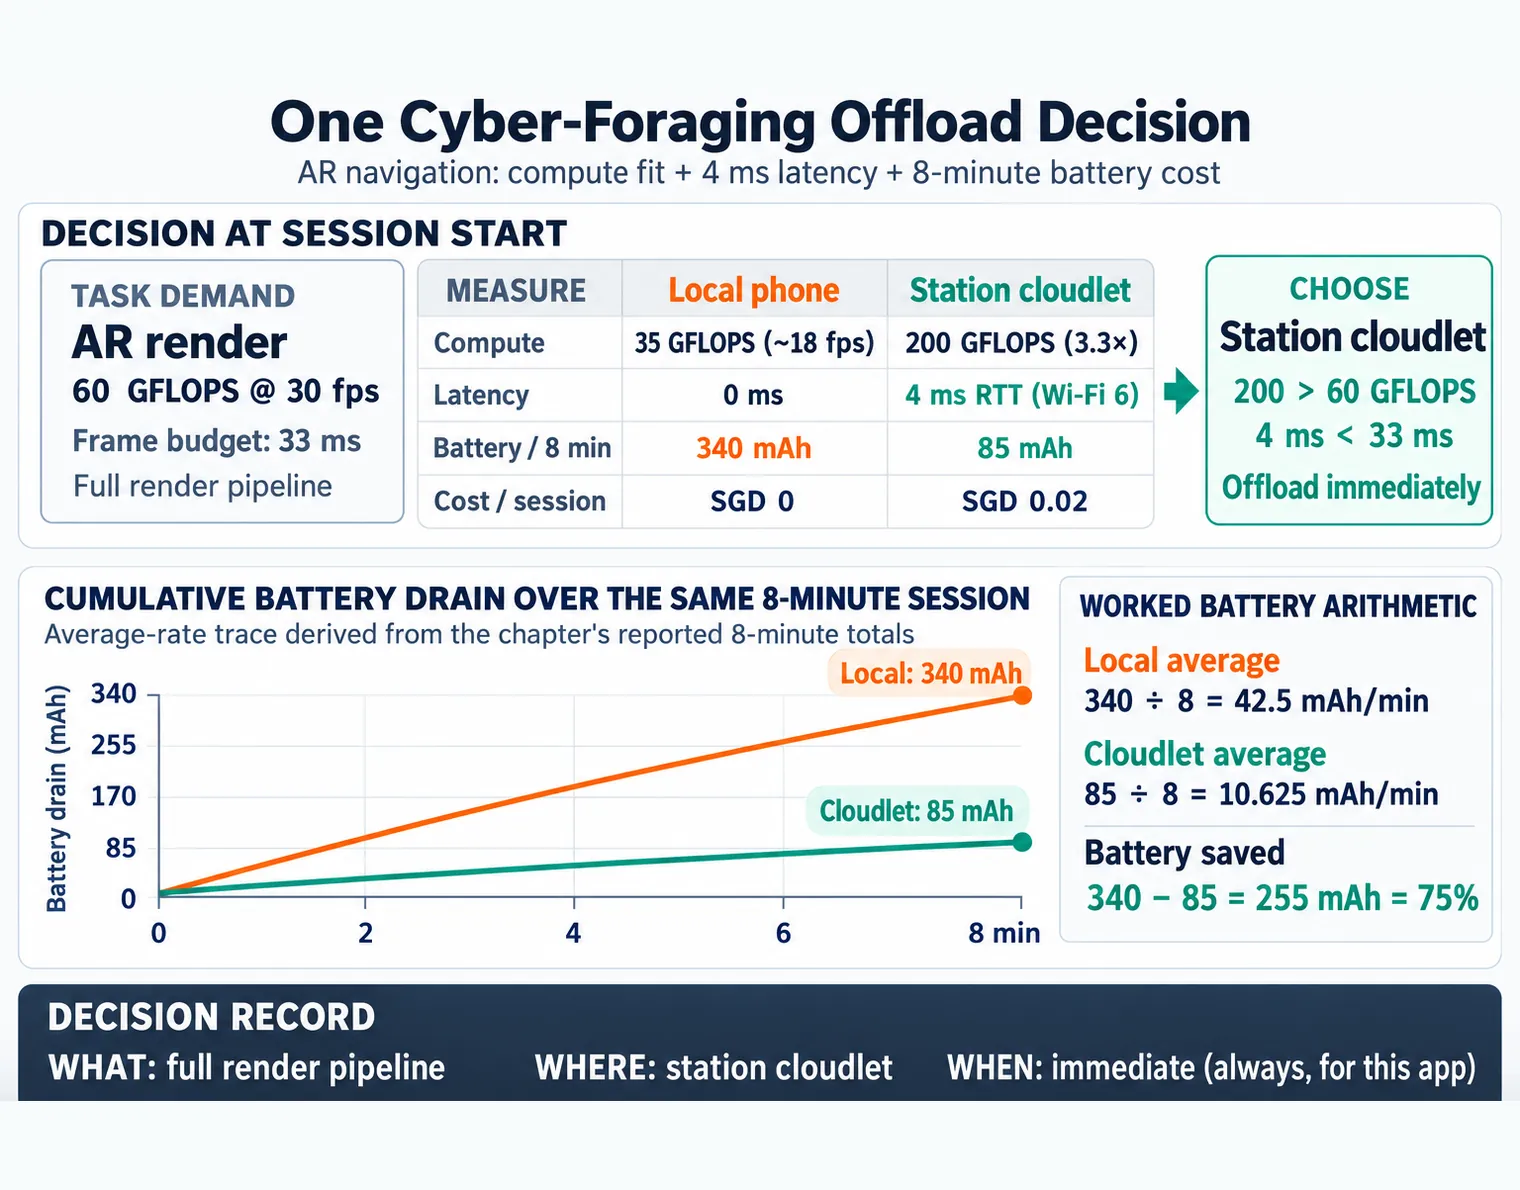
This section: Illustrative Station AR Wayfinding — Scenario: An illustrative station AR wayfinding app for visually impaired pedestrians renders 3D audio-visual overlays in real time, requiring GPU resources that exceed typical smartphone capabilities.
Scenario: An illustrative station AR wayfinding app for visually impaired pedestrians renders 3D audio-visual overlays in real time, requiring GPU resources that exceed typical smartphone capabilities.
Given:
- Smartphone GPU: Qualcomm Adreno 660, 35 GFLOPS sustained
- AR rendering demand: 60 GFLOPS at 30 fps for obstacle mesh + audio spatialization
- Station cloudlet: NVIDIA Jetson AGX Orin, 275 TOPS AI + 200 GFLOPS GPU
- Wi-Fi 6 latency to cloudlet: 4 ms round-trip
- 5G latency to cloud GPU instance: 22 ms round-trip
- Session duration: 8 minutes average (station entry to platform)
- Daily users: 1,200 visually impaired commuters across 40 stations
Step 1: Evaluate offloading options
| Option | Compute | Latency | Cost/Session | Battery Drain |
|---|---|---|---|---|
| Local only | 35 GFLOPS (insufficient, ~18 fps) | 0 ms | SGD 0 | 340 mAh (8 min full GPU) |
| Station cloudlet | 200 GFLOPS (3.3x headroom) | 4 ms | SGD 0.02 (amortized HW) | 85 mAh (Wi-Fi only) |
| Cloud GPU (5G) | Unlimited | 22 ms | SGD 0.18 (GPU-as-a-service) | 190 mAh (5G radio) |
Step 2: Apply What/Where/When framework
| Decision | Analysis | Choice |
|---|---|---|
| What to offload | AR mesh rendering (GPU-bound, 60 GFLOPS) + obstacle LIDAR processing | Full render pipeline |
| Where to offload | Cloudlet: 4 ms latency meets 33 ms frame budget; cloud: 22 ms too close to budget | Station cloudlet |
| When to offload | Battery <50% OR GPU thermal throttling OR >2 concurrent AR layers | Immediate (always, for this app) |
Step 3: Calculate system-wide economics
- Cloud compute cost = 1,200 users x 30 days x SGD 0.18/session = SGD 6,480/month
- Cloudlet compute cost = 1,200 x 30 x SGD 0.02 = SGD 720/month (amortized HW)
- Compute savings = SGD 6,480 - SGD 720 = SGD 5,760/month
For 40 stations at SGD 1,200 per cloudlet unit:
- Total hardware cost = 40 x SGD 1,200 = SGD 48,000
- Payback period = SGD 48,000 / SGD 5,760 per month ~= 8.3 months
Result for this illustrative station scenario: Station-deployed cloudlets deliver an assumed 30 fps AR navigation at 4 ms latency while reducing modeled battery drain by 75% compared with on-device rendering. The SGD 48,000 cloudlet investment pays for itself in about 8 months through eliminated cloud GPU costs, plus additional savings from reduced 5G data usage.
Key Insight: Cyber-foraging excels when the offloading environment is predictable. Train stations, airports, and hospitals have fixed infrastructure where cloudlets can be pre-positioned. The What/Where/When framework collapses to “always offload to the local cloudlet” when latency requirements are strict and surrogate availability is guaranteed.
16.14 Cyber-Foraging Offload Contracts
This section: Cyber-Foraging Offload Contracts — Cyber-foraging only works when the offload decision is measured instead of assumed.
Cyber-foraging only works when the offload decision is measured instead of assumed. Continue to Cyber-Foraging Offload Contracts for cloudlet break-even checks, cache freshness, privacy constraints, adaptive fallback, and decision-log evidence.
16.15 Cyber-Foraging Offload Contracts
This section: Cyber-Foraging Offload Contracts
16.15.1 Start With the Story
Borrow Nearby Computing Only When It Helps
Picture repair glasses that need a large image model. Running it on the glasses may drain the battery. Sending every image to a distant service may be too slow or fail when the outside link drops. A nearby site computer offers a third choice.
Offloading means sending a computing job to another machine. The runtime owner should compare the full trip: input size, send time, remote work, return size, energy, privacy, and the age of any saved result. Keep a safe local action when the borrowed machine is missing.
Test local work, nearby work, a saved answer, a stale answer, and a broken link. Record why each path was chosen and which software and data version produced the result.
Set a time and energy limit before the test. Use the same input for every path. Measure from the user’s request to the useful answer, including send and return time. A fast remote calculation can still lose once the travel time is counted.
Decide what the glasses do while waiting. They might show an older marked answer, run a smaller local check, or ask the worker to pause. The safe choice depends on the repair task. Record it before the outside machine becomes part of normal work.
Nearby is not always faster or safer. Practitioner writes the choice and fallback rules. Under the Hood examines discovery, transfer cost, caching, isolation, and scheduling.
An offload is useful when radio cost, result freshness, privacy, and fallback meet the named job better than local work.
16.15.2 Learning Objectives
After this page, you should be able to:
- Explain when a nearby cloudlet is a better target than local execution or a distant cloud.
- Compare local and offloaded execution using input size, result size, remote compute, radio energy, and latency.
- Specify cache metadata for freshness, source version, invalidation, and privacy scope.
- Record decision-log evidence for local execution, remote offload, cache hit, stale cache, and fallback paths.
16.15.3 Why Offload Follows Caching
Edge Cyber-Foraging and Caching introduces cloudlets, opportunistic offload, surrogate discovery, and hierarchical caching. This page turns those ideas into the contract a runtime scheduler needs: when to offload, when to stay local, when to serve from cache, and what evidence proves the choice was valid.
Use it when mobile, wearable, gateway, or field devices must borrow nearby compute without creating hidden battery, privacy, staleness, or availability failures.
16.15.4 Overview: Borrowing Compute From Nearby
Cyber foraging is the idea that a resource-poor device can borrow computing power from a nearby machine to do work it could not do alone. Rather than always computing locally (too slow, drains the battery) or always reaching the distant cloud (too far, too laggy), the device opportunistically offloads heavy tasks to a well-connected surrogate one hop away: a cloudlet.
The cloudlet gives cloud-like power with local-network latency, and caching results and models nearby avoids recomputing or refetching. But offloading is not always a win: whether to offload is a genuine calculation involving how much data must be shipped, how heavy the computation is, how much battery remains, and whether the answer is still useful after the network round trip.
Intuition: offloading is like handing a hard sum to a friend next to you instead of mailing it to an expert overseas. It helps only when the sum is hard enough to be worth handing over, and the friend is close enough to answer quickly.
Before applying offload to image and log work, inspect Figure 16.5 to ask when the full radio path uses less energy than local compute.
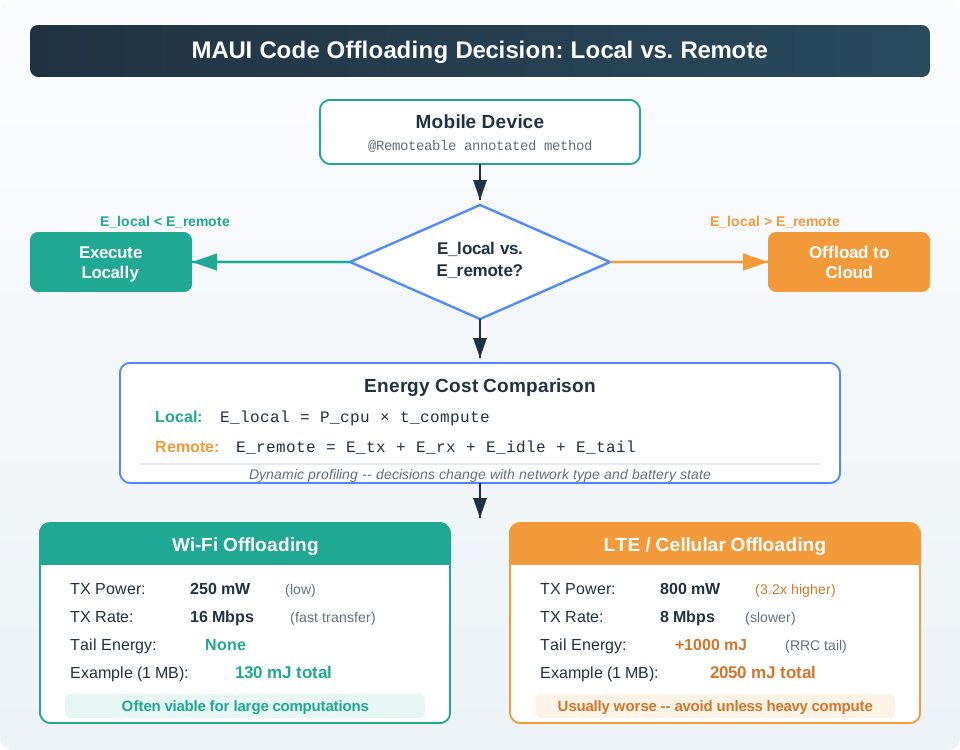
Start with the two energy ledgers in Figure 16.5. Local work costs processor power times compute time; remote work adds transmit, receive, idle, and radio-tail energy for the same task boundary. The branch chooses remote execution only when that total is lower, then checks deadline, privacy, and service availability. The paired 1 MB profiles show why the current link matters. One route costs 130 mJ, while the route with a long radio tail costs 2,050 mJ. Dividing 2,050 mJ by 130 mJ gives about 15.8, so an old offload decision cannot be reused after the network changes.
In practice, the device compares a local plan with a remote plan. The local plan spends CPU, memory, and battery on the device. The remote plan spends radio energy to send the input, remote compute time at the cloudlet, and radio energy to receive the answer. If the input is a 60 kB image and the result is a short label, offloading may be attractive. If the input is a 600 MB log and the local calculation is a simple average, offloading is usually wasteful. Caching improves the odds when the same model, map tile, inference result, or feature vector is likely to be reused soon.
16.15.5 Overview Knowledge Check
16.15.6 When Offloading Pays
Offloading helps only when shipping the work out and back beats doing it locally:
Offload if:  (send input) + (remote compute) + (receive result)
             <  (local compute)
Great candidates: heavy compute + small input/output
Poor candidates:  light compute + large input (shipping costs more
                  than just doing it locally)
Make that rule concrete with measurements rather than labels. Measure local execution time and energy for the task class. Measure uplink and downlink throughput on the current network. Estimate input bytes, output bytes, and any warm-up cost such as loading a model on the cloudlet. Then compare two budgets: local execution versus remote transfer plus remote execution. The offload decision can change minute by minute because Wi-Fi, cellular, battery state, and cloudlet load change.
Worked example: two tasks, two verdicts
Task A: run face recognition on one small image.
  input  = a small image (a few KB)
  output = a name (tiny)
  compute = heavy for a tiny device
  -> OFFLOAD: small data both ways, heavy compute saved. Win.

Task B: compute a simple average of a huge local log.
  input  = a large file (many MB)
  output = one number
  compute = trivial
  -> DO IT LOCALLY: uploading the file costs far more time and
     energy than the trivial computation would locally.
The pattern: offload compute-heavy, data-light tasks; keep data-heavy, compute-light tasks local. Caching then removes repeat work by storing the offloaded result or model at the edge so the next identical request is answered quickly.
A robust implementation also needs fallbacks. If discovery finds no trusted surrogate, the task must degrade to local mode, queue for later, or switch to a smaller model. If the surrogate is available but the cache entry is stale, refresh or recompute before serving the result. If the result contains private data, the policy may require local execution even when offloading is faster. The best path is therefore not only shortest latency; it is the path that meets latency, battery, privacy, and freshness constraints together.
16.15.7 Practitioner Knowledge Check
16.15.8 Energy, Networks, Staleness
The offload break-even equation has three terms on the remote side: energy and delay to send the input, cloudlet execution cost, and energy and delay to receive the result. A local-only path has CPU energy, memory pressure, heat, and user-visible delay. Offloading is beneficial only when the remote side is lower for the active constraint. A task may save battery but miss a latency deadline, or meet latency while violating a privacy rule.
Radio quality is the swing factor. On a strong Wi-Fi link, a few dozen kilobytes may be cheap enough that remote inference saves both time and energy. On a weak cellular link, retries, handshakes, tail energy, and low throughput can make the same offload worse than local execution. That is why cyber-foraging systems should profile the current path, not rely on a design-time assumption that “edge is always better.”
Caching adds another hidden variable: freshness. A cached model, map tile, or inference result is valuable because a cache hit costs almost no compute or network, but stale data can be wrong. Each cache entry needs metadata such as creation time, source version, time-to-live, invalidation rule, and privacy scope. For reusable tasks, the edge cache may be the difference between offloading once and paying the network cost on every request.
Privacy scope is part of the same control loop. A face embedding, location trace, or health feature vector may be cheap to offload, but policy can still require local execution, anonymisation, or a trusted surrogate. The scheduler should treat privacy, cache freshness, and link quality as first-class inputs rather than after-the-fact checks.
Energy break-even
On a battery device, offloading saves energy only if the radio energy to send the input is less than the local compute energy avoided. A weak or slow link can make offloading cost more energy than computing locally.
Why a cloudlet, not the cloud
The distant cloud's round trip is too slow for interactive offload. A one-hop cloudlet keeps latency low, which is exactly why cyber foraging targets nearby surrogates rather than remote data centres.
Decisions must be adaptive
Network quality and battery level change constantly, so the offload decision should be measured and made per task, not fixed at design time. The right choice this minute may be wrong the next.
Cached data goes stale
Cached results and models save work but can become outdated. Use time-to-live or invalidation so the edge does not serve a stale answer or run a superseded model.
So cyber foraging is a live cost-benefit calculation, not a fixed architecture: offload compute-heavy, data-light work to a nearby cloudlet when the network makes it cheaper in time and energy than computing locally, cache what you can to avoid repeats, and expire the cache so freshness is preserved. The decision log should record why a task ran locally or remotely: input size, result size, link estimate, battery state, cache hit or miss, privacy rule, and fallback path. Measured adaptively, it lets a small device punch far above its weight without pretending that every edge resource is always the right resource.
16.15.9 Under-the-Hood Knowledge Check
16.15.10 Release Checklist
Before shipping a cyber-foraging offload contract, verify these records:
- Each offloadable task records input size, result size, local execution time, local energy, remote execution time, and network transfer estimate.
- The scheduler measures current link quality and battery state before choosing local execution, cloudlet offload, delayed queue, or smaller-model fallback.
- Cache entries declare source version, creation time, time-to-live, invalidation rule, privacy scope, and whether stale results may be served.
- Trusted-surrogate policy says which cloudlets may run private data and what sandbox, attestation, or encryption boundary applies.
- Decision logs capture local/offload verdict, cache hit or miss, stale-cache handling, privacy override, fallback path, and operator-visible quality flag.
16.15.11 See Also
- Edge Cyber-Foraging and Caching for the broader offload, surrogate, and cache architecture.
- Edge Reference Model Placement Contracts for tier placement and evidence ownership.
- Edge Stream Window Contracts for bounded state and replay metadata behind edge summaries.
- Edge Patterns Practical Guide for worked placement decisions and calculators.
16.15.12 Next
Return to Edge Cyber-Foraging and Caching, then continue to Edge Patterns Practical Guide for interactive design tradeoffs.
16.16 Summary
This section: Summary
- Cyber-foraging enables mobile devices to opportunistically discover and offload computation to nearby surrogates
- The What/Where/When framework guides offloading decisions based on task characteristics, surrogate capabilities, and timing
- Scavenger architecture demonstrates client-server design with discovery, profiling, and execution components
- Virtualization vs mobile agents trade strong isolation (VMs) against deployment flexibility (agents)
- Three-tier caching places data at device, surrogate, and cloud levels for optimal access latency
- Caching policies (LRU, LFU, TTL, context-aware) match data characteristics to update strategies
- Service discovery (mDNS/Zeroconf) and task profiling enable intelligent offloading decisions
Cyber-foraging extends edge computing by allowing devices to scavenge nearby computational resources opportunistically. Use virtualization (cloudlets) for long sessions requiring strong isolation, and mobile agents for short-lived tasks on heterogeneous devices. In the chapter’s three-tier caching example (device, surrogate, cloud), the assumed hit rates serve 70% of traffic from the edge, reducing modeled backhaul volume.
16.17 Knowledge Check
This section: Knowledge Check
16.18 Concept Relationships
This section: Concept Relationships — Key Insight: Cyber-foraging excels when offload environment is predictable (train stations, airports with cloudlets).
Cyber-foraging extends edge computing by enabling opportunistic offloading to nearby devices:
Core Framework (This chapter):
- What/Where/When decision framework guides task offloading (CPU-heavy tasks to capable surrogates when battery low)
- Virtualization (cloudlets) vs mobile agents: strong isolation vs deployment flexibility trade-off
- In the chapter’s example, three-tier caching (device/surrogate/cloud) serves 70% of traffic from the edge, reducing modeled backhaul volume.
Edge Pattern Context:
- Edge Compute Patterns — Cyber-foraging is an advanced offloading pattern beyond basic filter/aggregate/infer
- Edge Processing Patterns — Infer pattern often offloads ML inference via cyber-foraging
Architectural Foundation:
- IoT Reference Model — Cyber-foraging operates at Level 3 (edge compute) leveraging nearby Level 4 (fog) resources
- Edge Fog Computing — Cloudlets are pre-positioned fog nodes; cyber-foraging discovers opportunistic fog resources
Practical Application:
- Edge Patterns Practical Guide — Latency calculator helps decide when offloading saves time vs network overhead
- Illustrative station AR navigation scenario: cloudlets deliver an assumed 30 fps at 4 ms latency and modeled 75% battery savings versus on-device rendering.
Data Acquisition Impact:
- Edge Data Acquisition — Cyber-foraging offloads processing but still requires edge data collection
- Edge Data Acquisition: Power and Gateways — Offloading reduces battery drain (85 mAh for Wi-Fi offload vs 340 mAh local GPU)
Key Insight: Cyber-foraging excels when offload environment is predictable (train stations, airports with cloudlets). Random opportunistic offloading (to stranger’s laptop) rarely works due to trust, discovery overhead, and availability uncertainty. In this illustrative station scenario, the What/Where/When framework selects the local cloudlet when latency requirements are strict and surrogate availability is guaranteed.
16.19 What’s Next
This section: What’s Next
| Next Topic | Description |
|---|---|
| Cyber-Foraging Offload Contracts | Cloudlet break-even checks, cache freshness, fallback, and decision-log evidence |
| Edge Patterns Practical Guide | Interactive tools, worked examples, and common pitfalls |
| Edge Data Acquisition | Data collection strategies at the edge |
Edge Pattern Series:
- Edge Compute Patterns — Core processing patterns overview
- IoT Reference Model — Seven-level architecture
- Edge Processing Patterns — Filter, aggregate, infer, store-forward
- Edge Patterns Practical Guide — Worked examples and tools
Architecture:
- Edge Fog Computing — Cloudlets and fog architecture
- Fog Architecture — Cloudlet VM synthesis details
Data Acquisition:
- Edge Data Acquisition — Collection strategies
- Edge Data Acquisition: Power and Gateways — Power management
16.20 Continue Your Route
This section: Continue Your Route — This is the last part of this chapter.
This is the last part of this chapter. Return to Edge Cyber-Foraging: Placement and Caching Decisions or continue from the analytics-ml module index.
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed