7 Edge Data: Semantic Compression and Pipelines
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
7.1 Start With the Situation
This section: Start With the Situation — A single rule for cutting samples may still send data the app does not need.
A single rule for cutting samples may still send data the app does not need. The team must say which events matter. It must measure what semantic compression removes, then check that the edge pipeline still supports the same decisions.
7.2 Overview
This section: Overview — This route moves from event extraction into algorithm selection, factory validation, and complete edge pipelines.
This route moves from event extraction into algorithm selection, factory validation, and complete edge pipelines.
This is part 2 of 2. Review Edge Data: Sampling and Statistical Compression when you need the first route.
7.3 Learning Objectives
This section: Learning Objectives
By the end of this chapter, you will be able to:
- design semantic event extraction
- select compression from evidence needs
- validate a multi-sensor edge pipeline
Highest compression, but requires domain knowledge:
from dataclasses import dataclass
from enum import Enum
from typing import Optional

class EventType(Enum):
    THRESHOLD_EXCEEDED = "threshold_exceeded"
    ANOMALY_DETECTED = "anomaly_detected"
    STATE_CHANGE = "state_change"
    PERIODIC_SUMMARY = "periodic_summary"

@dataclass
class SemanticEvent:
    timestamp: int
    device_id: str
    event_type: EventType
    value: float
    context: dict  # Additional info (threshold, previous state, etc.)

class SemanticCompressor:
    def __init__(self, device_id: str, threshold_high: float,
                 threshold_low: float, anomaly_std_factor: float = 3.0):
        self.device_id = device_id
        self.threshold_high = threshold_high
        self.threshold_low = threshold_low
        self.anomaly_std_factor = anomaly_std_factor
        self.history: list[float] = []
        self.last_state: Optional[str] = None
        self.summary_count = 0
        self.summary_sum = 0.0

    def process_sample(self, timestamp: int, value: float) -> list[SemanticEvent]:
        """
        Process a sample and return events (if any).
        Most samples produce NO events - that's the compression.
        """
        events = []

        # Update history for anomaly detection
        self.history.append(value)
        if len(self.history) > 100:
            self.history.pop(0)

        # Track for periodic summary
        self.summary_count += 1
        self.summary_sum += value

        # Check threshold crossing
        current_state = "normal"
        if value > self.threshold_high:
            current_state = "high"
        elif value < self.threshold_low:
            current_state = "low"

        if current_state != self.last_state and self.last_state is not None:
            events.append(SemanticEvent(
                timestamp=timestamp,
                device_id=self.device_id,
                event_type=EventType.STATE_CHANGE,
                value=value,
                context={
                    "previous_state": self.last_state,
                    "new_state": current_state
                }
            ))
        self.last_state = current_state

        # Check for statistical anomaly
        if len(self.history) >= 20:
            mean = sum(self.history) / len(self.history)
            std = (sum((x - mean)**2 for x in self.history) / len(self.history)) ** 0.5
            if std > 0 and abs(value - mean) > self.anomaly_std_factor * std:
                events.append(SemanticEvent(
                    timestamp=timestamp,
                    device_id=self.device_id,
                    event_type=EventType.ANOMALY_DETECTED,
                    value=value,
                    context={
                        "mean": mean,
                        "std": std,
                        "z_score": (value - mean) / std
                    }
                ))

        return events

    def get_periodic_summary(self, timestamp: int) -> SemanticEvent:
        """Call every N minutes to send a heartbeat/summary."""
        avg = self.summary_sum / self.summary_count if self.summary_count > 0 else 0
        event = SemanticEvent(
            timestamp=timestamp,
            device_id=self.device_id,
            event_type=EventType.PERIODIC_SUMMARY,
            value=avg,
            context={
                "sample_count": self.summary_count,
                "period_seconds": 300  # 5 minutes
            }
        )
        self.summary_count = 0
        self.summary_sum = 0.0
        return event

# Example: Temperature sensor, 1 sample/second
# Normal operation: 0 events per sample
# State change: 1 event (~100 bytes)
# 5-minute summary: 1 event (~80 bytes)
#
# Input: 300 samples x 8 bytes = 2400 bytes per 5 minutes
# Output: 1 summary + maybe 0-2 events = 80-280 bytes
# Compression ratio: 10:1 to 30:1 (varies by activity)When to use: Monitoring systems where “nothing happening” is the common case. Alarm systems, threshold monitoring, sparse event streams.
7.4 Algorithm Selection Decision Tree
This section: Algorithm Selection Decision Tree — The decision tree in Figure 7.1 turns the preceding methods into a selection sequence, beginning with what the signal and downstream decision are allowed to lose.
The decision tree in Figure 7.1 turns the preceding methods into a selection sequence, beginning with what the signal and downstream decision are allowed to lose.
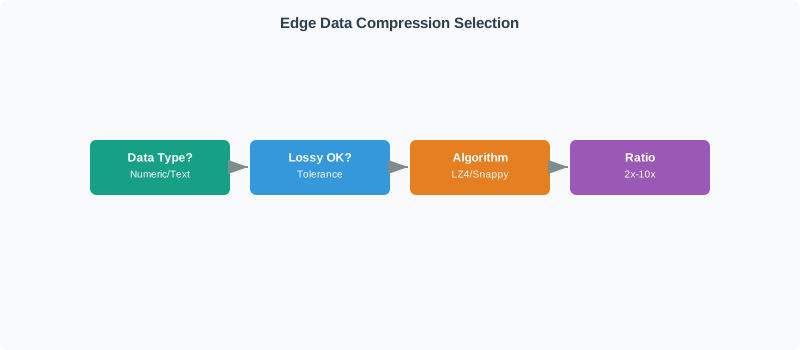
Read Figure 7.1 from signal type to fidelity requirement and only then to compute limits. Event-like data can often become sparse semantic records; smooth numeric streams may support delta or window summaries; spectral decisions may justify selected frequency features; audit-grade reconstruction keeps the route lossless. The final resource branch checks whether memory, latency, and energy fit the edge device. This connects the tree to the chapter’s running narrative: compression is an evidence contract chosen from the downstream claim, then tested against device constraints and reconstruction needs.
7.5 Benchmark Results: ESP32 Edge Device
This section: Benchmark Results: ESP32 Edge Device
Real measurements on ESP32-WROOM-32 (240 MHz, 520KB RAM):
7.6 Raw JSON
This section: Raw JSON
- 1000 samples: -
- Compress time: 15 ms (serialize)
- Output size: 28,000 bytes
- Power: 2.4 mJ
7.7 GZIP-6
This section: GZIP-6 — GZIP keeps the data lossless, so the smaller output can support exact reconstruction when decompression reproduces the source bytes.
GZIP keeps the data lossless, so the smaller output can support exact reconstruction when decompression reproduces the source bytes. The size reduction must be weighed against compression time, memory use, and total energy for computation plus transmission. A smaller payload alone does not establish an energy advantage; measure the same workload on the target device before choosing the algorithm.
- 1000 samples: 28,000 bytes
- Compress time: 85 ms
- Output size: 8,200 bytes
- Power: Measure on the target ESP32 for the same 1,000-sample workload
7.8 Window aggregation
This section: Window aggregation — Window aggregation replaces individual samples with summary values, preserving trends while discarding waveform and frequency detail.
Window aggregation replaces individual samples with summary values, preserving trends while discarding waveform and frequency detail. Its short compression time does not include the wait for a complete summary window. Choose the retained statistics from the downstream decision, and include sample count, window duration, and timestamp precision so the result can be interpreted. Measure computation and transmission energy together before comparing battery costs.
- 1000 samples: 8 bytes/sample
- Compress time: 2 ms
- Output size: 48 bytes
- Power: Measure on the target ESP32 for the same 1,000-sample workload
7.9 FFT Top-10
This section: FFT Top-10 — Selected FFT bins reduce the payload by retaining chosen frequency features rather than the full waveform.
Selected FFT bins reduce the payload by retaining chosen frequency features rather than the full waveform. This can support frequency-based decisions, but discarded bins and time detail cannot be recovered. Validate the selected features on representative traces before relying on them for fault detection. Include sample rate, window size, and transmitted bin identifiers so the receiver can interpret the output. Compare computation and transmission energy together when assessing the operating cost.
- 1000 samples: 4 bytes/sample
- Compress time: 45 ms
- Output size: 140 bytes
- Power: 5.0 mJ
7.10 Semantic
This section: Semantic — Key insight: For battery-powered edge devices, window aggregation offers the best power efficiency.
- 1000 samples: 8 bytes/sample
- Compress time: 3 ms
- Output size: 0-100 bytes
- Power: 0.5 mJ
Key insight: For battery-powered edge devices, window aggregation offers the best power efficiency. FFT is valuable when frequency content matters, but the CPU cost is significant. Semantic compression is ideal for sparse event streams.
7.11 Memory Constraints on Edge Devices
This section: Memory Constraints on Edge Devices — Compression algorithms have memory overhead.
Compression algorithms have memory overhead. Consider carefully on constrained devices:
| Algorithm | RAM Required | Notes |
|---|---|---|
| GZIP | 32-64 kB | Sliding window + Huffman tables |
| Window Agg | <1 kB | Just buffer for current window |
| FFT (1024 pt) | 16 kB | Complex float buffer + twiddle factors |
| FFT (4096 pt) | 64 kB | May not fit on small MCUs |
| Semantic | 2-4 kB | History buffer + state |
ESP32 recommendation: Use window aggregation or semantic compression as primary strategy. Reserve FFT for specific signals where frequency analysis is required.
7.12 Common Compression Pitfalls
This section: Common Compression Pitfalls
The Mistake: Applying high compression ratios uniformly across all sensor data without understanding which information is critical for downstream analytics, permanently destroying signals needed for root cause analysis.
Why It Happens: Bandwidth costs drive aggressive compression targets. Teams optimize for average case without considering anomaly detection requirements. Compression algorithms are chosen based on benchmark performance rather than domain-specific information preservation. The “we can always collect more data later” assumption fails for non-reproducible events.
The Fix: Profile your analytics requirements before choosing compression. For predictive maintenance, preserve frequency-domain information (use FFT compression, not just statistics). For threshold alerting, min/max preservation is critical. For trend analysis, mean and standard deviation suffice. Implement tiered compression: full resolution for anomalies detected locally, heavy compression for steady-state readings. Always retain enough information to answer “why did this alert trigger?” after the fact.
The Mistake: Compressing sensor data without preserving the metadata needed to decompress or interpret it correctly, creating files that cannot be decoded weeks or months later.
Why It Happens: Metadata seems redundant during development when context is fresh. Schema documentation is maintained separately and drifts over time. Edge device memory constraints pressure developers to strip every unnecessary byte. Compression parameters are hardcoded rather than embedded in output.
The Fix: Always include compression metadata in the payload or use self-describing formats. For FFT compression, include sample rate, window size, and which frequency bins are transmitted. For statistical aggregation, include sample count, window duration, and timestamp precision. Use envelope formats that version the compression scheme: {"compression": "fft-v2", "params": {...}, "data": [...]}. Maintain a compression schema registry that maps version identifiers to decompression algorithms.
The Mistake: Selecting compression algorithms based purely on compression ratio without accounting for CPU time and energy cost on battery-powered edge devices, resulting in net-negative energy savings.
Why It Happens: Compression benchmarks on desktop hardware show impressive ratios with negligible CPU time. The difference in computational efficiency between an ESP32 and a laptop can be substantial for compression workloads. Energy cost of computation versus transmission varies by network type (Wi-Fi is cheap to transmit, LoRa is expensive). Algorithm selection copied from cloud/server contexts.
The Fix: Measure end-to-end energy consumption: E_total = E_compute + E_transmit. For an illustrative LoRaWAN device where a transmission costs 100+ mJ per packet, aggressive compression can save energy if its compute cost is lower than the avoided radio energy. For an illustrative Wi-Fi device where transmission costs 1-5 mJ per packet, simple aggregation can beat complex compression if measured CPU energy exceeds the avoided radio energy. Measure GZIP and window-aggregation energy on the target ESP32 and the same 1,000-sample workload before choosing either algorithm. Choose based on total energy, not just bytes transmitted.
This section:
 Checkpoint: Match Compression to Evidence
You now know:
- Lossless compression preserves audit data, statistical aggregation preserves trends, FFT preserves frequency peaks, and semantic extraction preserves meaningful events.
- ESP32 limits matter: the benchmark section compares 520 kB RAM, GZIP state, FFT buffers, CPU time, and power rather than bytes alone.
- Compression metadata is part of the evidence path because a compact payload that cannot be decoded later is not trustworthy telemetry.
This section:
7.13 Industrial Edge Pipeline Check
This section: Industrial Edge Pipeline Check — The factory example turns the algorithm comparison into an operating choice: keep the frequency evidence, discard the raw waveform volume, and check latency against the maintenance requirement.
The factory example turns the algorithm comparison into an operating choice: keep the frequency evidence, discard the raw waveform volume, and check latency against the maintenance requirement.
Checkpoint: Factory Vibration Choice
You now know:
- The naive 50-sensor approach streams 500 Hz raw data into 129.6 GB per 30-day month, exceeding the 10 GB/month cap.
- Downsampling to 100 Hz cannot preserve components above 50 Hz; time-domain statistics discard waveform and frequency detail.
- FFT plus compression sends ten selected 16-bit magnitudes every 10 seconds: 500× payload reduction, or 250× including the example’s 20 B metadata, with total latency under the 1-minute requirement. Validate fault detection on representative traces.
Scenario: A manufacturing facility wants to examine illustrative shaft-order components on a motor running at 1800 RPM. These examples are possible indicators, not universal bearing-defect frequencies; actual BPFO/BPFI require bearing geometry.
Given:
- Motor speed: 1800 RPM = 30 Hz (revolutions per second)
- Illustrative shaft-order components: 1×: 30 Hz (can indicate imbalance); 2×: 60 Hz (can indicate misalignment); 3×: 90 Hz (can indicate looseness); 5×: 150 Hz; 7×: 210 Hz. These are example shaft harmonics, not universal bearing-defect frequencies. Actual BPFO/BPFI require bearing geometry.
- Highest illustrated component: 210 Hz (7th shaft order).
Question: What is the Nyquist minimum for the highest illustrated component, and what practical rate meets the example’s 2.5× margin?
Solution:
Step 1: Apply Nyquist theorem
Minimum sampling rate = 2 × highest frequency
f_sample_min = 2 × 210 Hz = 420 HzStep 2: Calculate practical sampling rate with safety margin
For this example, use 2.5x to 3x the Nyquist minimum as an anti-aliasing filter margin.
f_sample_recommended = 2.5 × 420 Hz = 1,050 Hz
f_sample_practical = 3 × 420 Hz = 1,260 Hz
Round up to a convenient rate that meets the stated 2.5× margin: 1,280 Hz.
Step 3: Check the below-target 1,000 Hz illustration
At 1,000 Hz, the Nyquist frequency is 500 Hz, above the illustrated 30–210 Hz components. This is above the Nyquist minimum but below the example’s 1,050 Hz practical target. Out-of-band input still requires adequate anti-aliasing filtering.
Step 4: Calculate data volume for the separate 1,000 Hz illustration
Single sensor:
- Sample rate: 1,000 Hz
- Data size: 2 bytes per sample (16-bit ADC)
- Data rate: 1,000 × 2 = 2,000 bytes/sec = 2 kB/sec
- Daily data: 2 kB/sec × 86,400 sec = 172.8 MB/day
For 100 motors:
- Daily data: 100 × 172.8 MB = 17.28 GB/day
- Monthly data: 17.28 × 30 = 518.4 GB/month
Step 5: Apply edge FFT compression to the separate 1,000 Hz illustration
Rather than stream raw waveforms to cloud:
# Pseudocode for edge processing every 10 seconds
import numpy

sample_rate_hz = 1000
window_s = 10
samples_per_window = sample_rate_hz * window_s  # 10000

# Perform FFT
fft_result = numpy.fft.rfft(samples)  # 5001 complex bins

# Extract illustrative shaft-order bins
illustrative_freqs_hz = [30, 60, 90, 150, 210]
bin_width = sample_rate_hz / samples_per_window  # 0.1 Hz
selected_bins = [int(f / bin_width) for f in illustrative_freqs_hz]
# Result: bins [300, 600, 900, 1500, 2100]

# Pseudocode: quantize five calibrated magnitudes to uint16, with declared scale,
# saturation handling, and receiver metadata for the selected frequencies.
calibrated_range = ...
magnitudes_u16 = quantize_to_uint16(
    [abs(fft_result[b]) for b in selected_bins], calibrated_range
)
compressed_data = serialize_uint16_with_metadata(
    magnitudes_u16, illustrative_freqs_hz, calibrated_range
)
payload_bytes = len(magnitudes_u16) * 2  # 10 bytes, excluding framing/metadata
compression_ratio = (samples_per_window * 2) / payload_bytes  # 2000x by payload bytes
Step 6: Calculate bandwidth savings
Without compression:
- 100 motors × 0.1728 GB/day per motor = 17.28 GB/day
With edge FFT compression (2,000x, assuming five calibrated 16-bit magnitude bins per 10-second window):
- 17.28 GB/day / 2,000 = 0.00864 GB/day = 8.64 MB/day
Cost savings:
- Cloud ingress: $0.09/GB (exercise assumption)
- Uncompressed: 17.28 GB/day × $0.09/GB = $1.56/day = about $568/year
- Compressed: 0.00864 GB/day × $0.09/GB = $0.00078/day = about $0.28/year
- Savings: about $567/year, excluding framing, storage, and processing costs
Key Insight: Sample above the Nyquist minimum with room for anti-aliasing filter roll-off; 2.5–3× the Nyquist rate is a useful starting margin for this example, subject to filter design. Sending selected FFT bins greatly reduces payload while retaining those selected spectral features. Validate fault detection on representative traces because discarded bins and time-domain detail cannot be recovered. The edge gateway computes the features; the cloud receives the chosen diagnostic values.
Choose the appropriate compression strategy based on signal characteristics, edge compute capabilities, and analytical requirements:
| Signal Type | Recommended Compression | Typical Ratio | Edge CPU | Bandwidth | Information Loss | Best For |
|---|---|---|---|---|---|---|
| Slowly changing continuous (temperature, humidity) | Statistical aggregation (min/max/mean/std) | 100-1000x | Very Low (1% CPU) | 99%+ reduction | Loses individual samples, keeps trends | Environmental monitoring, agriculture |
| Periodic vibration (motors, pumps) | FFT + top-N frequency bins | 100-5000x | High (50% CPU) | 99%+ reduction | Loses waveform, keeps frequency spectrum | Predictive maintenance, bearing analysis |
| Event-driven sparse (motion, door switches) | Event logging (timestamp + state change only) | 1000-10000x | Very Low | 99.9%+ reduction | Loses “no event” periods (acceptable) | Security, occupancy, access control |
| High-frequency transient (acoustics, ultrasound) | Triggered capture + FFT | 50-500x | High | 98%+ reduction | Loses non-trigger periods | Leak detection, acoustic monitoring |
| Bounded range analog (pressure, flow) | Delta encoding + GZIP | 3-10x | Medium (10% CPU) | 70-90% reduction | None (lossless) | Critical measurements requiring full fidelity |
| Audit trail / compliance (access logs, alarms) | GZIP compression only | 2-5x | Low (5% CPU) | 50-80% reduction | None (lossless) | Regulatory compliance, security logs |
Decision Tree:
Read the tree from information requirements toward implementation cost. Start by asking whether silence itself carries meaning or whether only state changes matter; event logging is appropriate only when the application can interpret the gaps correctly. Next decide whether audit or diagnostic work requires the exact waveform. If it does, keep the transformation lossless and prove that decompression reproduces the source bytes. If a lossy representation is acceptable, inspect the signal: stable frequency components can support FFT features, slow trends can support window statistics, and bounded low-variance values can support delta encoding. At each branch, measure edge CPU and memory cost, reconstructed or retained information, output rate, and end-to-end latency on representative data. Keep a raw review window and a versioned compression rule so that a model or threshold change can be audited. The ratios in the comparison table are illustrative workload ranges, not guarantees for a new sensor stream.
-
is the signal event-driven (state changes only)?
- YES → Use event logging (transmit only state changes)
- NO → Continue to step 2
-
do you need to preserve the exact waveform for audit/compliance?
- YES → Use lossless compression only (GZIP, DEFLATE)
- NO → Continue to step 3
-
does the signal have strong frequency-domain features?
- YES (vibration, acoustics) → Use FFT + top-N bins
- NO → Continue to step 4
-
is the signal slowly changing (< 1% per sample)?
- YES → Use statistical aggregation over time windows
- NO → Continue to step 5
-
is the signal bounded with low variance?
- YES → Use delta encoding + lossless compression
- NO → Use adaptive sampling rate based on rate-of-change
Example: Multi-Sensor System with Different Compression Strategies:
class EdgeCompressionPipeline:
    def __init__(self):
        self.strategies = {
            'temperature': StatisticalAggregator(window_sec=300),    # 5-min windows
            'vibration': FFTCompressor(top_n=10, window_sec=10),     # Top 10 freq bins
            'motion': EventLogger(),                                 # State changes only
            'pressure': DeltaEncoder() + GZIPCompressor(),           # Lossless delta
            'door': EventLogger(),                                   # State changes only
        }

    def compress_sensor_data(self, sensor_id, raw_samples):
        sensor_type = self.get_sensor_type(sensor_id)
        strategy = self.strategies[sensor_type]
        return strategy.compress(raw_samples)

# Usage example:
pipeline = EdgeCompressionPipeline()

# Temperature: 300 samples → 4 summary values (min/max/mean/std)
temp_compressed = pipeline.compress_sensor_data("temp_01", temp_samples)
# Compression: 300 samples × 2 bytes = 600 bytes → 16 bytes (4 floats)
# Ratio: 37.5x

# Vibration: 10,000 samples → 10 FFT bins
vib_compressed = pipeline.compress_sensor_data("vib_01", vib_samples)
# Compression: 10,000 × 2 bytes = 20 KB → 40 bytes (10 complex floats)
# Ratio: 500x

# Motion: 1000 samples (mostly "no motion") → 3 events ("motion detected" at 3 timestamps)
motion_compressed = pipeline.compress_sensor_data("motion_01", motion_samples)
# Compression: 1000 × 1 byte = 1 KB → 24 bytes (3 events × 8 bytes each)
# Ratio: 42xBuffer Sizing for Each Strategy:
| Strategy | RAM Required (per sensor) | Latency Added | Notes |
|---|---|---|---|
| Statistical Aggregation | 1-2 kB (circular buffer) | 5-60 seconds (window duration) | Minimal memory, acceptable latency |
| FFT Compression | 16-64 kB (FFT working memory) | 1-10 seconds (FFT window) | High memory, fast processing |
| Event Logging | < 1 kB (state machine) | None (immediate) | Minimal resources, real-time |
| Delta Encoding | 4-8 kB (recent history) | < 1 second | Low memory, minimal latency |
Verification Checklist:
- Compression ratio measured on representative data (not just ideal cases)
- CPU usage stays under 60% during peak sensor activity
- RAM usage leaves 30%+ margin for bursts
- Decompression/reconstruction tested to verify information preservation
- Bandwidth reduction measured end-to-end (including protocol overhead)
The Mistake: Sampling vibration data at only 2× the motor’s fundamental frequency can miss higher illustrative shaft-order components. These shaft harmonics are not universal bearing-defect frequencies; actual BPFO/BPFI require bearing geometry.
Illustrative Example: A factory exercise uses 100 Hz sampling on 30 Hz shafts (thinking “2× shaft speed is enough”) and examines a hypothetical 5× shaft-order component:
Shaft: 30 Hz
Illustrative 5× shaft-order component: 5 × 30 = 150 Hz

At 100 Hz sampling:
- Nyquist = 50 Hz
- 150 Hz aliases to |150 - round(150/100) × 100| = |150 - 200| = 50 Hz
- At exactly the Nyquist frequency, the signal is severely distorted

The illustrative component appears at the Nyquist boundary and cannot be reliably resolved.
Use this as a sampling exercise, not a bearing-failure prediction.
Correct Implementation:
def calculate_illustrative_shaft_order_rate(motor_rpm, highest_shaft_order=7):
    """
    Calculate a sampling example for an explicitly chosen shaft order.
    This does not predict bearing-defect frequencies.
    """
    motor_hz = motor_rpm / 60
    highest_frequency = motor_hz * highest_shaft_order

    # Safety factor: 3x Nyquist for anti-aliasing filter
    recommended_rate = 3 * 2 * highest_frequency

    return {
        'motor_hz': motor_hz,
        'highest_illustrated_component_hz': highest_frequency,
        'nyquist_min': 2 * highest_frequency,
        'recommended': recommended_rate,
    }

# Example usage:
rate_info = calculate_illustrative_shaft_order_rate(motor_rpm=1800, highest_shaft_order=7)
# Shaft: 30 Hz | Highest illustrative component: 210 HzWarning Signs: If an FFT shows only the shaft fundamental, check whether filtering or selected-bin upload hid harmonics. Compare the full spectrum and bearing defect frequencies derived from bearing geometry and shaft speed before diagnosing a bearing fault.
Prevention: Define the components of interest from representative traces and bearing geometry where defect frequencies are needed. Sample above the Nyquist minimum with room for anti-aliasing filter roll-off, and validate any selected-bin detector because discarded bins and time detail cannot be recovered.
7.20 Knowledge Check
This section: Knowledge Check
7.21 Practice Exercises
This section: Practice Exercises
Objective: Determine optimal sampling rates for different sensor types.
Tasks:
- Identify signal characteristics for 4 sensors: temperature (max 0.1 Hz), vibration (max 500 Hz), audio (max 20 kHz), motion IMU (max 50 Hz)
- Apply Nyquist theorem: calculate minimum sampling rates
- Implement with margin and measure data rate impact
Expected Outcome: Understand the relationship between signal bandwidth and sampling requirements.
Objective: Implement multiple data reduction techniques and compare bandwidth savings.
Tasks:
- Collect 1-minute of high-rate sensor data (100 Hz = 6,000 samples)
- Apply 4 reduction strategies: downsampling, statistical aggregation, delta encoding, event-based
- Transmit reduced data and compare bandwidth
- Validate: can you detect a 1C temperature spike with each method?
Expected Outcome: Understand trade-offs between compression ratio and information preservation.
This section:
Checkpoint: Ready to Apply
You now know:
- The remaining quizzes ask you to calculate sample rates, select memory-feasible compression, match concepts, order the workflow, label the pipeline, and complete aggregation code.
- The practice tasks keep the same evidence rule: sample high enough first, then reduce only in ways that preserve the analysis goal.
- The next audit page extends this chapter into lossless time-series boundaries when exact reconstruction becomes the requirement.
This section:
This section:
Always sample at 2x or higher than the highest frequency of interest (Nyquist theorem) to avoid aliasing artifacts. Then apply edge data reduction — aggregation for slow-changing signals, FFT compression for vibration analysis, or semantic event extraction for sparse event streams — which in these illustrative workload examples reduces bandwidth by 10-1000x while preserving the information needed for downstream analytics.
This section:
This section:
This section:
This section:
This section:
This section:
This section:
Semantic compression narrated tour
Narrated audio tour. The full transcript is below.
Play the tour to open the simulator. Pause, replay a beat, or read the full transcript below.
Some beats explain situations this teaching model cannot show; those beats keep the existing frame and provide captions only.
Full transcript — Semantic compression (8 beats)
B1 — Preserve evidence
You are choosing what a temperature sensor sends to an alerting service. Sending fewer readings sounds useful, but losing the temperature peak could leave an alert unexplained. Your job is to reduce the data while preserving the evidence the service needs.
Model caption: You need enough temperature evidence to explain an alert after reducing the data.
B2 — Semantic rule
Semantic compression means keeping information according to its meaning for the application. In the chapter's temperature example, normal readings produce no events. A change between normal and high temperature produces an event. A periodic summary carries an average, rather than every individual reading.
Model caption: Chapter semantic rule: normal readings produce no events; state changes produce events; periodic summaries retain an average.
B3 — Chapter byte estimate
Take five minutes at one reading per second. Three hundred readings, at eight bytes each, make two thousand four hundred bytes. Suppose no state changes occur. The chapter estimates about eighty bytes for the summary. Dividing two thousand four hundred by eighty gives a reduction by a factor of about thirty.
Model caption: Chapter estimate, no state changes: 300 readings × 8 bytes = 2,400 bytes; about 80 summary bytes; 2,400 ÷ 80 ≈ 30-fold reduction.
B4 — Deadband comparison
The savings come with a change in evidence: an average replaces individual temperatures. To understand what reducing a stream can discard, compare two simpler rules in the temperature model. Neither rule decides which temperature events matter to your alerting service.
Model caption: Deadband reduces the temperature stream by a numerical tolerance; it does not identify meaningful alert events.
B5 — Held reconstruction
Deadband sends a value when its difference from the last sent value reaches a chosen tolerance. At a quarter of a degree Celsius, a change of at least a quarter degree triggers another transmission. Between transmissions, reconstruction holds the last sent value. The model also sends the first and final readings.
Model caption: Send the first and final readings, and readings differing from the last sent value by at least 0.25 °C. Hold the latest sent value between transmissions.
B6 — Window averages
Window averaging works differently. With four readings per window, it replaces all four temperatures with their average. Individual peaks disappear into the summary. Maximum reconstruction error means the largest absolute difference between an original temperature and its reconstructed value, compared at the same sample.
Model caption: Each group of four temperatures becomes its average. Maximum error is the largest absolute original-to-reconstruction difference at a matching sample.
B7 — Alert evidence
The misconception is that a small reconstruction error guarantees safe alerting. Error measures a difference in temperature; it does not establish whether an alert threshold crossing survives. Even a small difference can matter at a threshold. The chapter calls for preserving minimum and maximum values for threshold alerts.
Model caption: Small reconstruction error alone does not establish alert safety. Threshold alerting needs minimum and maximum evidence.
B8 — Decision and savings
Keep the evidence your decision needs, then count the bytes you saved.
Model caption: Keep the evidence your decision needs, then count the bytes you saved.
7.22 Time-Series Compression Audit
This section: Time-Series Compression Audit — The body above covers Nyquist sampling, aggregation, FFT compression, semantic extraction, and edge algorithm selection.
The body above covers Nyquist sampling, aggregation, FFT compression, semantic extraction, and edge algorithm selection. Continue to Time-Series Compression and Audit Boundaries when you need the deeper L2 material: delta and delta-of-delta encoders, Gorilla-style XOR compression, columnar layout, lossless-vs-lossy evidence boundaries, and compression metadata required for audit-grade reconstruction.
See how a pasture-monitoring question changes where bytes are processed in the diagram Figure 7.2.

In the diagram Figure 7.2, cow-collar motion moves from Measure the raw stream through Fog extracts motion evidence to Cloud compares the herd. The Keep raw windows around anomalies note makes the bargain explicit: compact events travel, while selected waveform evidence remains available for audit.
Before choosing a reducer, price the unreduced six-axis feed with the diagram Figure 7.3.

Work across Figure 7.3 one unit at a time. Six axes at 2 bytes per axis make a 12-byte frame. At 100 frames per second, that is 12 B/frame x 100 frames/s = 1,200 B/s. Multiplying by 60 s/min gives 72,000 B/min; extending through 60 min/h and 24 h/day gives 103,680,000 B/day, or 103.68 MB/day before timestamps and identifiers. Now read the evidence warning. Downsampling may miss short hoof-strike peaks, while event extraction keeps counts but discards waveform shape. Those losses support different claims, so byte savings alone cannot choose the reducer.
Use the diagram Figure 7.4 when the design review must decide which motion claim is worth transmitting.

In the diagram Figure 7.4, the RAW / 5 HZ lane retains Waveform evidence at a measurable radio cost; the TILT / CHANGE lane retains State evidence and reports on change only. The shared Same ID and clock premise prevents a misleading comparison between differently described records.
Scale the sampling policy across the estate before assigning storage tiers in the diagram Figure 7.5.

In the diagram Figure 7.5, the sequence One sensor → gateway, Five sensors × 100 fog nodes, and Downsample at fog exposes the jump from 17.28 MB/day to 8.64 GB/day and the reduction to 14.4 MB/day. Its retention panel separates a short replay buffer from ninety-day trends and an explicitly authorized long hold.
7.23 Summary
This section: Summary
Edge data acquisition requires careful balance between data fidelity and resource constraints:
- Nyquist compliance: Sample at 2x or higher than your highest frequency of interest to avoid aliasing
- Reduction techniques: Aggregation (10-50x), FFT compression (50-500x), and semantic extraction (100-1000x) each serve different use cases
- Algorithm selection: Match compression to downstream analytics needs - lossless for audit, statistical for trends, FFT for vibration, semantic for events
- Resource awareness: Consider CPU time and memory on constrained edge devices, not just compression ratio
7.24 Concept Relationships
This section: Concept Relationships — Key Insight: Compression algorithm selection depends on analytics requirements, not just compression ratio.
Sampling and compression determine data fidelity, bandwidth, and power consumption trade-offs:
Sampling Theory (This chapter):
- Nyquist theorem: sample at 2x highest frequency to avoid aliasing (vibration monitoring: sample at 2.5-3x Nyquist for anti-aliasing filter)
- Under-sampling can cause phantom patterns (an illustrative 150 Hz shaft-order component aliases when sampled below its Nyquist minimum)
Compression Strategies (This chapter):
- Lossless (GZIP): 2-4x reduction, preserves all data (audit trails, compliance)
- Lossy statistical (aggregation): 10-100x reduction, preserves trends (environmental monitoring)
- In the illustrative workload comparison, FFT-based: 50-500x reduction, preserves selected frequency components (vibration analysis).
- Semantic (event extraction): 100-1000x reduction, preserves state changes (threshold monitoring)
Power Impact:
- Edge Data Acquisition: Power and Gateways - Aggregation reduces transmission frequency and can extend battery life (illustrative factory case: 14,400x record-count reduction makes LoRa feasible versus the assumed cellular schedule).
Architecture Context:
- Edge Data Acquisition: Architecture - Device category determines compression need (cameras need heavy compression; temperature sensors need aggregation)
- Edge Compute Patterns - Edge ML requires compressed features (FFT bins, not raw waveforms)
Data Quality:
- data Quality and Preprocessing - Validation must occur before compression (compressing invalid data wastes resources)
Key Insight: Compression algorithm selection depends on analytics requirements, not just compression ratio. Vibration monitoring can use FFT features selected from representative traces; validate their fault-detection performance because discarded bins and time detail cannot be recovered. Choosing a compression method without checking the required evidence can permanently discard signal details needed for analysis.
7.25 What’s Next
This section: What’s Next
- Understand the acquisition architecture that applies these strategies: Edge Acquisition Architecture
- Dig deeper into lossless time-series compression audits: Time-Series Compression and Audit Boundaries
- Learn about power management for low-duty-cycle sampling: Edge Acquisition Power and Gateways
- Study edge compute patterns built on efficient sampling: Edge Compute Patterns
- Apply to the broader edge data acquisition context: Edge Data Acquisition
- Return to the module overview: Big Data Overview
Edge Acquisition Series:
- Edge Data Acquisition: Architecture - Device categories and data generation patterns
- Edge Data Acquisition: Power and Gateways - Power management and gateway functions
Processing Context:
- Edge Compute Patterns - Processing patterns at the edge
- Multi-Sensor Data Fusion - Combining compressed sensor data
Data Quality:
- data Quality and Preprocessing - Validation before compression
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed