17 Sensor Processing: Sampling and Signals
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
17.1 Start With the Decision
This section: Start With the Decision — A clean chart can hide aliasing, clipping, or lost detail.
A clean chart can hide aliasing, clipping, or lost detail. Sensor processing starts with the signal band, sample rate, and step size.
17.2 Route Overview
This section: Route Overview — This is part 1 of 2.
This is part 1 of 2. Continue with Sensor Processing: Filter Selection and Validation.
17.3 Part Objectives
This section: Part Objectives
- Choose sample rate and resolution from signal limits.
- Detect aliasing, quantization, clipping, and noise.
17.4 Start With the Measurement Story
This section: Start With the Measurement Story — An analog-to-digital converter is a part that turns a voltage into a number.
Keep the Raw Reading Beside the Claim
An analog-to-digital converter is a part that turns a voltage into a number. It is often called an ADC. Bandwidth is the range of change a signal or link can carry. Picture a cold-room sensor that jumps once when a motor starts. Smoothing may hide the jump, but it may also hide a real door-open event.
Write the physical claim before choosing a data step. Record units, valid range, expected speed of change, sample time, and known sources of noise. Keep the raw value, quality state, and corrected value together so a reviewer can trace the result.
Test steady input, a real fast change, a single false spike, a missing sample, and a shifted reference. Change the order of checks only when the evidence supports it. Reject bad input before it can pull later values away from truth.
No filter can recover facts that were never measured. The deeper sections compare smoothing, middle-value checks, calibration, and stored settings. They show which fault each method can reduce and which limit must remain visible.
A reading becomes information only after noise, drift, outliers, scaling, and timing are handled. Start with the claim the processed value must support, then choose the smallest processing step that makes that claim reliable.
Keep one concrete record beside the chapter: name the raw observable and units, expected physical bandwidth, valid range, sample interval, known interference, and the decision threshold that consumes the result. A median filter is defensible when rare spikes are impossible physical events; a moving average is defensible when uncorrelated jitter is faster than the real process; calibration is required when a stable bias or scale error remains. Record the order too, because rejecting an invalid sample before smoothing is not equivalent to averaging it into later values, and converting ADC counts into engineering units before the reference is known only gives a more polished wrong number. Each later method should be justified against this same measurement story.
- Start With the Measurement Story
- In 60 Seconds
- Prerequisites
- Key Concepts
- Quick Check: Processing Purpose
- Introduction
- Sensor Data Processing
- Making Sensors Tell Truth
- Moving Average Noise Reduction
- Checkpoint: Measurement Meaning
- Filtering Noisy Sensor Data
- Folded Sampling And Aliasing Notes
- Phoebe’s Field Notes: Where Vibration Nyquist Meets the Sensor’s Own Step Size
17.5 Learning Objectives
This section: Learning Objectives
By the end of this chapter, you will be able to:
- Implement and compare moving average, Kalman, and median filters to reduce sensor noise
- Execute two-point calibration procedures to correct sensor offset and gain errors
- Design data validation pipelines that detect anomalies and reject outliers
- Select and justify appropriate filtering strategies based on signal characteristics and resource constraints
- Persist calibration coefficients in EEPROM and restore them reliably across power cycles
17.6 In 60 Seconds
This section: In 60 Seconds
17.7 Prerequisites
This section: Prerequisites
Before diving into this chapter, you should be familiar with:
- Sensor Fundamentals: Understanding of sensor types and output characteristics
- ADC Fundamentals: How analog signals are converted to digital values
- Electricity Basics: Basic understanding of voltage, resistance, and signal levels
- Basic Statistics (general knowledge): Mean, median, and variance concepts
17.8 Key Concepts
This section: Key Concepts
- Noise: Random variations in sensor readings caused by electrical interference, temperature fluctuations, or quantization errors.
- Filtering: Mathematical techniques to remove noise while preserving the true signal.
- Calibration: Process of adjusting sensor output to match known reference values.
- Offset Error: Constant shift in readings across the entire measurement range (zero-point shift).
- Gain Error: Proportional error that increases with measured value (sensitivity error).
- Drift: Gradual change in sensor accuracy over time due to aging or environmental factors.
- EEPROM: Non-volatile memory for storing calibration data that persists across power cycles.
17.9 Quick Check: Processing PurposeCheck your understanding: Processing Purpose
This section: Quick Check: Processing Purpose
17.10 Introduction
This section: Introduction — Raw sensor data is rarely perfect.
Raw sensor data is rarely perfect. Environmental noise, electrical interference, and manufacturing variations all affect measurement accuracy. This chapter covers the essential techniques for transforming noisy, uncalibrated sensor readings into reliable, accurate measurements.
17.11 Sensor Data Processing
This section: Sensor Data Processing
Core Concept: Raw sensor readings contain noise (random variations) and systematic errors (consistent offsets). Processing transforms unreliable raw data into accurate, usable measurements through filtering and calibration.
Why It Matters: An uncalibrated temperature sensor reading “25.3C” might actually mean anything from 23C to 28C. For an IoT system controlling HVAC or monitoring medical equipment, this uncertainty is unacceptable. Processing ensures your decisions are based on reality, not sensor artifacts.
Key Takeaway: Apply a moving average filter for slow-changing signals (temperature, humidity), use median filters to remove spikes, and always perform two-point calibration before deployment. Store calibration coefficients in EEPROM so they survive power cycles.
17.12 Making Sensors Tell Truth
This section: Making Sensors Tell Truth
Meet our friends: Temperature Terry, Lila the Light, the microcontroller, and the battery!
Sammy says: “I try my best to measure temperature, but sometimes I get a little jittery - like when you try to draw a straight line but your hand wobbles! That’s called NOISE.”
Lila explains: “Imagine you’re trying to count how many people are in a room, but every time you count, you get a slightly different number - 23, 25, 22, 24. A FILTER is like asking 5 friends to count and taking the average. Much more accurate!”
Real-world example: Think about your bathroom scale. If you step on it three times and get 65 kg, 64 kg, and 66 kg, you’d probably say you weigh about 65 kg - that’s filtering! And if you know your scale always reads 1 kg too high (your friend’s scale says 64 kg), you’d subtract 1 kg - that’s calibration!
Max’s tip: “Here’s how to make sensors tell the truth:
- Filter the noise - Take several readings and average them (like asking multiple people to measure)
- Calibrate for accuracy - Compare against a known reference and adjust (like using a ruler you KNOW is correct)
- Save the settings - Store calibration values so you don’t have to do it every time you turn on!”
Bella adds: “Good filtering means we don’t need to send as many messages to fix bad readings - that saves MY energy so your IoT device lasts longer on batteries!”
17.13 Moving Average Noise Reduction
This section: Moving Average Noise Reduction — An average is useful when several readings observe essentially the same physical condition.
An average is useful when several readings observe essentially the same physical condition. In the example below, five temperatures straddle 25°C, so the average estimates their shared centre. The gain comes from letting independent random deviations partly cancel.
The square-root noise rule assumes uncorrelated noise and a signal that remains sufficiently steady over the window. Five samples from a drifting reference do not become unbiased by being averaged. Likewise, a real temperature step is spread across successive windows, delaying the reported change. Compare the window’s duration with the fastest event the controller must detect before choosing its size. Use the calculation as a noise estimate under those assumptions, not as a guarantee of absolute accuracy.
Raw sensor readings: 24.8°C, 25.2°C, 24.9°C, 25.1°C, 25.0°C
Standard deviation (noise):
After 5-sample moving average:
Noise reduction: — approximately a 2.24x improvement.
For N samples, noise reduces by factor , demonstrating the mathematical basis for why averaging multiple readings improves measurement quality beyond individual sensor accuracy.
Try It: Noise Reduction Calculator
This section:
 Checkpoint: Measurement Meaning
You now know:
- Processing is only useful when it preserves the measurement claim instead of smoothing away the evidence.
- A 5-sample average can turn readings near 25C into a 25.0C estimate while reducing noise from 0.14C to 0.063C.
- Averaging improves as sqrt(N): the example’s 5 samples give about a 2.24x improvement, not a free accuracy guarantee.
17.14 Filtering Noisy Sensor Data
This section: Filtering Noisy Sensor Data — Sensor noise comes from many sources: electrical interference, quantization errors, and environmental factors.
Sensor noise comes from many sources: electrical interference, quantization errors, and environmental factors. Filters remove this noise while preserving the true signal.
The roadmap now shifts from “why process?” to “which process?” Start with the noise pattern you can observe, because the wrong filter can make a clean-looking but misleading signal.
17.15 Folded Sampling And Aliasing Notes
This section: Folded Sampling And Aliasing Notes — Filtering starts before the ADC.
Filtering starts before the ADC. If a signal is sampled below twice the highest frequency of interest, high-frequency content can appear as a false low-frequency pattern. Diagnose aliasing by naming the highest signal component, comparing it with the sample rate, changing the sample rate during a test, or checking the real waveform with faster capture.
Use the Nyquist limit as a minimum, not a complete design. Practical systems often sample faster than two times the highest frequency because analog filters roll off gradually. Place an anti-aliasing low-pass filter before the ADC when unwanted higher-frequency energy could enter the sampled data, then choose the digital filter after the sampled record preserves the signal you actually care about.
17.15.1 Sensor Data Processing Pipeline
The following diagram shows the complete sensor data processing pipeline from raw readings to calibrated output:
Before choosing a filter, inspect Figure 17.1 to locate filtering among validation, calibration, and conversion to engineering units.
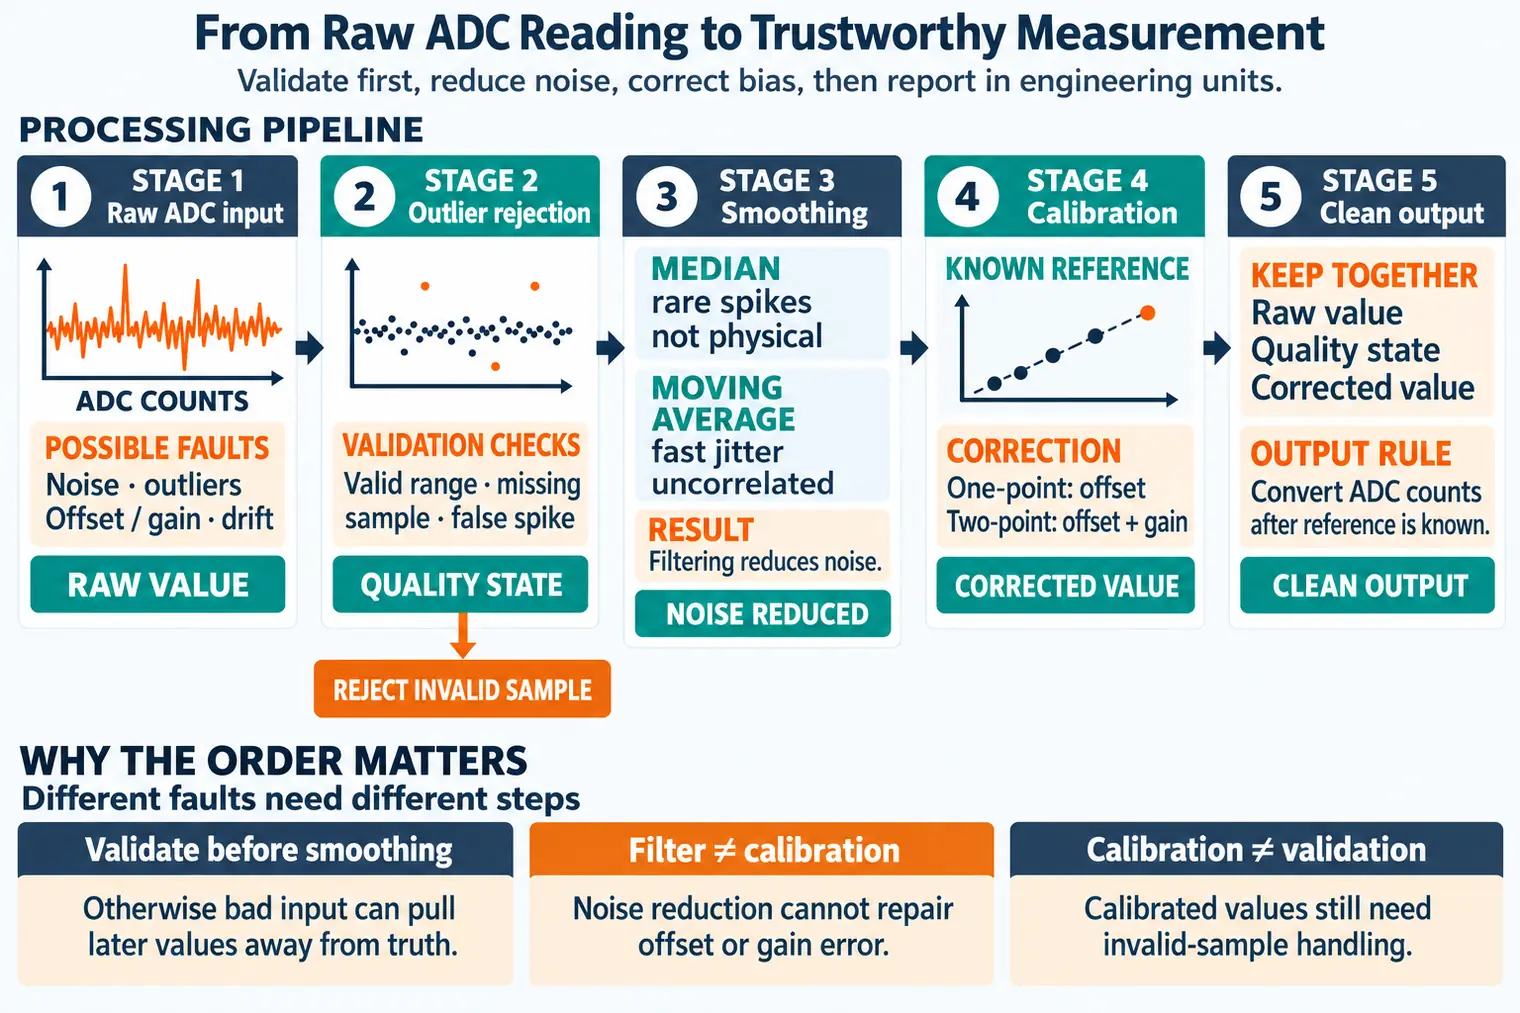
Sensor data processing pipeline showing stages from raw ADC input through outlier rejection, smoothing, calibration, to clean output in engineering units
Read Figure 17.1 from raw ADC input through outlier rejection and smoothing, then follow calibration into clean output. The order shows why noise reduction cannot repair bias and why calibrated values still require invalid-sample handling.
17.15.2 Filter Selection Decision Tree
Choosing the right filter depends on your signal characteristics and noise type. Use Figure 17.3 before implementing one: it separates noise-shape decisions from calibration errors that no filter can remove.
Filter Selection Decision Tree
Start with the failure mode you see in real readings, then choose the lightest filter that solves that problem.
Use a median filter first. It rejects outliers without averaging the bad value into later readings.
Use a moving average. Temperature, humidity, and pressure often only need a short rolling window.
Use exponential moving average. Tune alpha: lower is smoother, higher follows changes faster.
Use a Kalman filter when you can estimate process noise and measurement noise.
Use an IIR, Butterworth, or notch filter when you know the unwanted frequency band.
Filtering cannot fix offset or gain error. Calibrate with one, two, or multiple reference points.
Figure 17.3 begins with symptoms, not algorithm names. Occasional impossible spikes? points to a median filter because an outlier should be rejected rather than spread across a window. Slow signal with random jitter? leads instead to a moving average, while Need low memory or faster response? trades some smoothing for the tunable response of an exponential moving average. The dynamic-state branch, Tracking motion or dynamic state?, reserves a Kalman filter for cases with defensible process- and measurement-noise models; Known frequency interference? calls for a frequency-selective IIR, Butterworth, or notch design. Finally, Still biased after filtering? exits the tree toward calibration. That last card keeps the pipeline honest: the filter examples that follow address variation, not offset or gain error.
17.15.3 Moving Average Filter
The moving average filter is the simplest and most common approach. It averages the last N readings to smooth out random variations.
Use it when the measured quantity changes slowly and the problem is random jitter, not sudden spikes. For a beginner, the behavior matters more than the implementation: a larger window gives a smoother line but reacts more slowly.
17.15.4 Moving-Average Behavior
Start by keep the last N readings. Then remove the oldest reading when the window is full. Next add the newest reading. Finally return the sum divided by the number of valid readings.
17.15.5 Optional C++ Pattern
Read this implementation as a stored window plus a running sum. Each accepted reading replaces the oldest slot once the window is full. Subtracting that old value and adding the new one avoids summing the whole buffer on every call.
Trace the startup case before copying the pattern. With only two valid readings, divide by two, not by the configured maximum window size. Then trace one complete replacement and check that the sum contains exactly the current window. These checks explain the algorithm more usefully than watching a smooth plot. The class handles averaging; the surrounding pipeline still needs timestamps, invalid-sample policy, and calibration. A correct buffer implementation cannot decide whether the window is short enough to preserve a real event.
// Moving average filter (template-based, stack-allocated)
// Template parameter N sets window size at compile time —
// avoids heap allocation, which is unsafe on memory-constrained MCUs.
template<int N>
class MovingAverageFilter {
  private:
    float buffer[N];  // Stack-allocated, size known at compile time
    int index;
    int count;         // Tracks samples received (for cold-start)
    float sum;

  public:
    MovingAverageFilter() {
      index = 0;
      count = 0;
      sum = 0;

      for(int i = 0; i < N; i++) {
        buffer[i] = 0;
      }
    }

    float filter(float value) {
      sum -= buffer[index];
      buffer[index] = value;
      sum += value;

      index = (index + 1) % N;

      if (count < N) count++;  // Track fill level

      return sum / count;  // Divide by actual samples, not window size
    }
};
17.15.6 Kalman Filter
The Kalman filter provides optimal noise reduction for linear systems with Gaussian noise by modeling the system dynamics. It adapts based on measurement uncertainty and process noise. (For non-linear sensors such as thermistors or pH electrodes, Extended or Unscented Kalman Filters are needed instead.)
For most beginner IoT projects, do not start with Kalman. Start with the interactive comparison below, then choose Kalman only when the signal represents a changing state such as position, velocity, or orientation and you can estimate process and measurement noise.
17.15.7 Optional C++ Pattern
The example keeps an estimate and its uncertainty between calls. Each update combines a predicted state with the newest measurement, with process and measurement uncertainty influencing the correction. The arithmetic is small; choosing credible uncertainty values is the harder part.
Follow one update with a prediction below the measured value. The corrected estimate should move toward that measurement by the calculated gain. Then ask what repeated disagreement means: the physical state may have changed, the model may be inadequate, or the sensor may be faulty. The implementation cannot distinguish those explanations by itself. Use recorded steady and changing inputs to evaluate the model, and keep raw observations beside the estimate. Copying a compact Kalman class does not supply the missing system model.
// Kalman filter (simple 1D implementation)
class KalmanFilter {
  private:
    float q;  // Process noise covariance
    float r;  // Measurement noise covariance
    float x;  // Estimated value
    float p;  // Estimation error covariance
    float k;  // Kalman gain

  public:
    KalmanFilter(float processNoise, float measurementNoise, float initialValue) {
      q = processNoise;
      r = measurementNoise;
      x = initialValue;
      p = 1;
    }

    float filter(float measurement) {
      // Prediction
      p = p + q;

      // Update
      k = p / (p + r);
      x = x + k * (measurement - x);
      p = (1 - k) * p;

      return x;
    }
};

// Usage example
MovingAverageFilter<10> maFilter;  // 10-sample window (stack-allocated)
KalmanFilter kFilter(0.01, 0.1, 25.0);  // Process noise, measurement noise, initial value

void loop() {
  float rawTemp = readTemperature();

  float filteredMA = maFilter.filter(rawTemp);
  float filteredKalman = kFilter.filter(rawTemp);

  Serial.print("Raw: ");
  Serial.print(rawTemp);
  Serial.print(" | Moving Avg: ");
  Serial.print(filteredMA);
  Serial.print(" | Kalman: ");
  Serial.println(filteredKalman);

  delay(100);
}
17.15.8 Median Filter for Spike Removal
When sensor data has occasional spike errors (outliers), a median filter is more effective than averaging.
The key idea is simple: sort a short window and keep the middle value. A single bad spike is ignored instead of being averaged into future readings.
17.15.9 Optional C++ Pattern
The helper receives a buffer of recent readings, copies it into a sortable window, and returns the middle value. Sorting a copy matters because the caller may still need the chronological buffer to decide which reading should be replaced next. Treat those as two different orders: time order for storage, magnitude order for selection.
Trace a window with one extreme value and verify that the returned middle value stays near its neighbours. Next trace several consecutive elevated readings. Once they occupy enough of the window, the median follows them. That is expected behaviour, not a failure of sorting. It shows why the window must be checked against real event duration. Keep validity checks outside the helper, and decide what its output means before the window is fully populated.
// Median filter with fixed-size buffer (no VLA — portable C++)
const int MAX_MEDIAN_SIZE = 16;

float medianFilter(float* buffer, int size) {
    // Safety check: clamp to max supported window
    if (size > MAX_MEDIAN_SIZE) size = MAX_MEDIAN_SIZE;

    float sorted[MAX_MEDIAN_SIZE];
    memcpy(sorted, buffer, size * sizeof(float));

    // Bubble sort — O(N^2), but acceptable for small N typical
    // in sensor filtering (N=3 to N=9). For larger windows,
    // consider insertion sort or std::nth_element for O(N) median.
    for (int i = 0; i < size - 1; i++) {
        for (int j = 0; j < size - i - 1; j++) {
            if (sorted[j] > sorted[j+1]) {
                float temp = sorted[j];
                sorted[j] = sorted[j+1];
                sorted[j+1] = temp;
            }
        }
    }

    // For even N, returns upper-median (standard median averages
    // the two middle values, but single-value is simpler for embedded)
    return sorted[size / 2];
}

// Example: [22, 55, 23] -> sorted: [22, 23, 55] -> median: 23
// The spike (55) is completely ignored!
17.15.10 Filter Behavior Comparison
The following diagram compares moving average and median filter responses to the same noisy input with a spike. Kalman filter response varies based on Q and R parameters and is explored in the interactive calculator below.
The noisy trace and isolated spike in Figure 17.2 reveal how each filter changes both noise and transient response.
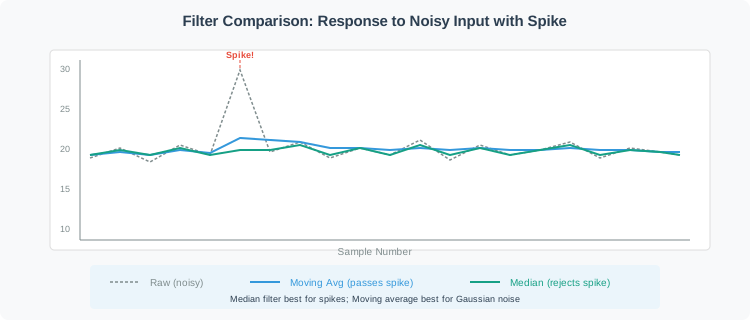
Filter comparison chart showing how raw noisy signal, moving average, and median filter each respond to the same noisy input with a spike, demonstrating median filter’s spike rejection ability
Read Figure 17.2 from the raw series to the moving-average and median outputs. The moving average spreads a spike across its window, so several later samples remain displaced after the raw event has passed. The median instead rejects an isolated outlier while preserving the surrounding level. That difference connects the expected noise shape to filter choice: use averaging for distributed random variation, but prefer a median when occasional impulses would contaminate a windowed mean.
17.15.11 Filter Comparison Summary
| Filter Type | Memory (N samples) | CPU Cost | Latency | Best For | Weakness |
|---|---|---|---|---|---|
| Moving Average | N floats (4N bytes) | O(1) with circular buffer | N/2 samples | Gaussian noise, slow signals | Passes spikes, fixed response |
| Median Filter | N floats (4N bytes) | O(N^2^) bubble sort; O(N) possible | N/2 samples | Spike/impulse noise | CPU intensive for large N |
| Exponential MA | 1 float (4 bytes) | O(1) | (1-alpha)/alpha samples | Memory-constrained devices | Parameter tuning required |
| Kalman Filter | 5 floats (20 bytes) | O(1) with multiply/divide | Adaptive | Tracking, state estimation | Requires noise characterization |
| IIR/Butterworth | Order x 2 floats | O(order) | Phase-dependent | Known frequency noise | Design complexity (beyond this chapter’s scope) |
17.15.12 Exponential Moving Average (EMA)
The EMA is the most memory-efficient filter — it requires only a single float (4 bytes) of state. Unlike a moving average that weights all N samples equally, the EMA gives exponentially decreasing weight to older samples. The smoothing factor alpha (0 to 1) controls responsiveness: lower alpha means smoother output but slower response.
Think of alpha as a trust knob: high alpha trusts the newest reading, low alpha trusts the previous filtered value.
17.15.13 EMA Behavior
filtered = alpha x new_reading + (1 - alpha) x previous_filtered
High alpha follows new readings quickly; low alpha produces a smoother, slower response.
17.15.14 Optional C++ Pattern
The EMA implementation needs a previous estimate rather than an entire sample window. Each accepted reading updates that estimate using alpha, leaving older observations with progressively less influence. Inspect how the class initializes its state so the first outputs do not reflect an unintended zero value.
Trace the worked 20°C-to-24°C change with alpha set to 0.25: the next two estimates should be 21°C and 21.75°C. Then repeat at a different sampling interval and compare the response in seconds. The arithmetic per call is unchanged, but the physical response time changes. Keep this distinction in the prototype record. Low memory use makes the pattern convenient; it does not remove the need to justify alpha, handle invalid readings, and verify threshold timing.
// Exponential Moving Average — one previous output; implementation storage is additional
class EMAFilter {
  private:
    float filtered;
    float alpha;
    bool initialized;

  public:
    EMAFilter(float smoothingFactor) {
      alpha = smoothingFactor;
      filtered = 0;
      initialized = false;
    }

    float filter(float newValue) {
      if (!initialized) {
        filtered = newValue;  // First sample: no smoothing
        initialized = true;
      } else {
        filtered = alpha * newValue + (1.0 - alpha) * filtered;
      }
      return filtered;
    }
};

// Usage: alpha=0.1 for heavy smoothing, alpha=0.5 for fast response
EMAFilter emaFilter(0.1);

void loop() {
  float raw = readTemperature();
  float smoothed = emaFilter.filter(raw);  // O(1) time; implementation storage is additional
  delay(100);
}
Try It: Filter Latency and EMA Explorer
17.15.15 Moving Average vs Kalman Filters
Option A: Moving Average (N=10 samples): A ten-sample buffer uses 40 bytes when floats occupy four bytes, plus the running sum and bookkeeping. Group delay is 4.5 samples; uncorrelated equal-variance noise is reduced by sqrt(10), about 3.16 times. Tune N against the required response time and measure execution cost on the target.
Option B: Kalman Filter (1D): A compact state estimate with adaptive gain and Q/R tuning; memory, CPU time, delay, and noise reduction depend on the implementation and signal.
Decision Factors: Compare both filters on recorded steady inputs and real transitions. Kalman performance depends on the state model and process and measurement uncertainties. The moving-average example here uses floating-point arithmetic; integer implementations are possible, but precision, overflow, memory, and execution time must be checked on the target.
Try It: Kalman Filter Gain Explorer
Adjust Q (process noise) and R (measurement noise) to see how the Kalman gain converges. Higher Q/R ratio means the filter trusts measurements more; lower ratio means it trusts its own predictions more.
17.16 Continue to the Next Part
This section: Continue to the Next Part — Carry this evidence into Sensor Processing: Filter Selection and Validation, which begins with Vibration Filter Selection.
Carry this evidence into Sensor Processing: Filter Selection and Validation, which begins with Vibration Filter Selection.
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed