7 Cloud Platforms: Provider Checks and Selection
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
7.1 Start With the Decision
This section: Start With the Decision — A provider demo cannot prove how a whole fleet of devices behaves under load, when many devices use the service at once, or during an outage, when the service is unavailable.
A provider demo cannot prove how a whole fleet of devices behaves under load, when many devices use the service at once, or during an outage, when the service is unavailable. A simulation models those conditions. Pair it with checks on the path the product will use.
7.2 Route Overview
This section: Route Overview — This is part 2 of 2.
This is part 2 of 2. Review Cloud Platforms: Message Paths and Capacity for the preceding evidence.
7.3 Learning Objectives
This section: Learning Objectives
- Design simulation and provider checks for an IoT workload.
- Record platform selection with capacity and storage evidence.
7.4 Chapter Roadmap
This section: Chapter Roadmap
- Simulation and Provider Checks
- Cold-Storage Platform Messaging
- Platform Selection Record
- Common Pitfalls
- Do Not Pick by Feature Lists
- 2. Treating A Broker As A Database
- 3. Ignoring Duplicate Messages
- 4. Hiding Failed Messages
- Platforms Map Message Duties
- Platform Selection Record
- Reliability Across Boundaries
- Summary
- Key Takeaway
- See Also
7.5 Simulation and Provider Checks
This section: Simulation and Provider Checks — Cloud simulators and named provider stacks are useful when they turn assumptions into repeatable evidence.
Cloud simulators and named provider stacks are useful when they turn assumptions into repeatable evidence. They should not replace the platform record.
Use simulation when a real deployment would be too slow, expensive, or disruptive to test directly. A simulator record should name the workload, topology, virtual machines or services, scheduling policy, network delay, storage behavior, energy or cost model, and the values changed between runs. Tools in this family include CloudSim-style discrete-event simulation for data centers, VMs, brokers, applications, and users; CloudAnalyst-style experiments for geographically distributed users and data centers; and GreenCloud-style experiments for energy and network behavior inside data-center designs. The result is useful only when the run explains what it did not model, such as provider quotas, managed-service behavior, hardware failures, security controls, or operational support.
Named platforms need the same discipline. OpenStack can be a self-managed IaaS control plane when private-cloud control and integration matter, but it brings ownership of compute, networking, images, storage, patching, monitoring, and upgrade risk. Azure, AWS, and similar public clouds can supply managed compute, storage, messaging, analytics, monitoring, machine learning, and IoT services, but the team still owns workload fit, identity policy, data retention, export, cost review, and recovery evidence. For EC2-style virtual machines, record instance family, storage choice, scaling rule, image maintenance, network policy, and the reason the workload needs VM-level control instead of a more managed runtime.
Treat every simulator or provider comparison as a scenario test, not a ranking table. A useful comparison says which design choice changed, which metric moved, which responsibility shifted, and which proof is still required before production.
7.6 Cold-Storage Platform Messaging
This section: Cold-Storage Platform Messaging — A cold-storage operator has gateways at many facilities.
A cold-storage operator has gateways at many facilities. Each gateway receives temperature readings, door events, compressor state, local alarm events, and device-health records. The system needs local alarms, central dashboards, maintenance workflows, and replayable records for investigations.
7.6.1 Workload Placement
Device-facing broker
- Accepts gateway telemetry and device-health updates.
- Uses topic names that include site, device class, and event family.
- Enforces gateway identity and allowed topic patterns.
- Keeps short local buffers during connectivity loss.
Routing and queueing
- Sends urgent alarm events to a work queue with retry and escalation handling.
- Routes accepted telemetry summaries to long-term storage.
- Sends rejected or malformed events to inspection instead of silently dropping them.
Event stream
- Keeps ordered operational events for replay and analytics.
- Lets analytics consumers reprocess events after schema or model changes.
- Tracks lag so teams know when dashboards or reports are stale.
Return path
- Sends approved configuration changes back through a controlled command topic.
- Requires idempotent command handlers on gateways.
- Records command intent, approval, delivery, acknowledgment, and rollback state.
Decision record: The device broker is optimized for secure gateway sessions and topic authorization. Alarm handling uses a queue so processors can retry and escalate. The replay stream holds accepted operational events for investigation and analytics. Configuration changes return only through an approved command path with idempotent handlers.
7.7 Platform Selection Record
This section: Platform Selection Record — The platform selection record is the artifact that keeps the chapter from becoming a product comparison.
The platform selection record is the artifact that keeps the chapter from becoming a product comparison.
Use Figure 7.1 to connect a cloud workload to its message path, capacity proof, owner, and limits on portability.
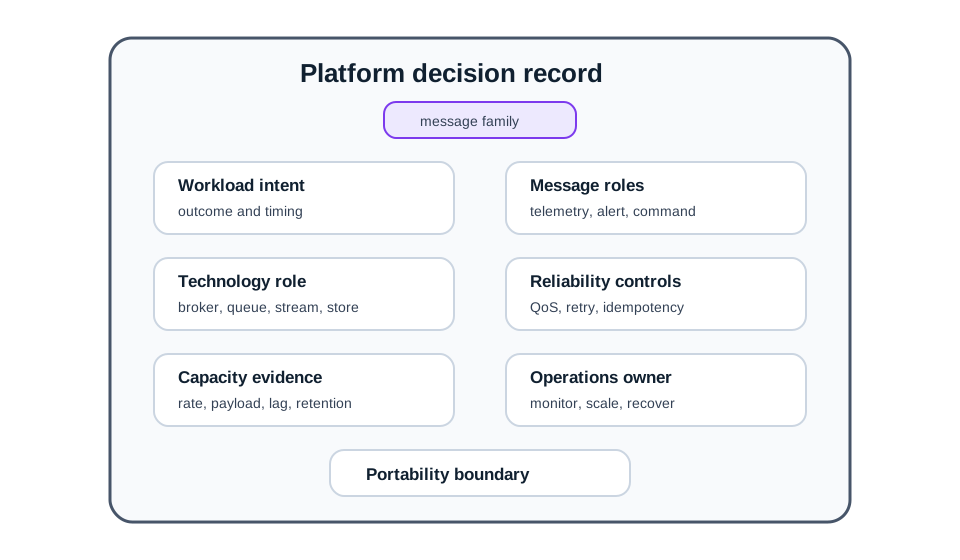
The fields in Figure 7.1 turn a platform choice into a test plan. Workload intent names the outcome and timing before message roles split telemetry, alerts, commands, and replay. The technology field then assigns broker, queue, stream, or store to each job. Reliability controls record QoS, retries, and idempotency; capacity evidence keeps peak rate, payload size, lag, retention, and load results. Operations names who monitors, scales, and recovers the path. The portability boundary records service-specific rules and formats that may be hard to move. A platform comparison is useful only when these records show what it must do for the chosen message family.
Include:
- Workload intent: what outcome the platform path supports.
- Message roles: telemetry, alert, command, state, audit, replay, or file reference.
- Technology role: broker, queue, stream, state store, time-series store, object store, or application API.
- Reliability controls: QoS, retries, idempotency, deduplication, dead-letter handling, and replay.
- Capacity record: connection count, peak rate, payload size, retention, lag, and load-test result.
- Operations owner: monitoring, scaling, credential rotation, patching, incident response, and check cadence.
- Portability boundary: where service-specific rules, state formats, or deployment assumptions exist.
7.8 Common Pitfalls
This section: Common Pitfalls
Feature lists hide operations risk. Check the responsibilities the team will own: identity, patching, routing rules, scaling, storage, monitoring, and response to outages.
A broker can retain selected state or sessions, but it should not be the only long-term record store. Send accepted events to storage or a retained stream when replay or audit is required.
Retries, reconnects, QoS 1 delivery, and downstream failures can create duplicates. Use idempotency keys and safe processors when duplicates would harm analytics or operations.
Malformed, unauthorized, or repeatedly failing messages need an inspection path. Silent drops make data gaps difficult to investigate and can hide device defects.
7.9 Platforms Map Message Duties
This section: Platforms Map Message Duties — An IoT cloud platform is a set of responsibilities around messages, not a single endpoint.
An IoT cloud platform is a set of responsibilities around messages, not a single endpoint. The design must say who proves device identity, who accepts messages, where work is buffered, which events are retained for replay, which state is synchronized, and how commands return toward the field.
Before making the decision in this section, inspect Figure 7.2. It makes the decision concrete by showing use the platform responsibility map to keep identity, ingestion, routing, storage, observability, state, and return-path duties visible before choosing a managed, self-managed, or hybrid shape, so the relationships can be checked before they are turned into a design claim.Figure 7.2 gives each cold-storage message duty an owner before platform selection.
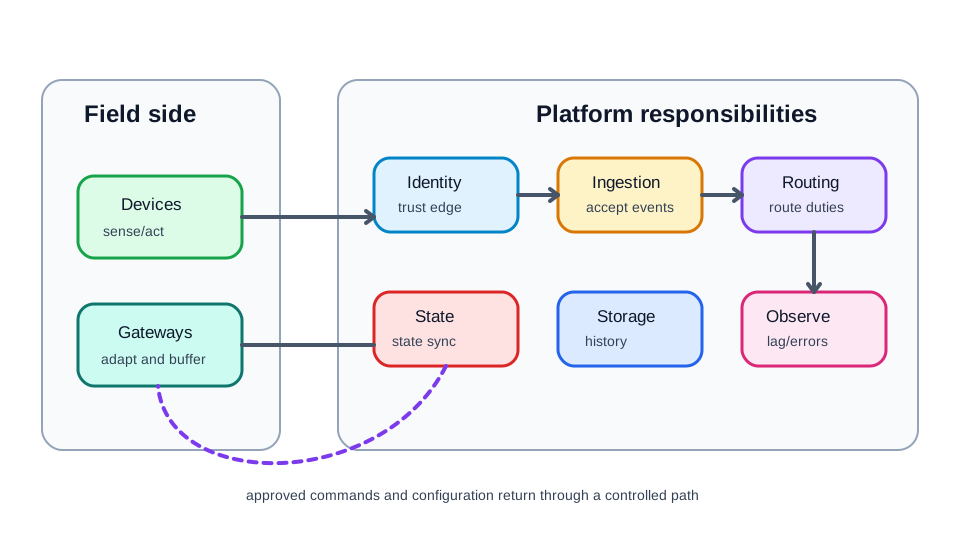
Read Figure 7.2 from field devices and gateways to identity and intake. Those first services decide who may join and which events may pass. Routes then send accepted data to state, stores, and apps. Logs and health checks show whether each handoff works. Follow the return path last. Safe commands and settings must use a ruled path; they cannot skip identity and policy. A platform choice is complete only when the team names an owner and proof for each duty. It also needs a safe response when either a managed part or a self-run part is down.
Devices and gateways produce temperature, door, and health events. Identity must establish which source may publish, and ingestion must accept valid messages while rejecting bad ones. Routing sends urgent alarms to a queue and later action, while storage and the event stream retain accepted telemetry for replay and analysis. A state view must expose stale devices when messages stop. Managed, self-managed, and hybrid designs can put those duties in different services, but the duties do not disappear. Trace one normal reading, one urgent alarm, and one failed delivery through the map before choosing the platform shape.
Mobile summary: A cloud platform decision is a responsibility decision: prove device identity, accept messages, route work, retain evidence, observe failures, synchronize state, and control commands back to the field.
The broker, queue, and stream answer different parts of that map. A broker handles live publish-subscribe communication, a queue controls processor work, and a stream keeps accepted events available for replay, analytics, and audit.
Keep the first review at message-family level. Room temperature telemetry, compressor-fault alarms, gateway health reports, firmware rollout status, and setpoint commands should not be forced through one generic "cloud messaging" answer. Each family has a different identity check, delivery consequence, retention need, and owner.
For overview review, ask three questions. Which component proves the sender is allowed to publish? Which component absorbs work when downstream processors are slow? Which component keeps accepted events long enough to replay or audit them? If those answers point to different components, the platform design should say so explicitly.
Broker
Owns live topics, sessions, authentication, authorization, retained messages, and offline behavior at the connection-facing boundary.
Queue
Owns work dispatch, retry timing, back-pressure, dead-letter handling, and alerting when processors cannot keep up.
Stream
Owns ordered event history, retention, consumer lag, schema evolution, and replay after analytics or model changes.
That trace should also name what is not proven. A broker acknowledgement does not prove dashboard freshness. A queue retry does not prove long-term history. A stream replay window does not prove that a command reached a gateway. The overview record should keep those boundaries visible before the team chooses managed, self-managed, or hybrid platform pieces.
A useful minimum record therefore has four columns: message family, platform role, evidence produced, and owner. For example, telemetry may name the broker topic and accepted-event store, alarms may name the queue and escalation owner, replay analytics may name the stream and retention window, and commands may name the return path plus acknowledgement rule. This keeps the overview small while still proving the architecture is more than a product label.
During the first pass, avoid mixing operational promises into one vague availability target. A platform can be available for telemetry while alarm processors are overloaded, replay consumers are behind, or command acknowledgements are delayed. The overview should therefore name the user-visible consequence for each message family: stale dashboard, missed escalation, incomplete audit, unsafe command state, or delayed maintenance action.
7.10 Platform Selection Record
This section: Platform Selection Record — Write one record per major message family.
Write one record per major message family. The record should not merely say "use managed IoT" or "self-host MQTT." It should tie workload behavior to the component role, validation evidence, operations owner, and retest trigger.
Use the record to separate normal traffic from stress cases. A platform that handles average telemetry may still fail during a power recovery when every gateway reconnects, resends buffered samples, refreshes credentials, and asks for pending commands. The record should include reconnect-storm behavior, rejected-message inspection, queue catch-up time, and the owner who decides whether to shed, defer, replay, or escalate work.
Also record the portability boundary. Topic naming, rule engines, device shadows, retained state, stream partition keys, and dead-letter formats can become service-specific. That is acceptable when the team names the dependency, tests the export or migration path that matters, and knows which release or compliance event would force a review.
For a cold-storage deployment, a useful record might say: alarm events use QoS 1 into the broker, include an idempotency key, enter a queue with dead-letter alerting, and write accepted alarm state to an audit stream. Temperature summaries use a replay stream with schema version and consumer-lag alert. Commands use a command id, authorization check, gateway acknowledgement, timeout, and rollback owner. Those details make the platform choice testable.
7.11 Reliability Across Boundaries
This section: Reliability Across Boundaries — MQTT QoS can confirm delivery between MQTT endpoints, but it does not prove downstream processing, storage, replay, dashboard state, or command execution.
MQTT QoS can confirm delivery between MQTT endpoints, but it does not prove downstream processing, storage, replay, dashboard state, or command execution. Each boundary needs its own failure rule, duplicate rule, and inspection path.
At the broker boundary, the key questions are session identity, topic authorization, retained-message behavior, duplicate publishes, and whether the acknowledgement means "accepted by broker" or "processed by the application." At the queue boundary, the questions change to visibility timeout, retry count, idempotency, poison-message handling, and when a failed message becomes an incident. At the stream boundary, the questions are partitioning, ordering scope, retention, schema evolution, lag, and replay authority.
Under load, these boundaries interact. A reconnect storm can create duplicate QoS 1 deliveries, queue backlogs, stream lag, dashboard staleness, and delayed commands at the same time. The release record should therefore connect sequence numbers or idempotency keys to the processor, not only to the broker. It should connect dead-letter records to operator action, not only to a storage bucket. It should connect replay windows to the investigation questions the team actually needs to answer.
Broker Ack
Proves the broker exchange, not whether a processor stored the event, an alert fired, or an operator saw it.
Queue Retry
Protects processors only if visibility timeout, idempotency, dead-letter handling, and alerting are configured together.
Stream Replay
Works only when retention, partitioning, schema evolution, consumer lag, and replay authority are owned explicitly.
Command Return
Needs authorization, idempotent handlers, acknowledgement state, timeout behavior, and rollback before it is safe to operate.
Command return paths need the same treatment. A command record should include command id, requested state, target group, authorization decision, delivery attempt, gateway acknowledgement, application completion proof, timeout rule, and rollback owner. Without those fields, a platform can show that a command was published while still leaving operators unsure whether the field system accepted or safely applied it.
This is why "exactly once" claims need careful wording. A protocol or service may narrow duplicate behavior for one exchange, but the IoT outcome still depends on application handlers, storage writes, retries, human workflow, and gateway state. The deeper platform proof is a chain of small contracts, each with its own evidence and owner.
For replay and audit, the boundary is not only technical; it is also interpretive. A stream partition key decides which events keep order together. A schema version decides which consumers can safely replay old records. A retention rule decides whether an incident can still be investigated. A lag alert decides when analytics are stale enough to stop trusting a dashboard. Those choices should be recorded beside the broker and queue settings because they change what the platform can prove after an outage or model defect.
Security boundaries also change the reliability claim. Mutual TLS or token validation proves a session identity, not that the device is healthy, calibrated, or authorized for every topic. Topic authorization proves publish permission, not that a payload schema is valid. Schema validation proves shape, not physical truth. The platform record should keep these proofs separate so incident review can locate the failing boundary quickly.
The same separation helps cost and capacity review. Broker connection limits, queue depth, stream retention, storage writes, and alert fan-out scale on different drivers. If the team records the driver at each boundary, it can retest the right part when gateway count, sampling rate, retention policy, or command frequency changes.
7.12 Summary
This section: Summary — Cloud platforms and message queues should be selected by workload responsibility, not by brittle named-service comparisons.
Cloud platforms and message queues should be selected by workload responsibility, not by brittle named-service comparisons. A durable IoT messaging architecture separates live device communication, work buffering, retained event history, state synchronization, storage integration, and controlled return paths. The quality gate is a validation record: capacity assumptions, QoS and retry behavior, replay tests, dead-letter handling, observability, operations ownership, and portability boundaries.
7.13 Key Takeaway
This section: Key Takeaway — Cloud platforms should be compared by message responsibilities, reliability boundaries, operations ownership, replay needs, and team operating capability.
Cloud platforms should be compared by message responsibilities, reliability boundaries, operations ownership, replay needs, and team operating capability.
7.14 See Also
This section: See Also
Responsibility boundaries across SaaS, PaaS, IaaS, and FaaS.
Cloud Deployment Models for IoT
Workload placement and hybrid boundary records.
Device identity, access boundaries, and secure return paths.
Monitoring, scaling, rollout, and operations readiness.
7.15 Continue Your Route
This section: Continue Your Route — This is the last part of this chapter.
This is the last part of this chapter. Return to Cloud Platforms: Message Paths and Capacity or continue from the cloud-sdn-production module index.
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed