11 Interface Examples: Gesture and Multimodal UX
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
11.1 Start With the Decision
This section: Start With the Decision — A gesture can feel quick while light, clothing, or motion makes it fail.
A gesture can feel quick while light, clothing, or motion makes it fail. A second mode can keep the task clear and safe.
11.2 Route Overview
This section: Route Overview — This is part 2 of 2.
This is part 2 of 2. Review Interface Examples: Voice UX for the preceding evidence.
11.3 Learning Objectives
This section: Learning Objectives
- Compare gesture, touch, voice, and visual feedback.
- Choose a multimodal route from context and access needs.
11.4 Chapter Roadmap
This section: Chapter Roadmap
- Visual Reference Gallery
- Gesture Control Interactions
- Multimodal Interaction Framework
- Smart Home Interface Design
- Voice Interface Design Flow
- Accessibility in IoT Design
- Knowledge Check: Voice Interface Design
- For Kids: Meet the Sensor Squad!
- Voice Command Success Analysis
- Checkpoint: Evidence Before Calculation
- Putting Numbers to It
- When to Use Voice Interfaces
- Avoid Overbuilt Voice NLU
- Checkpoint: Voice Fit and Complexity
- Interactive Quiz: Match Concepts
- Interactive Quiz: Sequence the Steps
- Common Pitfalls
- Understand Timing Assumptions
- Blocking Reads in Event Loops
- Handle Partial Serial Reads
- Label the Diagram
- Code Challenge
- Summary
- Concept Relationships
- See Also
- Try It Yourself
- What’s Next
11.5 Visual Reference Gallery
This section: Visual Reference Gallery — These AI-generated visualizations provide alternative perspectives on interface and interaction design concepts.
These AI-generated visualizations provide alternative perspectives on interface and interaction design concepts.
Use Figure 11.1 to trace a gesture from sensing to a device action.
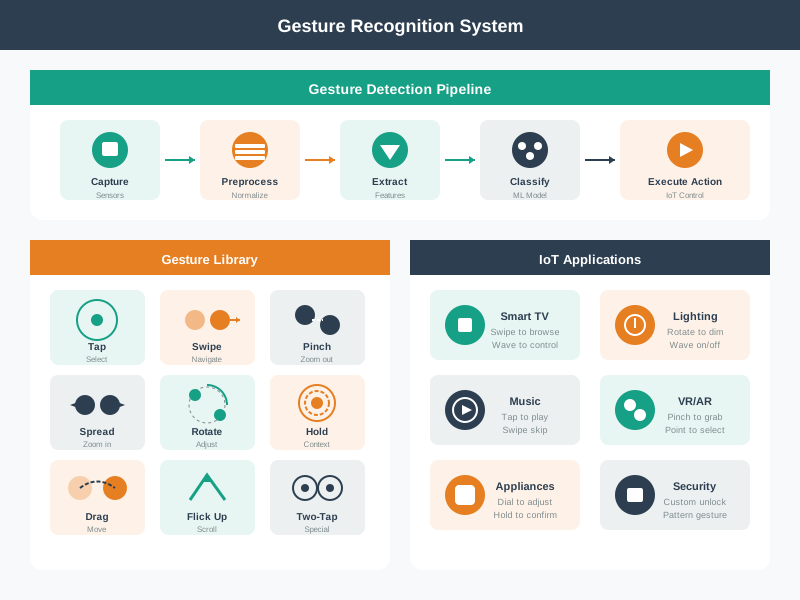
The pipeline captures a movement, normalizes it, extracts features, classifies it, and only then executes an IoT control. The gesture library shows that a swipe can navigate, a rotate can adjust, and a hold can express context; the meaning depends on the application. Music controls and VR or AR are examples of different uses of the same recognition route. The review should check what the system recognized and which action it sent, since a confident looking animation cannot prove that the intended device state changed.
Gesture control enables touchless interaction with IoT devices, particularly valuable in hands-busy situations (cooking, driving) or accessibility contexts. This visualization shows common gesture vocabularies and the feedback loop between user action and system response. Effective gesture interfaces provide clear affordances about available gestures and immediate visual or haptic feedback confirming recognition.
AI-Generated Visualization - Modern Style
The traces in Figure 11.2 compare voice, gesture, and touch for the same control goal.
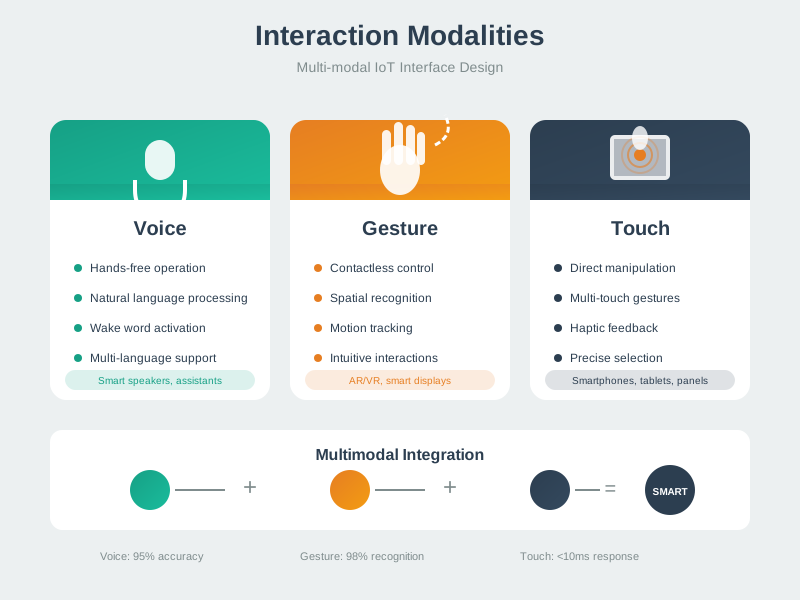
Gesture relies on spatial recognition and needs immediate feedback that the movement was seen. Touch offers a precise app selection, while voice must first recognize intent, acknowledge it, and then confirm the resulting light state. The timing notes separate acceptable response delay from how long the system waits after speech ends. These routes should share one truthful outcome even though their inputs differ. Test recognition and device confirmation separately so a spoken or visual acknowledgement is not mistaken for a completed action.
IoT systems typically support multiple interaction modalities to accommodate diverse contexts and user preferences. This framework shows how different input channels (voice, touch, physical, automated) can be combined to create flexible, accessible interfaces. The key challenge is maintaining consistency across modalities - the same action should be possible through voice, app, or physical control with predictable results.
AI-Generated Visualization - Modern Style
Read Figure 11.3 to follow a 2 AM unlock through the quiet-hours rule.
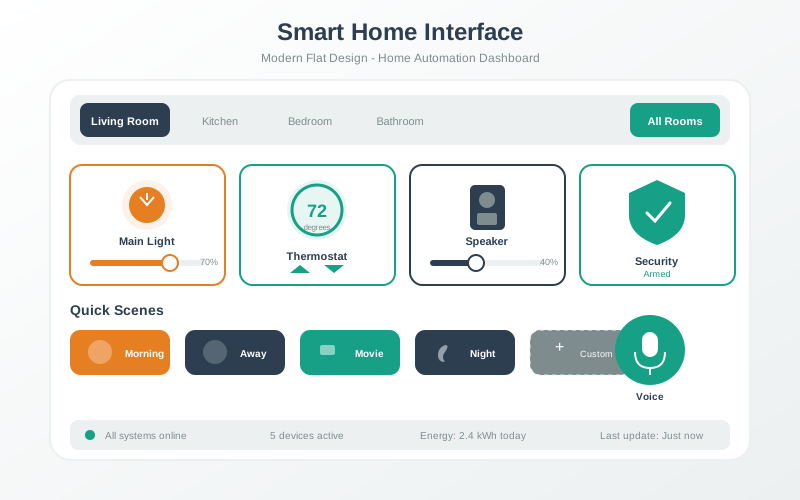
The trace starts at 2 AM, inside the 11 PM–7 AM quiet-hours interval. The rule therefore selects visual-only feedback for a confirmed unlock: an LED flashes while audio stays silent. The dashboard shows the same time, active rule, unlocked state, and LED result, giving the user one place to inspect or override it. The last warning says a failed lock or sensor response must remain visible; the scene must not look complete. That shared state matters when several interface channels are involved, because a sound, light, and screen must not tell different stories about the same action.
AI-Generated Visualization - Modern Style
Voice interfaces require careful orchestration of multiple components. The user speaks a wake word to activate the system, which then captures and processes speech in real-time. Natural language processing extracts intent and entities from the utterance, enabling the system to execute commands and provide appropriate audio feedback. Effective voice UI design must handle errors gracefully and maintain conversational context across multi-turn interactions.
AI-Generated Visualization - Artistic Style
Use Figure 11.4 to test accessible control when pairing fails.
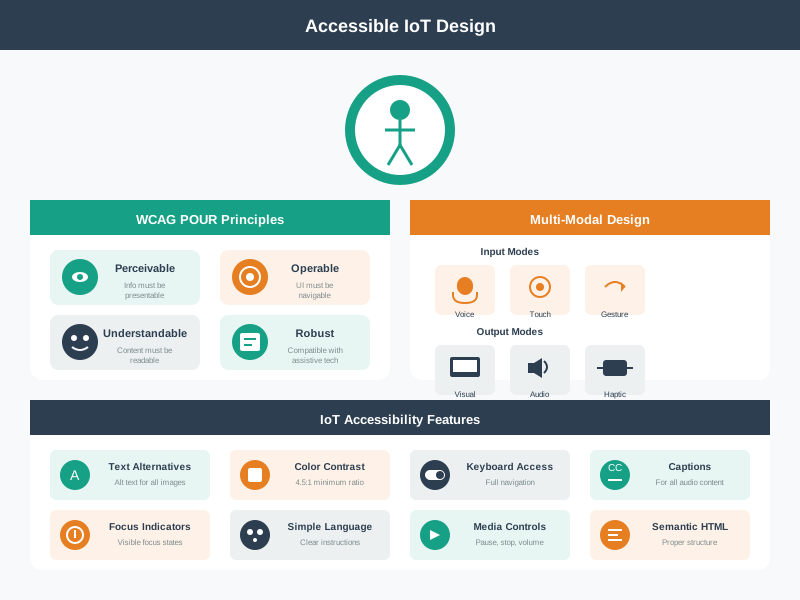
A VoiceOver user starts pairing while the gateway is offline. The live region must announce that the system is still trying and then offer a local reset route, rather than leaving a silent spinner. Touch, voice, gesture, keyboard, and physical controls are alternate paths, while text, speech, sound, and vibration can carry the result. Each channel has to name the state, explain delay or failure, and offer a safe fallback. Record the user behavior and technical setting when checking that contract.
Inclusive IoT design ensures devices are usable by people with diverse abilities and in varied contexts. This diagram illustrates key accessibility considerations across visual, motor, auditory, and cognitive dimensions. Visual accessibility includes high-contrast modes and screen reader support. Motor accessibility provides voice control and large touch targets for users with limited dexterity. Auditory accessibility substitutes visual and haptic feedback for audio cues. Cognitive accessibility emphasizes simple language, consistent patterns, and error prevention to reduce mental load.
AI-Generated Visualization - Geometric Style
Designing for everyone means making sure your device works for young AND old, with or without perfect hearing or vision!
11.5.1 Grandma Rose Smart Home
The Sensor Squad was helping Grandma Rose set up her smart home. But Grandma had some special needs: her hearing wasn’t as sharp as it used to be, and sometimes she forgot the exact words for things.
“Alexa, activate the luminaire!” said the microcontroller, demonstrating. “The what now?” asked Grandma Rose, confused.
“We need to think like GRANDMA, not like engineers!” said Temperature Terry. So they redesigned the whole voice system:
Speaking Grandma’s Language: Instead of requiring “Activate luminaire,” the system learned to understand “Turn on the light,” “I need light,” “It’s dark in here,” and even just “Light, please!” Sammy programmed 40 different ways to say the same thing.
Sounds She Can Hear: the LED discovered that Grandma couldn’t hear high-pitched beeps very well. So they changed all sounds to deeper, lower tones that Grandma could hear clearly. They also made the system speak a little SLOWER and LOUDER when the TV was on.
Kind Error Messages: When Grandma said something the system didn’t understand, instead of “Command not recognized” (scary!), it said: “I didn’t quite catch that. Did you mean the lights or the temperature?” Only TWO choices, so it wasn’t overwhelming.
Room Detective: The smartest feature was that the system figured out which room Grandma was in! When she said “Lights on” from the kitchen, it knew she meant the KITCHEN lights. No need to specify!
Always a Backup: On the wall, big friendly switches still worked without voice commands. A simple remote with 5 big buttons was always on the coffee table. And a bright orange “HELP” button could call the front desk anytime.
“Now I LOVE my smart home!” said Grandma Rose. “It listens to ME, not the other way around!”
11.5.2 Key Words for Kids
| Word | What It Means |
|---|---|
| Intent Recognition | Understanding what someone MEANS, not just the exact words they say |
| Multi-Modal | Having multiple ways to do the same thing (voice, buttons, remote, app) |
| Fallback | A backup plan when the main method doesn’t work (like a physical switch when voice fails) |
| Context Awareness | The device figuring out what you need based on WHERE you are and WHEN it is |
This synthetic worked example uses 2,847 commands over 4 weeks from 87 residents (ages 65–90); a real claim needs a study cohort, sampling protocol, and raw outcomes.
Synthetic worked-example command data:
| Command Category | Total Attempts | Successful | Failed | Success Rate | Top Failure Reason |
|---|---|---|---|---|---|
| Lights on/off | 1,243 | 1,189 | 54 | 95.7% | Background TV audio triggered false activations |
| Temperature adjust | 876 | 742 | 134 | 84.7% | Phrases like “I’m cold” not initially recognized—added after week 1 |
| Brightness adjust | 418 | 357 | 61 | 85.4% | “A little brighter” ambiguous—added increments of 10% |
| Room specification | 310 | 298 | 12 | 96.1% | Residents said room names clearly when needed |
Synthetic worked-example results by tech comfort:
| Tech Comfort Level | Residents | Avg Success Rate | Common Issue |
|---|---|---|---|
| High (20 residents) | Used smartphones daily | 93.2% | Few issues, occasionally over-specified commands |
| Medium (45 residents) | Occasional tech use | 88.1% | Forgot room context—asked “Which room?” frequently |
| Low (22 residents) | Minimal tech exposure | 79.3% | Struggled with phrasing—needed more suggestions |
Illustrative cost calculation using synthetic worked-example results (79.3% → 91.2%):
Added contextual hints: “You can say ‘too bright’ or ‘dim lights’” — 8 hours dev time. Expanded intent recognition from 40 to 87 phrase variations — 24 hours training. Added audio feedback for partial understanding — 6 hours. Total fix cost: $1,900 (38 hours × $50/hr). Illustrative result: In this synthetic example, the low-tech-comfort group improves from 79.3% to 91.2% success rate.
 Checkpoint: Evidence Before Calculation
You now know:
- The 2,847-command, 87-resident figures are synthetic worked-example inputs; a real claim would need a study cohort, sampling protocol and raw outcomes.
- Temperature adjustment is the weak spot at 84.7%, just below the 85% design target used in the example; validate adoption against observed user outcomes.
- The practical fix is not more magic: contextual hints, expanded phrase coverage from 40 to 87 variations, and partial-understanding feedback.
How do we calculate voice recognition success rate, and what does the example’s 85% design target mean?
Success rate formula (from 2,847 commands over 4 weeks):
For the “Temperature adjust” category:
Interactive Calculator: Voice Recognition Success Rate Analysis
A paired significance test requires each resident’s before-and-after outcomes. The two marginal confidence intervals do not determine a p-value.
Illustrative success rate before/after: 79.3% / 91.2%; compute uncertainty only from resident-level outcomes or a prespecified clustered analysis.
Improvement: 11.9 percentage points
Two-failure probability examples:
At 85% success, probability of 2 consecutive failures:
At 79% success (below the example’s 85% design target):
In this synthetic worked example, assume that 78% of users encountering 2+ consecutive failures within 5 minutes abandon voice and revert to physical controls.
Cost-benefit of the fix:
- Fix cost: $1,900 (38 developer hours)
- Value: additional successful commands per week
- Avoided support calls: 127 × 15% frustration rate × $28/call = $533/week savings
ROI: $533/week × 52 weeks = $27,716 annual savings vs. $1,900 fix cost = 15× return
Key insight: The 85% success target is a design threshold in this example, not a mathematical cutoff derived from two-failure probability. Validate adoption against observed user outcomes.
Assumed resident-satisfaction relationships in this example:
- Assumed relationship: 90%+ success rate → 4.6/5 satisfaction (“I love it!”)
- Assumed relationship: 80–89% success → 3.8/5 satisfaction (“It’s okay, sometimes frustrating”)
- Assumed relationship: under 80% success → 2.4/5 satisfaction (“I just use the switches instead”)
Key insight: The 85% success rate is an example design target; assess adoption against observed user outcomes rather than treating it as a minimum.
| Factor | Voice Control Appropriate | Voice Control Problematic |
|---|---|---|
| User hands | Occupied (cooking, carrying items) | Free and can use touchscreen |
| Environment noise | Quiet (<50 dB ambient) | Loud (>65 dB: factory, street, party) |
| Privacy needs | Private space (alone, family only) | Public/shared space (office, hospital) |
| Command complexity | Simple (on/off, warmer/cooler) | Complex (set schedule, configure automation) |
| User cognitive load | Low (one task at a time) | High (multitasking, stressed) |
| Accent/language | Recognition model trained on user demographic | Heavily accented speech, non-primary language |
| Latency tolerance | 1-2 second delay acceptable | Need instant response (<200 ms) |
Scoring system:
5+ factors favor voice → Primary interaction method. 3-4 factors favor voice → Secondary option (provide physical fallback). 2 or fewer → Don’t implement voice (wasted development effort).
Cost-benefit per device:
Voice recognition cloud service: $0.02-0.05 per command. 1,000 commands/month × 100 devices = $2,000-5,000/month. Must deliver value: estimate voice-feature costs and benefits at expected usage; a 20% uptake assumption alone does not determine ROI.
Design principle: Voice is convenience, not a replacement. Always provide physical controls for: Emergency situations (voice system fails). Guest users (don’t have account/app). Privacy moments (silent operation needed). In a high-reliability scenario, set an acceptable failure rate from task risk and user testing; 10–15% is an illustrative unacceptable range.
The mistake: Building sophisticated natural language understanding with 200+ intent variations, synonyms, and context tracking. Result: system over-interprets and makes wrong guesses.
Real example: A smart home voice system for elderly users tried to be “too smart”: User: “It’s cold in here”. System interprets: “Set temperature to 75°F based on historical preference”. Reality: User wanted temperature set to 72°F (their current preference). User now distrusts the system—it “doesn’t listen”.
Another example: User: “Turn on the lights… wait, no”. System already executed “lights on” before user finished speaking. Elderly users with slower speech need longer timeout before command execution.
Why over-engineering fails:
Cognitive mismatch: Sophisticated AI makes assumptions elderly users didn’t intend. Loss of control: Users feel the system is “doing its own thing”. Debugging is difficult without feedback: If intent recognition guesses wrong, show what it understood and give the user a clear correction path. Slower speech patterns: Elderly users speak with more pauses—system should wait longer.
The fix: Simpler is better for elderly users
GOOD approach (explicit, predictable):
User: “I’m cold”. System: “Would you like me to raise the temperature by 2 degrees? Say yes or no.”. User: “Yes”. System: “Raising temperature to 72 degrees.”.
BAD approach (implicit, unpredictable):
User: “I’m cold”. System: [Silently sets to 75°F based on historical data]. User: [Doesn’t realize it happened, doesn’t trust it].
Design principles for elderly voice interfaces:
Explicit confirmation: Always announce what the system will do before doing it. Limited choices: Max 2 options in clarification questions (not 5). Longer timeouts: Wait 2-3 seconds after user stops speaking (not <1 second). Undo commands: “Alexa, cancel that” works for any command issued in last 10 seconds. Progress feedback: “Turning on the lights… lights are now on” (confirm completion).
Complexity budget:
Intent variations: 30-40 per command (not 200+). Context tracking: 1 turn (remember last room mentioned, not full conversation history). Inferencing: Minimal (ask for clarification rather than guessing).
Validation: For this prototype, treat more than 15% wrong-action commands as a review trigger; set the production threshold with task-specific user testing.
Checkpoint: Voice Fit and Complexity
You now know:
- Voice should be primary only when enough factors favor it; otherwise it is a secondary convenience with physical fallback.
- Cost matters: 1,000 commands/month across 100 devices can cost $2,000-5,000/month before support burden.
- Overbuilt NLU fails when it guesses silently; the safer pattern is explicit confirmation, 2-option clarification, longer timeouts, undo, and progress feedback.
Common Pitfalls
This section: Common Pitfalls
Example code often uses fixed delays calibrated for one microcontroller clock speed that produce wrong timings on a different clock. Copying without checking can cause sensors to receive malformed I2C timing. Parameterise timing values from the clock speed constant and verify with a logic analyser on the actual target hardware.
Calling blocking sensor read functions within an MQTT callback can stall the network stack long enough for a watchdog reset or missed keep-alive. Trigger sensor reads from a timer, cache the latest value, and return cached data from any function called within a network callback.
Assuming a serial read() always returns a complete packet causes firmware to process partial payloads as valid data when bytes arrive in multiple TCP segments. Implement a length-prefixed or delimiter-terminated framing protocol and accumulate bytes into a ring buffer until a complete frame is received.
11.6 Summary
This section: Summary — Intent-Based Understanding: Design for natural speech patterns, not rigid command syntax.
This chapter demonstrated comprehensive worked examples:
Key Takeaways:
Intent-Based Understanding: Design for natural speech patterns, not rigid command syntax. Hearing Accessibility: Lower frequency responses, adaptive volume, visual redundancy. Cognitive Accessibility: Limit choices, system takes blame, offer suggestions. Context Awareness: Automatic room detection reduces cognitive burden. Multi-Modal Fallbacks: Voice augments physical controls, doesn’t replace them. Validation: Test across user abilities and assess outcomes against the example’s 85% design target.
How this chapter connects to other IoT concepts:
Synthesizes: Multimodal Design modality selection and Interaction Patterns feedback principles into complete worked example. Demonstrates: Design Process & Checklists validation applied to real retirement community deployment. Accessibility: WCAG Standards compliance through hearing-accessible audio and cognitive-load design choices. Voice Pipeline: Edge ML wake word detection and NLP intent recognition implementation details. Error Recovery: Graceful Degradation patterns applied to voice interface failures.
Related topics for deeper exploration:
Speech Recognition Systems: Technical details of automatic speech recognition (ASR) models and accuracy factors. Conversational AI Design: Broader principles of dialogue management and turn-taking in voice assistants. Age-Related Hearing Loss: Audiological research on presbycusis that informs the 180-220 Hz frequency selection. Cognitive Decline & Interface Design: Memory support strategies and error attribution psychology. Voice Biometrics Security: How voice interfaces authenticate users and prevent spoofing attacks.
Hands-on exercises to practice voice interface design:
11.6.1 Test Intent Recognition
Build a simple voice command parser:
Define one intent: “Turn on lights” with 10 phrase variations (“lights on”, “turn the lights on”, “I need light”, etc.). Implement keyword matching vs. intent-based classification. Test with 20 natural phrases from friends/family. Measure: What percentage of natural speech is recognized?
What to observe: Measure how many of your 20 test phrases keyword matching catches; record failures before trying intent patterns. Compare the revised parser on the same 20 phrases; report its observed recognition rate and new failure modes. Notice which phrases break your system—users say “it’s dark” not “activate illumination.”
11.6.2 Audio Feedback for Hearing Loss
Record a confirmation message (“Okay, turning on lights”):
- Version A: High-pitched voice (300-400 Hz female voice)
- Version B: Low-pitched voice (180-220 Hz male voice)
- Test with older adults (60+ years) in noisy environment (TV on at 60 dB)
- Measure comprehension: Can they repeat what the system said?
What to observe: Treat 40–50% missed by Version A as an illustrative test outcome to verify with participants who have age-related hearing loss. Treat 85–90% understood for Version B as an illustrative test outcome to verify in the same cohort. Lower frequencies may help in some settings; test with the intended audience.
11.6.3 Memory Support vs Exact Syntax
Design two error recovery approaches:
- Exact syntax: “Invalid command. Please say ‘set temperature to [number] degrees Fahrenheit’”
- Memory support: “I didn’t catch that. You can say things like ‘too cold’ or ‘warmer’”
Test with users with mild cognitive decline:
What to observe: Treat 70% exact-syntax failure and 90% example-aided success as hypothetical results to measure in the design exercise. Notice how many users try the exact example phrase—that’s why examples matter.
11.7 What’s Next
This section: What’s Next
| Next Topic | Description |
|---|---|
| Hands-On Lab | Build an accessible IoT interface using the Wokwi ESP32 simulator |
| Process & Checklists | Iterative design methodology and validation checklists |
| Multimodal Design | Modality tradeoffs and accessibility considerations |
| Interface Overview | Return to the chapter series overview |
11.8 Continue Your Route
This section: Continue Your Route — This is the last part of this chapter.
This is the last part of this chapter. Return to Interface Examples: Voice UX. See ux-design module index.
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed