7 Actuator Safety: Watchdogs and Interlocks
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
7.1 Start With the Decision
This section: Start With the Decision — A watchdog is a timer that detects a control loop that stops making progress.
A watchdog is a timer that detects a control loop that stops making progress. A control loop repeats the steps that read inputs and command motion. An interlock blocks motion when a safety condition is not met. A watchdog that trips too soon stops sound work; one set too late lets harm grow. Its limit must follow measured loop time.
7.2 Route Overview
This section: Route Overview — This is part 2 of 2.
This is part 2 of 2. Review Actuator Safety: Protection and Fail-Safe Design for the preceding evidence.
7.3 Learning Objectives
This section: Learning Objectives
- Calculate a watchdog timeout from task and bus delays.
- Design relay boot states, interlocks, and stall protection.
7.4 Chapter Roadmap
This section: Chapter Roadmap
- Watchdog Timeout Sizing
- Fail-Safe Relay Setup
- Pull-Downs on Relay Boot
- Fail-Safe Design Principles
- Deep Dive: Failure Energy, Interlocks, and Stall Protection
- Checkpoint: Fault Energy
- Summary
- Key Takeaway
- For Kids: Meet the Actuator Crew!
- Knowledge Check
- Quiz: Actuator Safety
- Concept Relationships
- See Also
- What’s Next?
- Label the Diagram
- Code Challenge
Watchdog timing narrated tour
Narrated audio tour. The full transcript is below.
Play the tour to animate the timeline. Pause, replay a beat, or read the full transcript below.
Full transcript — Watchdog timing (9 beats)
B1 — Shared control and logging
You are the engineer responsible for a network-controlled warehouse arm controller. The arm picks items from shelves; its controller also logs to a storage card. Should the arm controller wait for paperwork?
B2 — Loop progress and watchdog
A control loop repeatedly reads inputs and commands motion. A watchdog timer detects when that loop stops making progress. Only your control loop feeds it, at each iteration's end, restarting the timeout window. Missing that window resets the controller.
B3 — 325 ms loop, 487.5 ms candidate
The chapter's measured worst case combines seventy-five milliseconds of other work with a two hundred fifty millisecond card write. Together, they take three hundred twenty-five milliseconds. Multiply by a margin factor of one point five, and the candidate watchdog timeout becomes four hundred eighty-seven point five milliseconds.
B4 — Timing exceeds 300 ms limit
But the safe-stop limit for the arm is three hundred milliseconds. The candidate timeout exceeds that limit by one hundred eighty-seven point five milliseconds. Even the worst-case loop iteration takes too long: finishing work isn't finishing soon enough.
B5 — Timeout alone cannot resolve conflict
A larger timeout lets logging finish but only lengthens the wait; it cannot shorten the loop or extend the physical safety deadline. A timeout within the safety limit interrupts a permitted long iteration, so your design needs to change.
B6 — Queue logging; 100 ms loop, 150 ms watchdog
Move the slow storage-card logging out of the critical control loop. The loop queues a log event; a lower-priority background task writes it without blocking control. The chapter's illustrative redesign schedules the critical loop every one hundred milliseconds with a one hundred fifty millisecond watchdog.
B7 — Test the complete stop path
A reset alone cannot guarantee safe outputs: those settings need measurement and testing to prove the complete stopping path fits within three hundred milliseconds, with hardware reset defaults separately designed and tested.
B8 — Interlock blocks unsafe motion
An interlock blocks motion when a safety condition fails. An open guard forces a local stop, and a remote command must never bypass the guard. The watchdog checks loop progress; the interlock responds to physical safety conditions.
B9 — Measure, redesign, and test
With slow logging outside control, your loop and tested stopping path must fit the physical safety limit, while interlocks block unsafe motion.
Scenario: An IoT-controlled automated warehouse uses a robotic arm to pick items from shelves. The control loop performs these steps every cycle:
- Read load sensor (5 ms)
- Calculate pick trajectory (20 ms)
- Send motor commands via CAN bus (15 ms)
- Wait for arm position feedback (30 ms)
- Verify grip force sensor (5 ms)
- Log to SD card (10 ms)
Total expected loop time: 85 ms
Question: What watchdog timer (WDT) timeout should you configure to detect control loop hangs without triggering false positives?
Step 1: Account for worst-case execution variance
Real-world timing varies due to:
- CAN bus arbitration delays (priority collisions)
- SD card write delays (wear leveling, flash erase)
- Interrupt handling (network stack, sensor polling)
Measured worst-case loop times:
- Typical: 85 ms
- 95th percentile: 120 ms
- 99th percentile: 180 ms
- Worst-case loop (75 ms of other work plus a 250 ms SD card write): 325 ms
Step 2: Add safety margin
Watchdog timeout = Worst-case time × Safety factor
Using 1.5× safety factor: 325 ms × 1.5 = 487.5 ms
Step 3: Validate against actuator safety constraints
If the control loop hangs, what is the maximum safe time before forcing a system reset?
- Robot arm moving at 0.5 m/s
- Collision hazard if control lost for >300 ms (150mm uncontrolled travel)
487.5 ms candidate watchdog timeout exceeds the 300 ms safe-stop limit by 187.5 ms!
Step 4: Redesign control architecture
The 250 ms SD card write is the bottleneck creating the safety conflict. Solution: Decouple logging from critical loop
// BEFORE: Unsafe monolithic loop
void control_loop() {
    read_sensors();        // 5ms
    calculate_path();      // 20ms
    send_motor_commands(); // 15ms
    wait_for_feedback();   // 30ms
    verify_grip();         // 5ms
    log_to_sd();          // 10-250ms <-- PROBLEM!
    feed_watchdog();
}

// AFTER: Two-tier architecture
void critical_control_loop() {  // Runs every 100ms
    read_sensors();             // 5ms
    calculate_path();           // 20ms
    send_motor_commands();      // 15ms
    wait_for_feedback();        // 30ms
    verify_grip();              // 5ms
    queue_log_event();          // <1ms (just adds to queue)
    feed_watchdog();            // WDT timeout = 150ms (100ms × 1.5)
}

void background_logger() {      // Runs in lower-priority task
    if (log_queue_not_empty()) {
        write_to_sd_card();     // 10-250ms (doesn't block control)
    }
}
Final watchdog configuration:
esp_task_wdt_config_t cfg = { .timeout_ms = 150, .idle_core_mask = 0, .trigger_panic = true };
esp_err_t wdt_result = esp_task_wdt_init(&cfg);  // ESP-IDF 5.x; call after the scheduler starts
if (wdt_result == ESP_ERR_INVALID_STATE) {
    wdt_result = esp_task_wdt_reconfigure(&cfg);  // Already initialized
}
if (wdt_result != ESP_OK) {
    // Handle configuration failure; do not claim the watchdog is active.
    return;
}
wdt_result = esp_task_wdt_add(NULL);  // Add current task to WDT
if (wdt_result != ESP_OK) {
    // Handle subscription failure before relying on the watchdog.
    return;
}

while (1) {
    critical_control_loop();     // Must complete in <150ms
    esp_task_wdt_reset();        // Feed watchdog
}Verification: The ideal timer-only travel is 150 ms × 0.5 m/s = 75 mm (within the 150 mm target). This is not a guaranteed stopping distance: measure reset and output latency, and use an independent motion stop.
Key lesson: Watchdog timeout is a safety-critical parameter. Always:
- Measure real worst-case timing, not theoretical
- Account for I/O delays (SD, network, sensors)
- Ensure timeout is shorter than actuator safety constraint
- Decouple slow non-critical operations from control loop
When designing IoT systems controlling safety-critical actuators (door locks, HVAC, industrial equipment), the choice between normally-open (NO) and normally-closed (NC) relay contacts determines what happens during power loss or communication failure.
| Actuator Type | Safe State on Failure | Relay Configuration | Real-World Example |
|---|---|---|---|
| Heater/Furnace | OFF (prevent fire/overheating) | Normally-Open (NO) | Power loss = relay opens = heater disconnected |
| Cooling fan (data center) | ON (prevent equipment overheating) | Normally-Closed (NC) | Loss of relay-coil power = NC contact closes and keeps an independently powered fan on |
| Solenoid valve (water) | CLOSED (prevent flooding) | Use spring-return valve + NO relay | Power loss = spring closes valve mechanically |
| Door lock (fire exit) | UNLOCKED where required for egress | NC relay or fail-unlocked hardware selected for the actual lock | Power-loss behavior and egress requirements depend on the lock hardware and applicable local code |
| Door lock (secured area) | LOCKED (maintain security) | Normally-Open (NO) relay + fail-secure electric strike or latch | Loss of power leaves a fail-secure strike or latch locked; a magnetic lock releases |
| Emergency stop (industrial) | STOPPED (prevent injury) | NC contacts in series (break-to-stop) | Any failure in circuit = machine stops |
| Ventilation damper (lab fume hood) | OPEN (exhaust hazardous fumes) | Spring-return damper + NO relay | Power loss = spring opens damper |
Decision tree:
Step 1: Define the safe state
Ask: “For each defined failure, which actuator position minimizes harm? State whether controller power, relay-coil power, and actuator power are lost, and account for the hardware and local code.”
- Example: Smart oven heater → Safe state = OFF
- Example: Server room cooling fan → Safe state = ON
Step 2: Match relay type to safe state
| Desired safe state | Power-loss actuator position | Relay type |
|---|---|---|
| Actuator OFF/unpowered | De-energized | Normally-Open (NO) relay |
| Actuator ON/powered | Energized from an independent supply | Normally-Closed (NC) relay; loss of coil power closes the contact only while actuator power remains available |
| Specific mechanical position | Independent of power | Spring-return actuator + NO relay |
Step 3: Validate fail-safe behavior with fault injection testing
Physically test all failure modes:
Test 1: Disconnect power to IoT controller
Expected: Actuator moves to safe state
Pass/Fail: ___

Test 2: Disconnect network (Wi-Fi, Ethernet)
Expected: A separate communication-loss timer or local fallback moves the actuator to its defined safe state; a task watchdog need not expire while firmware is still running.
Pass/Fail: ___

Test 3: Force microcontroller crash (trigger WDT)
Expected: Hardware reset → relay de-energizes → safe state
Pass/Fail: ___

Test 4: Remove relay coil power wire
Expected: Relay de-energizes → safe state
Pass/Fail: ___
Worked example: Smart greenhouse ventilation
Requirements:
- Vent must open if temperature exceeds 35°C (95°F)
- Safe state on failure: Vent OPEN (prevents crop loss from overheating)
Wrong design (unsafe):
Vent motor: Powered to open, unpowered to close
Relay: Normally-Open (NO)
Failure behavior: Power loss → relay open → motor unpowered → vent CLOSES → crops overheat
Correct design (fail-safe):
Vent motor: Spring-loaded to open position
Relay: Normally-Open (NO) controls solenoid that holds vent CLOSED
Normal operation: IoT energizes relay when T < 35°C → solenoid holds vent closed
Failure: Loss of relay-coil power opens the relay and releases the solenoid; a separate communication-loss timer or local fallback is needed for network outages. The spring opens the vent if actuator power is lost.
Alternative correct design (NC relay):
Vent motor: Powered to close, unpowered to open (spring-return)
Alternative (controller/coil-power loss only): An NC contact supplies a powered-to-open actuator from an independent motor supply. When relay-coil power is lost, NC closes and powers the motor open. If motor power also fails, this cannot guarantee opening; add spring return for all-power-loss fail-open behavior.
Trade-off comparison: A spring-return vent actuator adds mechanical complexity compared with a standard bidirectional motor, but it removes the crop-loss failure mode where the controller dies and leaves the vent shut.
Documentation note: For life-safety, industrial, or high-value assets, document the safe state, the failure assumptions, and the fault-injection tests. “Fail-safe” is an explicit design requirement for these applications, not a cosmetic feature.
The mistake: A smart irrigation controller uses GPIO pins to control 8 solenoid valves via relays. During system boot (power-on or watchdog reset), the irrigation system briefly opens ALL valves simultaneously for 2-3 seconds, flooding the garden and wasting water. In this example, the valves open during each controller reboot until the outputs are initialized.
Why it happens: During ESP32/Arduino boot-up, GPIO pins are in a high-impedance (floating) state for approximately 2 seconds until the firmware initializes and sets pin modes. Floating pins can be pulled HIGH by electromagnetic coupling or internal leakage currents, randomly energizing relays.
Measured GPIO states during boot:
| Time | GPIO Pin State | Relay Behavior | Valve State |
|---|---|---|---|
| T=0 ms (power applied) | Floating (undefined) | Random (some energize) | 2/8 valves open |
| T=500 ms (bootloader starts) | Still floating | Random | 5/8 valves open |
| T=1500 ms (firmware starts) | Still floating | Random | 7/8 valves open |
| T=2000 ms (pinMode() called) | OUTPUT LOW (firmware control) | All OFF | All valves close |
The 1.5-second flood delivers approximately:
These snapshots do not establish water wasted per boot. Measure each valve’s open time and flow, then sum Σ(flow_i × open_time_i); annual waste is the measured per-boot total × observed reboots per year.
Root cause: No pull-down resistors to define GPIO state during boot.
The fix: Add 10kΩ pull-down resistors between each GPIO pin and ground.
Circuit schematic:
| Node | Connection | Effect during boot |
|---|---|---|
| ESP32 GPIO25 | Relay driver input | Firmware can drive the relay after startup |
| ESP32 GPIO25 | 10k resistor to GND | Holds the pin LOW while it is floating |
| Relay coil | Driver output | Stays OFF unless firmware deliberately enables it |
Why 10kΩ?
- Strong enough to pull pin LOW during floating state
- Weak enough that firmware can override by driving pin HIGH
- When GPIO drives HIGH, the pull-down draws about 0.33 mA per pin; at LOW or high impedance it draws negligible DC current.
Firmware initialization is not a substitute for a boot-safe external bias
Configure the GPIO’s pull-down when firmware starts, but use a suitable external resistor or inherently safe driver input to hold the relay off before firmware runs.
gpio_pulldown_en(GPIO_NUM_25); // Post-startup only; external bias holds the pin during resetVerification test:
- Connect oscilloscope to relay control pins
- Power-cycle the system
- Measure time from power-on until pin reaches stable LOW state
- Expected: With pull-down: LOW immediately. Without pull-down: undefined for 1-3 seconds.
Why this mistake is common:
Bench testing often uses short power cycles where floating pins stay LOW by chance. The failure only appears in production when EMI (from motors, Wi-Fi) couples into floating pins, or after long power-off periods when internal capacitances discharge.
Field impact: In production irrigation controllers, this failure appears as “phantom watering” during boot or reset. Adding pull-downs to every relay input is a small board-level change; discovering the problem after installation is much more disruptive because it requires site visits, replacement boards, or firmware workarounds.
Key takeaway: Choose an external pull-down for an active-high driver or an external pull-up for an active-low driver so the actuator stays off during reset; verify the boot waveform on the actual board.
7.5 Fail-Safe Design Principles
This section: Fail-Safe Design Principles — Those principles become concrete when you translate failure into energy, travel distance, and timeout.
-
Default State: All actuators should power up in a safe state
- Valves: Closed (prevents flooding)
- Heaters: Off (prevents overheating)
- Motors: Stopped (prevents injury)
-
Power Loss Behavior: Consider what happens during power outage
- Use normally-closed relays for safety-critical shutoffs
- Spring-return valves for fail-safe closing
-
Communication Loss: If IoT device loses connection:
- Implement timeout to safe state
- Local fallback logic
- Visual/audio warning
-
Sensor Failure: If feedback sensor fails:
- Detect out-of-range readings
- Switch to open-loop with limits
- Alert user
Those principles become concrete when you translate failure into energy, travel distance, and timeout. The deep dive below is the evidence pass for that translation.
7.6 Deep Dive: Failure Energy, Interlocks, and Stall Protection
This section: Deep Dive: Failure Energy, Interlocks, and Stall Protection — Inspect Figure 7.1 to put local hazard evidence ahead of network control.
Actuators move real things, so the central safety question is not only “does it work?” but “what does it do when a wire falls off, the code hangs, or the load jams?” Good actuator safety starts by defining the least harmful physical state for the specific hazard: stopped, released, clamped, vented, open, closed, or isolated. A heater usually fails safe by turning off. A greenhouse vent may fail safe by opening. A fire-exit lock may fail safe by unlocking. A laboratory exhaust damper may fail safe by opening, even though a security door may fail safe by locking.
Inspect Figure 7.1 to put local hazard evidence ahead of network control. The useful reading order is physical status, interlock decision, and forced operating mode, because a remote command must never bypass a guard or emergency stop.
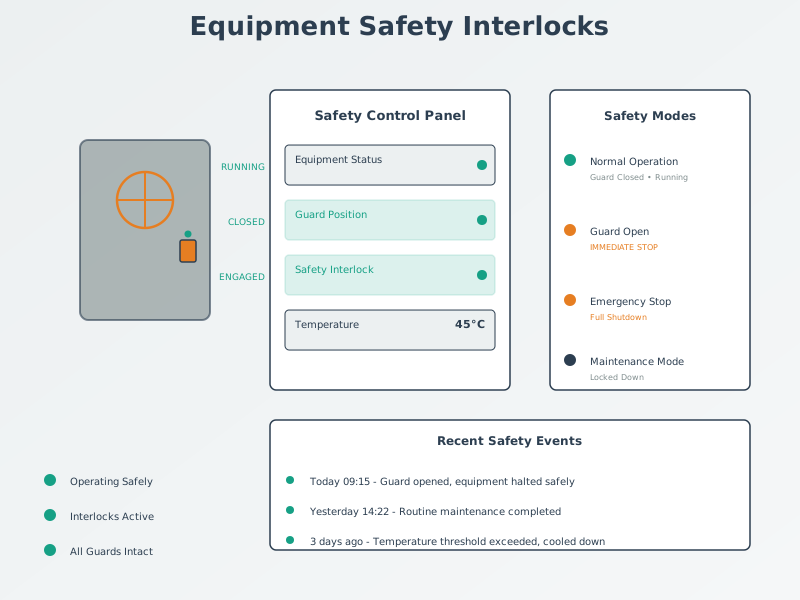
Read Figure 7.1 from equipment status and guard position into the interlock, then compare normal operation, guard-open stop, emergency stop, and maintenance lock-down. Each unsafe condition forces a bounded local response; that hierarchy connects the safe-state choice to the energy and travel calculations below.
Work the failure case with numbers. Suppose a 24 V ventilation actuator draws 0.4 A while holding a damper shut, so the coil consumes 24 V x 0.4 A = 9.6 W. If the controller must keep that coil energized to hold the safe state, a power loss removes the energy needed for safety. A spring-return design reverses the dependency: the controller spends 9.6 W during normal closed operation, and loss of power releases the spring so the damper opens. The same calculation applies to a water valve: a 12 V solenoid drawing 0.6 A dissipates 12 V x 0.6 A = 7.2 W while energized, so continuous hold current is both an energy budget and a thermal safety concern.
Fail-safe design also asks how much motion can occur after the controller has lost authority. A small linear actuator moving at 0.05 m/s travels 0.05 m/s x 2 s = 0.10 m during a two-second software hang unless a limit switch, current limit, or watchdog stops it. A conveyor moving at 0.5 m/s travels the same 0.10 m in only 200 ms, so a cloud timeout or app command is too slow for personnel protection. Hardware defaults come first, local controls second, and network supervision last.
| Protection | Guards against |
|---|---|
| Overcurrent or current limit | A stalled or shorted motor drawing destructive current |
| Thermal cutoff, fuse, or PTC | Sustained overload heating windings or wiring |
| Emergency stop | Removes actuator power directly in hardware |
| Limit switch or hard stop | Travel beyond the safe mechanical range |
| Watchdog timer | Firmware hanging while an actuator is driven |
| Opto-isolation | Power-side faults reaching the controller |
Two design choices carry much of the fail-safe weight. Choose normally-open or normally-closed contacts so that de-energized means safe for that hazard: a brake that clamps when unpowered, or a valve that closes when unpowered, fails safer than a control path that needs healthy firmware. Put the E-stop in the power path, not in software; it must cut actuator power even if the microcontroller is locked up.
Size protection around the fault, not just the normal load. If a 12 V door actuator normally draws 1.5 A, its running power is 12 V x 1.5 A = 18 W. If the mechanism jams and stall current reaches 6 A, the wiring, driver, and fuse must account for a 12 V x 6 A = 72 W fault. A practical design uses driver current limiting near the allowed peak, a fuse for wiring faults, and firmware that cuts drive if high current persists beyond the expected acceleration window.
Bias every control input into its safe state. A relay board driven from a 3.3 V GPIO should not float while the controller boots. A 10 kOhm pull-down defines the input while firmware is not yet running. When GPIO drives HIGH, it draws about 0.33 mA per pin; at LOW or high impedance it draws negligible DC current. Across eight outputs, all pins driven HIGH draw up to 2.64 mA. For high-current drivers, apply the same rule to the enable pin: hardware should hold it disabled until firmware explicitly proves it is healthy.
Choose watchdog timing from the mechanical hazard. If the critical loop normally completes in 80 ms and has a measured worst case of 120 ms, a 200 ms watchdog leaves margin. But if the actuator can cause damage after 150 ms of uncontrolled motion, the software architecture must change; slow logging or network work belongs in a background task. A watchdog is useful only when its timeout is shorter than the physical hazard time and the reset state actually removes actuator energy.
7.6.1 Why a Stalled Motor Is a Fire Risk
A spinning motor generates back-EMF, a voltage opposing the supply that rises with speed, and that back-EMF is what limits its running current. When a motor stalls, speed is zero, back-EMF is zero, and the only thing limiting current is the winding’s small resistance. Stall current can therefore be many times the running current, all of it turning into heat in the windings.
Use a simple DC motor model to see the jump. A 12 V actuator motor with 2 ohm winding resistance may generate 9 V of back-EMF at normal speed. The winding then sees only 12 V - 9 V = 3 V, so running current is 3 V / 2 ohm = 1.5 A. Copper heating is I^2R = 1.5^2 x 2 = 4.5 W. At stall, speed is zero and back-EMF is zero. The same winding sees the full 12 V, so current becomes 12 V / 2 ohm = 6 A and copper heating becomes 6^2 x 2 = 72 W. That is sixteen times the heat in the winding.
Thermal time matters. If the winding and case can absorb 40 J before exceeding a safe temperature rise, then 72 W of stall heating reaches that energy in about 40 J / 72 W = 0.56 s. A cloud alert or thirty-second timeout cannot protect that motor. The protective action must be local and fast: current limit in the driver, a hardware fuse or PTC for wiring faults, a thermal cutoff for sustained heating, and a position or current-based stall detector that removes drive within the allowed time.
This section:
 Checkpoint: Fault Energy
You now know:
- Safety timing comes from motion and heat: 0.10 m of uncontrolled travel or 72 W of stall heating can matter before a cloud alert arrives.
- Biasing a relay input with a 10 kOhm pull-down costs only 0.33 mA per pin but prevents undefined boot behavior.
- A useful safety proof combines current limiting, thermal cutoff, watchdog reset state, e-stop wiring, and fault-injection tests.
This section:
7.7 Summary
This section: Summary — Actuator safety is about limiting energy when hardware, firmware, communication, or users behave unexpectedly.
Actuator safety is about limiting energy when hardware, firmware, communication, or users behave unexpectedly. Good designs combine electrical protection, mechanical limits, watchdogs, safe defaults, and clear manual override paths before the actuator is connected to a real load.
Actuator safety requires multiple layers of protection: flyback diodes for inductive loads, overcurrent protection with fuses, watchdog timers for software reliability, and fail-safe defaults that put actuators into safe states when power or communication is lost. For high-voltage applications, proper electrical isolation, rated components, enclosed wiring, and compliance with electrical codes are mandatory. Always design for the worst case: what happens when everything goes wrong at once.
“Safety meeting!” called the microcontroller, gathering the team. “Before we connect any actuators, we need to talk about protection.”
“Protection from what?” asked DC Danny the Motor.
“From YOU, Danny!” said Max with a smile. “When you stop spinning, your coils create a nasty voltage spike — like a tiny lightning bolt. Without a flyback diode to catch it, that spike could fry my circuits!”
Danny looked embarrassed. “I don’t mean to do it…”
“It’s just physics,” said Temperature Terry kindly. “That’s why we always put a diode — think of it like a lightning rod — right next to motors and relays.”
the battery raised another concern. “What if Max’s software freezes? Like when your computer stops responding? Danny could be left spinning forever, or a heater could stay on and get dangerously hot!”
“That’s why I have a watchdog timer!” Max explained. “It’s like having a friend who pokes me every 3 seconds and says ‘Are you still awake?’ If I don’t answer, it restarts me and everything goes back to the safe position — motors stopped, heaters off, valves closed.”
“And the number one rule,” the LED said, flashing red for emphasis, “is that when the power goes out or something breaks, EVERYTHING should go to its SAFEST state. Heaters OFF. Valves CLOSED. Motors STOPPED. We call it fail-safe!”
“Safety first, second, and third!” the whole team cheered.
7.8 Knowledge Check
This section: Knowledge Check
7.9 Quiz: Actuator Safety
This section: Quiz: Actuator Safety
7.10 Concept Relationships
This section: Concept Relationships
| Concept | Relates To | Connection Type |
|---|---|---|
| Flyback Diodes | Relays and Solenoids | Protect circuits from inductive kickback |
| Fail-Safe Design | Actuator Introduction | Safe default states on power loss |
| Watchdog Timers | ESP32 Programming | Software hang detection and recovery |
| Overcurrent Protection | Electronics | Fuses and current limiters prevent damage |
7.11 See Also
This section: See Also
- Relays and Solenoids - Flyback protection for inductive loads
- DC Motors - Motor driver thermal management
- Actuator Labs - Implement watchdog timers in projects
- PWM Control - Avoid overcurrent with soft-start
- Actuator Assessment - Safety troubleshooting guide
7.12 What’s Next?
This section: What’s Next? — Now that you can apply safety protections to actuator circuits, explore related topics to deepen your practical skills.
Now that you can apply safety protections to actuator circuits, explore related topics to deepen your practical skills.
| Chapter | Description |
|---|---|
| Hands-On Labs | Build complete actuator projects with safety circuits on ESP32 |
| Relays and Solenoids | Apply flyback diode protection to relay and solenoid circuits |
| DC Motors | Implement thermal management for motor driver circuits |
| PWM Control | Use soft-start PWM techniques to prevent overcurrent surges |
| Actuator Assessment | Test your safety knowledge with troubleshooting scenarios |
7.13 Continue Your Route
This section: Continue Your Route — This is the last part of this chapter.
This is the last part of this chapter. Return to Actuator Safety: Protection and Fail-Safe Design or continue from the actuators module index.
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed