Request-Response
One caller asks one target for a result, then uses the response to continue or stop.
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
This section: Start With the Decision — A block diagram shows parts, but it does not record why a choice was safe.
A block diagram shows parts, but it does not record why a choice was safe. A decision record keeps the claim, evidence, and fallback together.
This section: Route Overview — This is part 2 of 2.
This is part 2 of 2. Review Systems Thinking: Boundaries and Processes for the preceding evidence.
This section: Learning Objectives
This section: Chapter Roadmap
This section: Decision Records — Process-and-system decision records make design choices reusable.
Process-and-system decision records make design choices reusable. They also help the next maintainer understand why a block diagram, interface, placement choice, or fallback rule was accepted.
Figure 3.1 ties a cold-room monitoring choice to timing, outage, and workflow constraints.
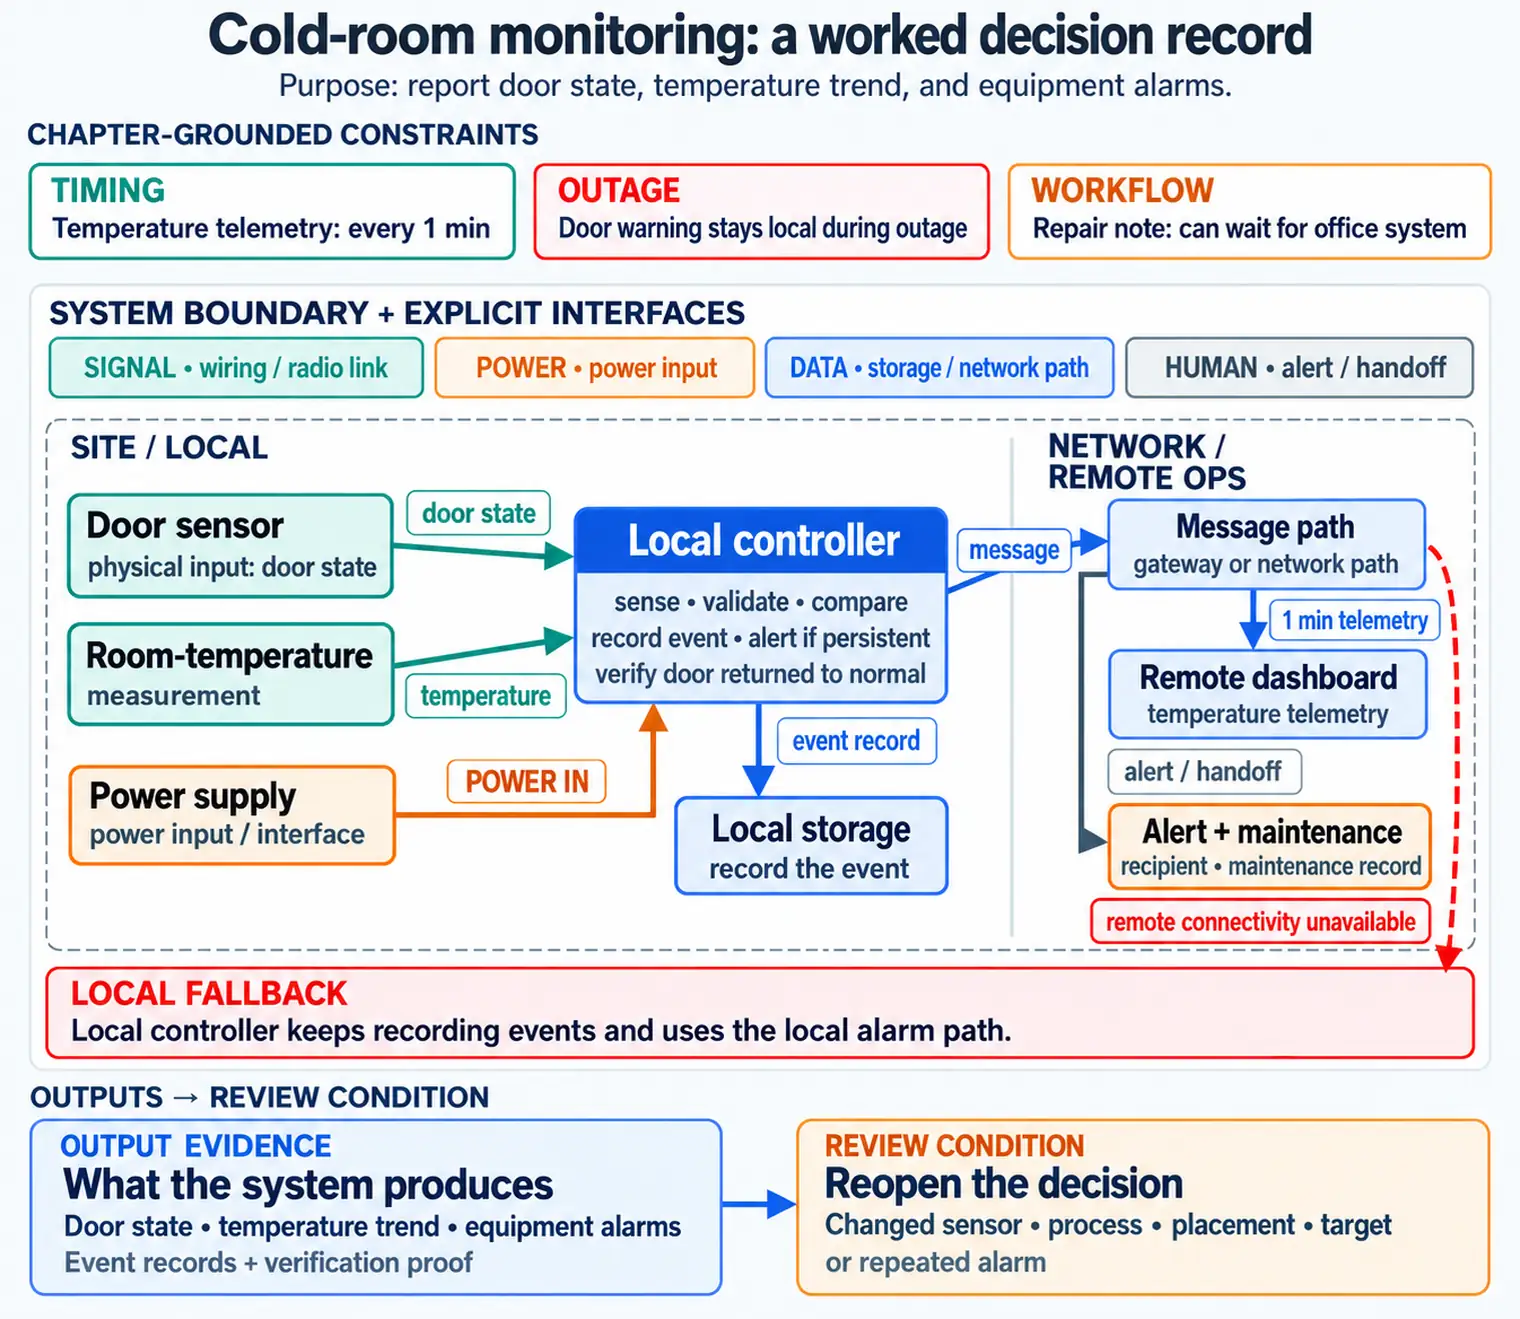
Temperature telemetry is expected every minute, but a door warning must remain local during an outage. A repair note can wait for the office system, so these flows do not need the same timing or failure treatment. The record places each flow at a system boundary and names the interface that carries it. It should also preserve the output expected at that interface and the condition for review. Testing a network outage then checks that the door path still warns locally while delayed telemetry and the repair note recover through their assigned paths.
Process-and-system decision
Purpose: what outcome the system exists to produce
Boundary: owned components, outside dependencies, and excluded responsibilities
Inputs: physical, informational, power, configuration, and operator inputs
Process: validation, decision, communication, actuation, logging, fallback
Outputs: physical action, messages, records, alerts, and verification proof
Interfaces: signal, power, data, mechanical, service, and human handoff points
Constraints: timing, energy, safety, accuracy, connectivity, support, maintenance
Review condition: changed sensor, actuator, process, placement, target, or repeated alarmThis section: Learning Route — This chapter orients the series.
This chapter orients the series. Inspect Figure 3.2 to choose the next chapter based on the question you are trying to answer.
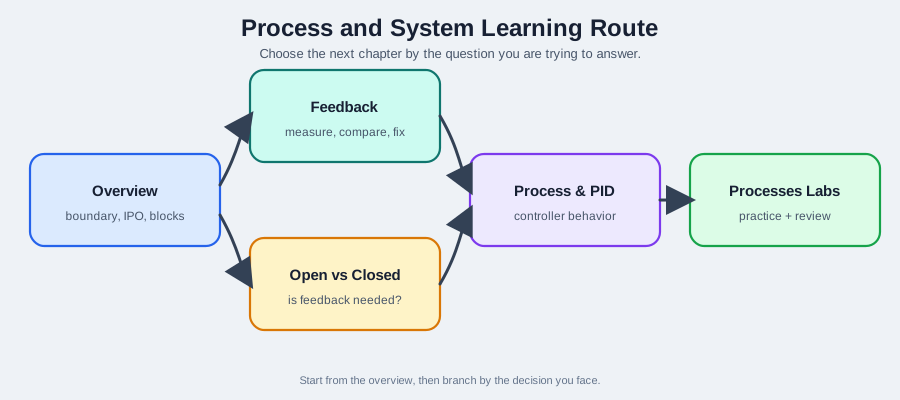
Read Figure 3.2 from the overview question into the feedback and loop-choice branches, then continue to PID theory, implementation, or tuning according to the evidence gap you need to close. This returns the chapter’s system vocabulary to a concrete next decision.
Need loop vocabulary?
Use Feedback Mechanisms to study measurement, comparison, correction, and verification.
Choosing open or closed loop?
Use Open vs Closed Loop to decide whether feedback is needed.
Choosing controller behavior?
Use Process Control and PID before moving into detailed controller chapters.
Need practice?
Use Processes Labs after the system boundary and loop proof are clear.
This section: Fundamentals Route Addendum — Use the overview as the entry point for a stable decision sequence.
Use the overview as the entry point for a stable decision sequence. Keep system vocabulary separate from process vocabulary and control vocabulary so later feedback and PID choices have a clear basis.
| Decision step | Record to capture |
|---|---|
| Core definitions | Purpose, boundary, environment, inputs, transformation, outputs, retained state, constraints, interfaces, assumptions, and review conditions. |
| Input-process-output | What enters, what changes, what leaves, what state is retained, and which constraints shape acceptable behavior. |
| Block diagram | Responsibility of each block, meaning of each interface, trusted inputs, verified outputs, dependencies, and fallback points. |
| Decomposition | Device, communication, site or edge, remote service, and operator workflow responsibilities. |
| Feedback need | Whether the system must measure the result before choosing the next action. |
| Control complexity | Open-loop, on/off feedback, proportional-family, or PID choice made only after measurement trust, actuator authority, timing, and fallback are clear. |
This route prevents premature labels. A design is not closed-loop because it has a sensor, and it is not PID because it has a variable output. The record should show the measurement, comparison, command, output limit, and fallback behavior before the control label is accepted.
This section: Cold-Room Door Monitoring — A cold-room monitoring system reports door state, temperature trend, and equipment alarms.
A cold-room monitoring system reports door state, temperature trend, and equipment alarms. A process-and-system overview does not start by choosing a controller. It starts by naming boundaries and flows.
System boundary: door sensor, room-temperature measurement, local controller, power supply, message path, remote dashboard, alert recipient, and maintenance record.
Process: sense the door state, validate the reading, compare against allowed open duration, record the event, alert if the condition persists, and verify that the door returned to normal.
Interfaces: sensor wiring or radio link, controller input, local storage, gateway or network path, alert channel, and maintenance handoff.
Fallback: if remote connectivity is unavailable, the local controller should keep recording events and use the local alarm path if the condition remains unresolved.
The same system can later be inspected as a feedback loop, an alerting workflow, a networked gateway pattern, or an operations record. The overview diagram keeps those later views grounded.
This section: Knowledge Check
This section: Match the Overview Concepts
This section: Order a Process-and-System Decision
This section: Key Concepts — Set the system boundary and the output to watch.
Set the system boundary and the output to watch. Then choose the control to review.
This section: Common Pitfalls
Starting with code instead of boundaries
Implementation becomes hard to check when nobody knows what the system owns or which process each block supports.
Drawing every wire too early
A block diagram should expose responsibilities and flows first. Low-level wiring belongs in a later implementation view.
Ignoring output verification
An output is not trustworthy until the design says how it is checked, logged, or escalated.
Hiding dependencies
External services, human actions, network paths, and maintenance records are still part of the system behavior.
Confusing feedback with the whole system
Feedback is one process pattern. The system also needs interfaces, ownership, constraints, and fallback behavior.
Leaving no review condition
Sensor moves, actuator changes, new targets, placement changes, and repeated alarms can invalidate the original diagram.
This section: Communication Models for IoT
Picture a cold room with one sensor and one cooling unit. The sensor sends a temperature every minute. A worker can also change the target. An open door must trigger a local warning. A repair note can wait until the office system is ready.
These messages do different jobs. A communication model describes the shape of each exchange. It asks who starts. It asks who waits. It asks whether one or many receivers need the message. It also asks what happens when the other end is missing.
Use four simple shapes. A request asks for a direct answer. A published event lets several listeners react. A local event can act without a distant service. A queued task can wait for later work. The same product may need all four.
Choose from the consequence. A late repair note is inconvenient. A late cooling command may spoil stock. A missed door warning may need local action. Record when a retry is safe. Record how the receiver proves that it acted. Keep the owner of each wait clear.
This first view gives each message one tidy shape. Real systems can combine shapes and cross several trust boundaries. The Practitioner layer turns each flow into a design record. Under the Hood examines delivery state, duplicate action, outage behavior, and the cases where a simple arrow hides important responsibility.
Communication models describe how a message behaves before the team chooses HTTP, CoAP, MQTT, AMQP, WebSocket, a queue, or a stream. The model names who starts the exchange, who consumes it, whether the sender waits, what happens during outage, and what evidence proves the flow worked.
In a refrigerated warehouse, the same gateway may need four different communication models. Temperature telemetry can be pushed every minute and published to a broker so a dashboard, history store, alert service, and maintenance model can consume it independently. A compressor setpoint change should behave like a request-response command: the operator needs to know whether the gateway accepted, rejected, timed out, or deferred the change. A door-left-open event should run locally even if the cloud path is down. A maintenance report can be queued asynchronously because a technician can wait for a final work-order reference.
Beginner Rule
Pick the communication model per flow. A device can publish telemetry, raise local events, accept request-response commands, and replay buffered history without forcing all flows into one pattern.
Do not carry Start With Flow, Not Protocol forward as an untested abstraction. Figure 3.3 anchors it in the visible claim that communication models turn message movement into an architecture boundary.
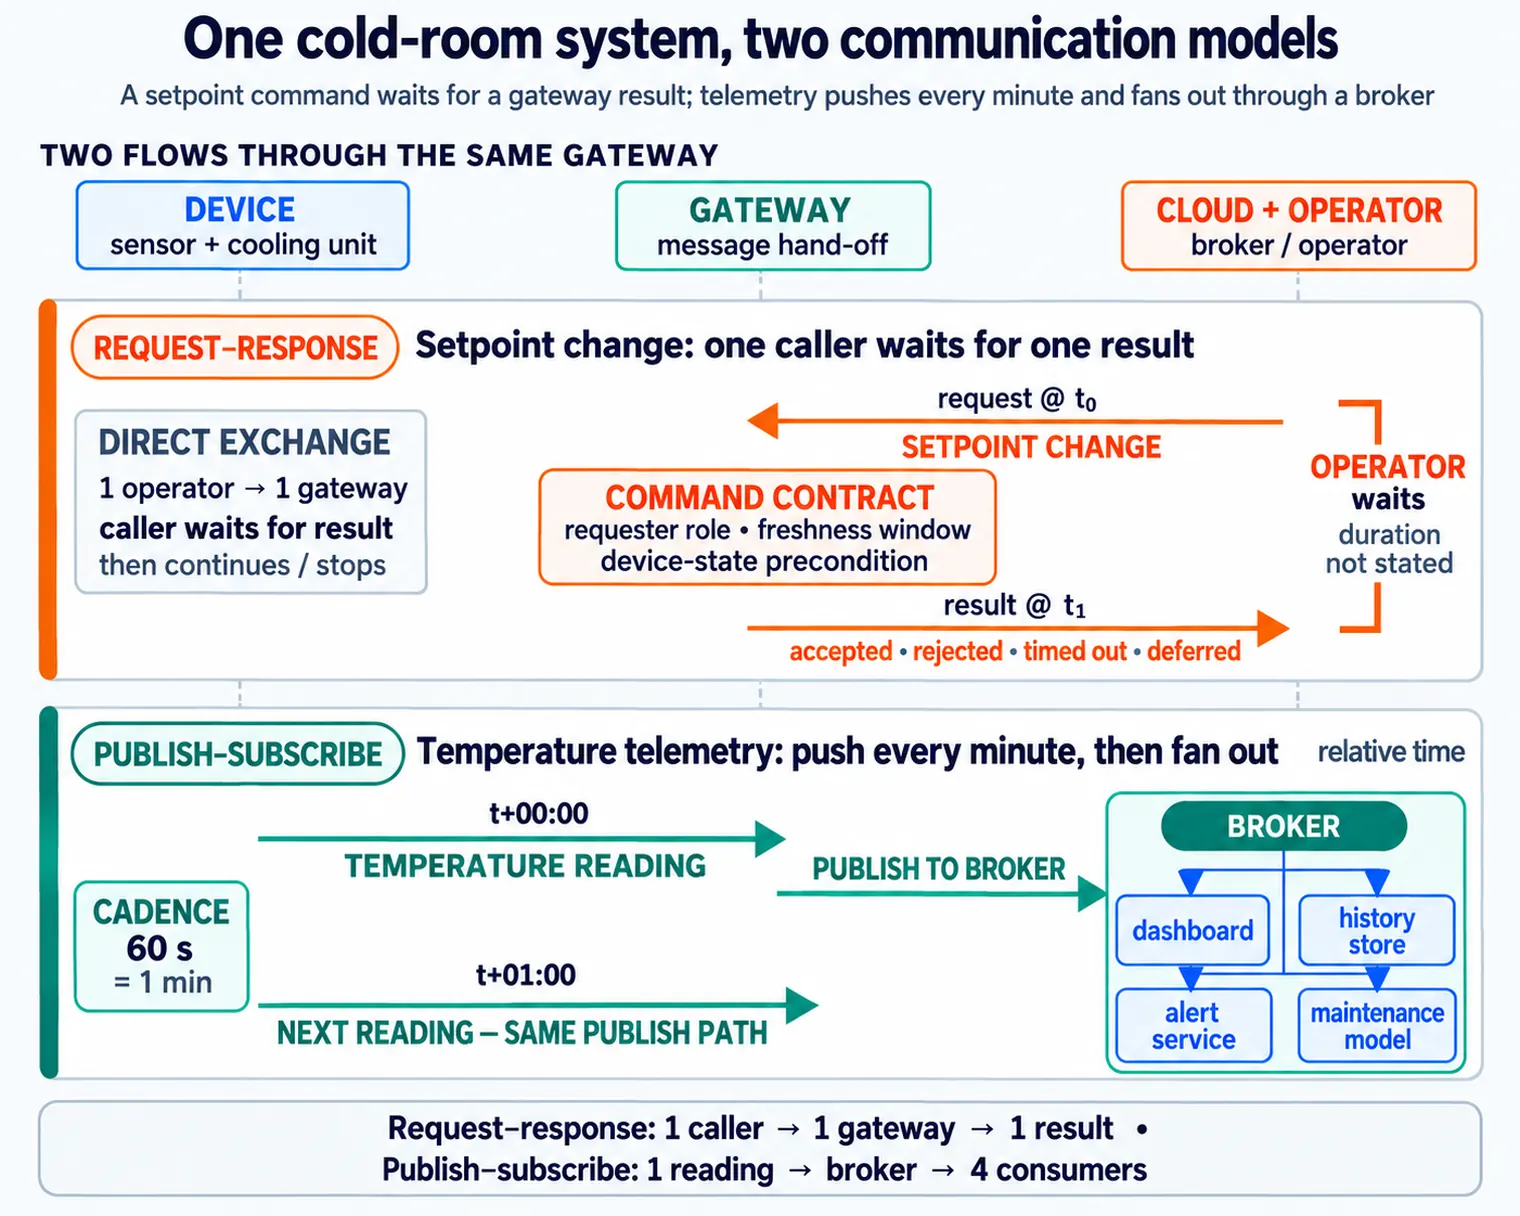
Use Figure 3.3 to compare the responsibilities named sense, act, sleep and Application, then inspect What evidence? for the consequence. This comparison explains why communication models turn message movement into an architecture boundary. It closes the visual loop back to Start With Flow, Not Protocol and the design choice now under review.
Request-response fits a command, query, enrollment step, or configuration change that needs an accepted-or-rejected result. Publish-subscribe fits telemetry, alarms, status, and fan-out where new consumers may appear later. Event-driven design fits meaningful state changes such as threshold crossings, failures, workflow transitions, and local safety actions.
Request-Response
One caller asks one target for a result, then uses the response to continue or stop.
Publish-Subscribe
Producers publish to a topic so dashboards, storage, analytics, and operations tools can consume independently.
Event-Driven
A meaningful change triggers local logic, queued work, downstream processing, or an operator workflow.
Hybrid Flow
A real system combines models, but each major flow still needs its own owner, failure behavior, and evidence.
The surrounding explanation becomes actionable when its components can be followed. Figure 3.4 provides that route for Start With Flow, Not Protocol, showing how the core patterns differ in waiting behavior, consumer coupling, and recovery evidence.
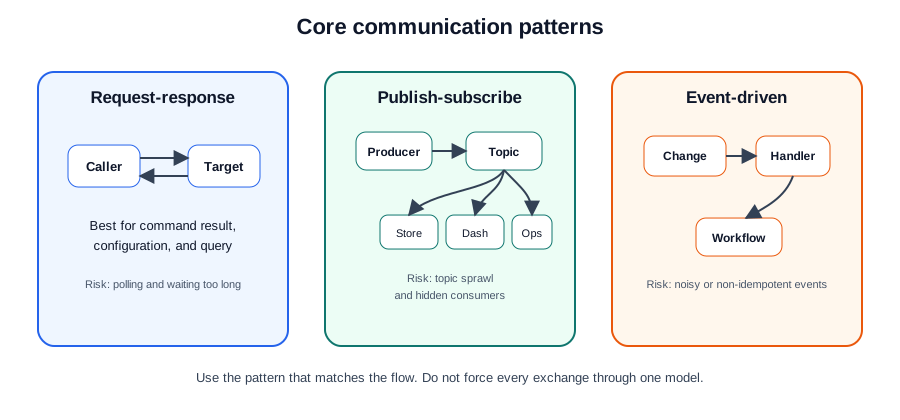
The visual argument in Figure 3.4 starts with Caller, turns on Dash, and becomes reviewable at Risk: noisy or non-idempotent events. These labels are the mechanism behind the core patterns differ in waiting behavior, consumer coupling, and recovery evidence. Their progression advances the chapter beyond the introductory statement of Start With Flow, Not Protocol.
The practical review is a flow table. For each flow, classify whether the source pushes or the consumer pulls, whether the sender waits synchronously or hands off asynchronously, whether the data needs fan-out, and what recovery evidence is required after outage.
The chapter now shifts from naming Separate Timing and Outage Needs to proving it. Figure 3.5 matters because it shows how push, pull, synchronous, and asynchronous are timing behaviors that can combine with the core patterns.
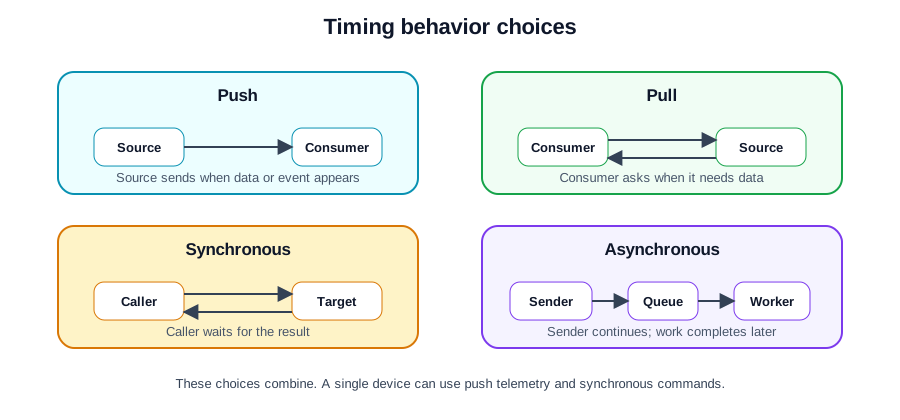
Read the diagram in Figure 3.5 by comparing Source sends when data or event appears with Consumer asks when it needs data. Then contrast Caller waits for the result with Sender continues; work completes later. Those pairs separate push from pull and synchronous from asynchronous behavior, carrying Separate Timing and Outage Needs into a per-flow outage and replay decision.
Selection Rule
Do not choose one model for the whole system. Choose one model per important flow, then document why the selected protocol currently implements that model well enough.
For a cold-storage facility, temperature telemetry usually fits push plus publish-subscribe because dashboards, history, alerting, and analytics can consume the same reading. A high-temperature alarm should trigger local event-driven behavior so safety action does not depend on cloud availability. A compressor setpoint change needs request-response because the operator must know whether the command was accepted, rejected, stale, unauthorized, or blocked by local limits.
Make the table concrete enough to test. For telemetry, write the topic name, timestamp rule, duplicate rule, and buffered replay rule. For an alarm, record the local threshold, latch behavior, operator acknowledgement, and the cloud event that proves it was later synchronized. For a command, record the requester role, freshness window, device state precondition, rejection reason, and audit event. Those fields matter more than whether the first implementation uses MQTT, CoAP observe, HTTP polling, WebSocket, or an AMQP queue.
Figure 3.6 compares communication models against the needs of each cold-storage flow.
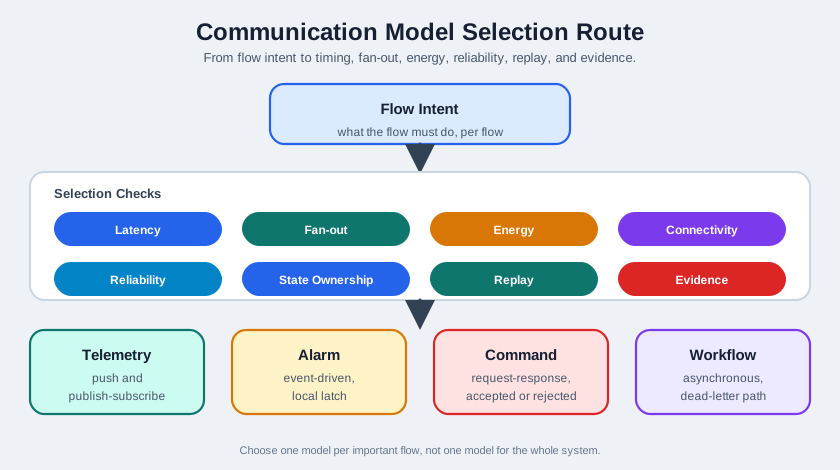
Temperature telemetry can be published for several consumers and replayed after a link gap. A high-temperature alarm needs a local action when the cloud is unreachable. A compressor setpoint command has a different path: the requester needs an accepted, rejected, stale, or unauthorized result. The route asks about timing, fan-out, energy, connectivity, reliability, state ownership, and replay before assigning a model. Record the receiver and failure evidence for each flow, then choose a protocol that implements that model. One message pattern cannot satisfy all three just because it is convenient to deploy.
Telemetry Flow
Usually push and publish-subscribe, with schema, timestamp, retention, duplicate, and replay rules.
Alarm Flow
Usually event-driven locally, with latch behavior, acknowledgement, replay marker, and operator visibility.
Command Flow
Usually request-response, with requester role, freshness check, accepted state, rejection reason, and audit event.
Workflow Flow
Often asynchronous, with correlation key, retry status, dead-letter handling, and final work reference.
Under the hood, a communication model is a contract about state, timing, replay, and ownership. A publish-subscribe flow is weak if nobody owns topic contracts or duplicate handling. A request-response flow is weak if the response only proves that a packet arrived, not that the command was fresh, authorized, and applied. An event-driven flow is weak if handlers are not idempotent or if local and cloud records disagree after recovery.
Evidence Fields
To keep Model as Evidence Contract auditable, the chapter now needs a visual contract. Figure 3.7 provides it by showing how the review record keeps protocol changes from erasing the original model reasoning, describing behavior first and implementation second.
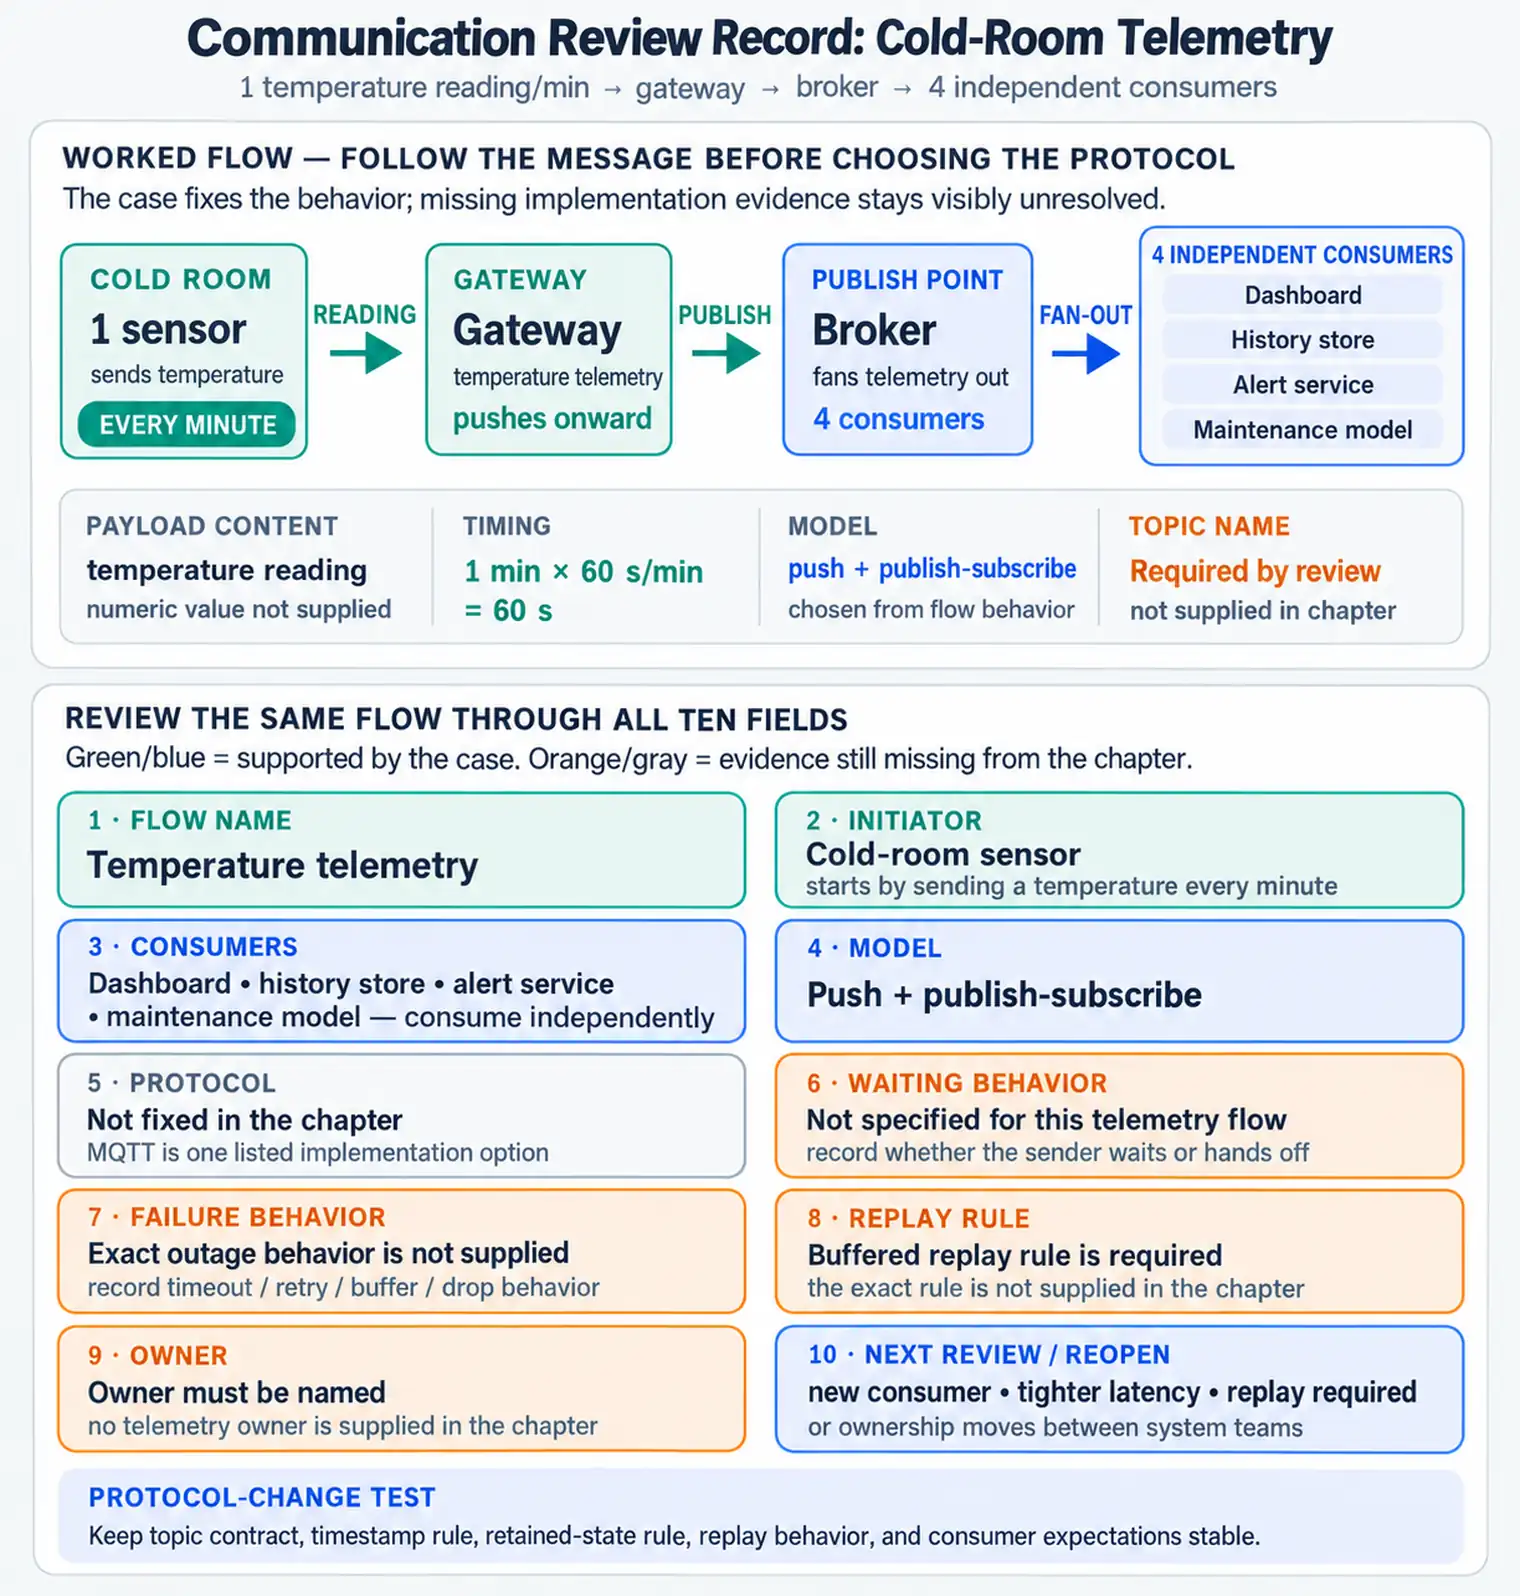
Figure 3.7 separates Flow Name, Waiting Behavior, and Reopen the Decision so the reader can see where the claim might fail. Taken together, they show the review record keeps protocol changes from erasing the original model reasoning, describing behavior first and implementation second. That failure-aware reading connects the figure directly to Model as Evidence Contract and its later proof obligations.
Protocols can change while the model remains stable. A telemetry path can move from one broker to another if the topic contract, timestamp rule, retained-state rule, replay behavior, and consumer expectations still hold. A command path can change transport if it still preserves freshness, authorization, applied-state proof, rejection reasons, and audit evidence. That is why the review record should describe behavior first and implementation second.
The hardest failures usually come from hidden model changes. A "simple" dashboard feature may turn one telemetry consumer into five consumers and require publish-subscribe fan-out. A firmware update may turn a configuration write into a safety-relevant command that needs a response contract. A battery-saving change may make pull polling impractical because devices sleep longer. Treat those changes as model changes, not only protocol changes.
Reopen the Decision
Recheck the model when a new consumer appears, latency targets tighten, a flow becomes safety-relevant, devices sleep longer, outage windows grow, replay becomes required, or ownership moves between device, gateway, cloud, and operations teams.
IoT communication models explain how each flow behaves: who starts it, who consumes it, whether the sender waits, what happens during outage, and which evidence proves the behavior. Start with the flow, split mixed requirements, choose request-response, publish-subscribe, event-driven, push, pull, synchronous, asynchronous, or hybrid behavior where it fits, and then choose the protocol that implements the selected model with clear ownership.
Choose communication models from flow evidence, not protocol preference: telemetry, alarms, commands, and workflows often need different timing, fan-out, outage, replay, and ownership contracts.
Pick the message model from flow needs. Check time, replay, and owner before protocol choice.
This section: Summary — Process-and-system thinking gives IoT design a stable starting point.
Process-and-system thinking gives IoT design a stable starting point. Define the system boundary, list inputs and outputs, trace the process, draw block diagrams at the right abstraction level, decompose responsibilities, and record constraints and fallback behavior. Feedback, open-loop choices, and controller design become clearer once the system view and process flow are explicit.
This section: See Also — Review what the system changes and where the result is observed before treating a block diagram as design proof.
Review what the system changes and where the result is observed before treating a block diagram as design proof.
This section: What’s Next — Continue with PID Control Theory for error signals, P/I/D terms, windup, derivative filtering, tuning proof, and records.
Continue with PID Control Theory for error signals, P/I/D terms, windup, derivative filtering, tuning proof, and records.
This section: Continue Your Route — This is the last part of this chapter.
This is the last part of this chapter. Return to Systems Thinking: Boundaries and Processes or continue from the control-gateways module index.
3 reviewed answers.
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed