8 IoT Research Methods: Fieldwork and Synthesis
More
Depth: Practitioner
Progress saves as you read. Mark sections complete as you go; your progress appears in the sidebar.
8.1 Start With the Decision
This section: Start With the Decision — A home visit can be a contextual inquiry: watching a task where it happens and asking the person about it.
A home visit can be a contextual inquiry: watching a task where it happens and asking the person about it. An interview asks a person to describe that task. The visit may reveal workarounds, extra steps people take when a product does not fit their work, that an interview misses. Field notes record what the person did, where, with which device, and why.
8.2 Route Overview
This section: Route Overview — This is part 2 of 2.
This is part 2 of 2. Review IoT Research Methods: Evidence and Selection for the preceding evidence.
8.3 Learning Objectives
This section: Learning Objectives
- Conduct contextual inquiry, interviews, and diary studies.
- Synthesize field evidence into design decisions.
8.4 Chapter Roadmap
This section: Chapter Roadmap
- Contextual Inquiry
- Interviews
- Diary Studies
- Prototype and Usability Tests
- Surveys
- Telemetry and Support Logs
- Field Pilots
- Mixed-Method Evidence Plan
- Incremental Examples
- Try It Now: Choose a Method Mix
- Micro-Exercise: Reject the Mismatch
- Method Planning Checklist
- Common Defects
- Concept Check: Pick the Research Plan
- Concept Check: Match Methods to Evidence
- Concept Check: Order the Method Plan
- Summary
- Key Takeaway
- See Also
- What’s Next
8.5 Contextual Inquiry
This section: Contextual Inquiry — Contextual inquiry means observing people in the environment where the product, task, or workaround happens.
Contextual inquiry means observing people in the environment where the product, task, or workaround happens.
Use it when the team needs to understand:
physical placement, reach, lighting, noise, weather, power, mounting, or cleaning. shared use between account owners, household members, visitors, workers, caregivers, or technicians. setup behavior under realistic interruption, time pressure, and connectivity constraints. maintenance routines such as charging, battery replacement, testing, calibration, or cleaning. workarounds that people may not remember or may not mention in an interview.
Good contextual inquiry records:
task and setting. participant role. relevant devices and infrastructure. observed actions. interruptions and workarounds. device, app, service, and support states. questions asked after observation. evidence boundary and follow-up needs.
Do not interrupt every action with questions. Watch first, then ask targeted follow-up questions such as:
“I noticed you checked the app before touching the device. What were you looking for?”. “What told you the setup was working?”. “What would you do if this message appeared when someone was waiting outside?”.
8.6 Interviews
This section: Interviews — Interviews help explain goals, decisions, language, trust, expectations, and past experiences.
Interviews help explain goals, decisions, language, trust, expectations, and past experiences. They are less reliable for predicting future behavior.
Use interviews to learn:
how people describe a task or failure. what they believe the system should know or control. which alerts feel urgent, useful, confusing, or intrusive. how roles and responsibilities are understood. how people decide whether to trust an automated action. what support or maintenance path they expect.
Avoid leading questions.
Weak question:
“Would this smart reminder make your life easier?”.
Stronger question:
“Tell me about the last time you missed, delayed, ignored, or changed a reminder.”.
The stronger question asks for evidence from a real situation instead of inviting approval of a concept.
8.7 Diary Studies
This section: Diary Studies — Diary studies ask participants to record events over time.
Diary studies ask participants to record events over time. They are useful when the experience is intermittent, private, distributed, or hard to observe in one session.
Use diary studies for:
- alert response across days or weeks
- comfort, noise, or environmental changes
- caregiver or household coordination
- device maintenance and battery events
- changing trust in automation
- situations where participants cannot host long observations
Keep diary prompts short and tied to events:
- What happened?
- Where were you?
- Who was affected?
- What did the device/app/service show?
- What did you do next?
- What was unclear or missing?
Avoid asking for long essays. Frequent lightweight records are more useful than a perfect diary that participants stop completing.
8.8 Prototype and Usability Tests
This section: Prototype and Usability Tests — Prototype tests answer whether a design representation is understandable before the team commits to implementation.
Prototype tests answer whether a design representation is understandable before the team commits to implementation.
Use prototype tests for:
- setup flows
- permission and consent screens
- role invitation and revocation
- alert language and escalation
- device state and data freshness displays
- maintenance reminders
- support handoff
- ownership transfer and decommissioning
Test with realistic states, not only the happy path. For IoT, include:
- device not found
- credential pending
- permission denied
- offline state
- stale data
- low battery
- muted alert
- update required
- shared-role conflict
Prototype fidelity should match the question. A sketch may be enough for sequence and wording. A clickable prototype may be needed for flow comprehension. A bench prototype or field prototype may be needed when physical sensing, placement, timing, or feedback affects behavior.
8.9 Surveys
This section: Surveys — Surveys are useful after the team understands the pattern it wants to measure.
Surveys are useful after the team understands the pattern it wants to measure.
Use surveys to estimate:
how common a known task, constraint, or role is. which contexts or devices participants have. how people rank trade-offs after the trade-offs are clearly described. whether a finding from qualitative research appears in a broader group.
Do not use surveys to replace discovery when the team does not yet know what to ask.
Weak survey item:
“Would you use automatic home access?”.
Stronger survey item:
“In the past month, how many times did you need to grant temporary access to someone while you were away from the entrance?”.
The stronger item asks about past behavior and context. It can still be imperfect, but it is more useful than hypothetical enthusiasm.
8.10 Telemetry and Support Logs
This section: Telemetry and Support Logs — Telemetry and support logs can show field signals that research sessions miss.
Telemetry and support logs can show field signals that research sessions miss.
Useful signals include:
- setup drop-off stages
- repeated pairing attempts
- alert mute patterns
- manual overrides after automation
- device offline duration
- low-battery and stale-data events
- support categories and resolution paths
- update failures and recovery loops
Telemetry does not explain itself. A spike in overrides might mean the automation is wrong, the UI is unclear, the context changed, or users do not trust the system. Combine logs with observation, interviews, or support review before turning the signal into a requirement.
Privacy review is part of telemetry planning. Collect the least precise signal that supports the decision, and make the data practice understandable.
8.11 Field Pilots
This section: Field Pilots — Field pilots test how product, context, service, support, and maintenance behave together over time.
Field pilots test how product, context, service, support, and maintenance behave together over time.
Use pilots when:
physical placement affects sensing or actuation. shared roles need to coordinate. the support path is part of the experience. maintenance or failure recovery matters. telemetry needs interpretation in real context. automated rules need trust-building and override evidence.
A field pilot should have a clear scope:
what decision it will inform. who is included and excluded. what data is collected. what support is available. what failure and maintenance states will be reviewed. what conditions would stop, revise, or expand the pilot.
8.12 Mixed-Method Evidence Plan
This section: Mixed-Method Evidence Plan — The plan in Figure 8.1 starts with the decision research should change.
The plan in Figure 8.1 starts with the decision research should change.
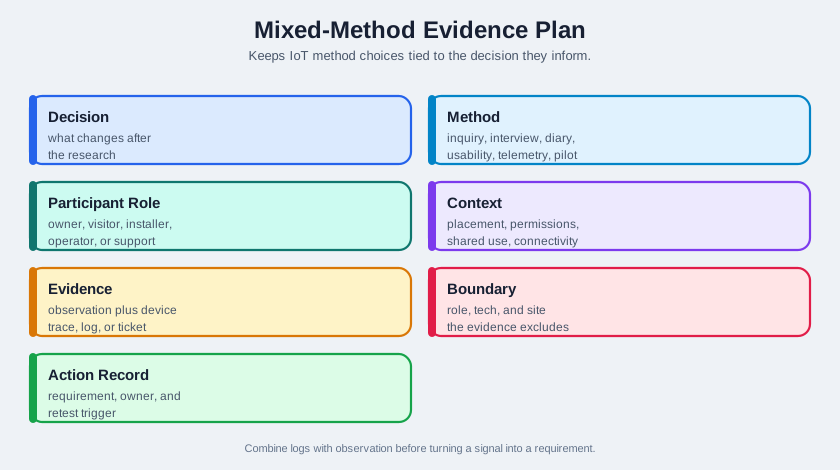
Method and participant role then identify who will be asked or observed, from owners and visitors to installers or support. Context records placement, permissions, shared use, and connectivity so a device trace is read with the situation that produced it. Evidence can join observation with logs or tickets, but the boundary field states which roles, sites, or technical states remain untested. The action record turns the finding into a requirement, owner, and retest trigger. That prevents a single signal from becoming an unsupported product rule.
8.13 Incremental Examples
This section: Incremental Examples
8.13.2 Comfort Sensor Feedback
Decision:
How can a building team gather comfort evidence for facilities action without making workers feel monitored?
Evidence plan:
Interviews with workers, facilities staff, night-shift workers, and people in shared spaces. Context observations in rooms with different lighting, noise, occupancy, and connectivity. Survey only after interviews identify the comfort and privacy concerns to quantify. Telemetry review at room or zone level, not individual history, unless a justified and consented purpose exists.
Evidence boundary:
Comfort findings from one building may not transfer to another building with different zones, work patterns, or governance.
Action record:
Requirements should state what is sensed, what is not sensed, how data is summarized, who can see it, and how occupants can report problems. Reopen the study when sensors, data retention, building zones, or automation policies change.
8.13.3 Cold-Chain Maintenance Pilot
Decision:
Which research method mix should validate a cold-chain monitoring workflow before a regional rollout?
Evidence plan:
Contextual inquiry with warehouse staff, delivery drivers, quality managers, and maintenance technicians during loading, handoff, exception handling, and device replacement. Prototype tests for alert wording, acknowledgement, escalation, and exception-resolution screens. Diary prompts for drivers and warehouse staff when alerts occur outside scheduled observation. Telemetry review using MQTT event time, device id, firmware version, DS18B20 or SHT31 probe id, calibration date, battery voltage, gateway id, LoRaWAN RSSI/SNR, packet loss, and queued upload duration. Support-log review for false alarms, missed alerts, sensor placement issues, battery swaps, and trailer gateway outages. Field pilot across a small set of routes before expanding to more warehouses, carriers, and product categories.
Evidence boundary:
The pilot can support decisions about the tested routes, sensor models, firmware, trailer types, gateway placement, and escalation workflow. It does not prove performance in a different climate zone, packaging type, carrier process, or retention policy.
Action record:
Requirements should separate product-temperature excursion, sensor fault, gateway offline state, delayed upload, driver acknowledgement, quality-manager release decision, and maintenance work order. Reopen the plan when probe model, calibration interval, firmware, route profile, carrier role, alert threshold, or data-retention policy changes.
This advanced mix names the method and the system handle together. Observation explains workflow, prototype tests check comprehension, diary entries catch intermittent events, telemetry distinguishes sensor and network causes, support logs reveal operational cost, and the pilot tests whether all of those signals survive field use.
8.14 Try It Now: Choose a Method Mix
This section: Try It Now: Choose a Method Mix
Pick one IoT design decision and fill in this method plan:
| Field | Your answer |
|---|---|
| Decision | Feature, state model, alert, setup flow, dashboard, or support path |
| Evidence gap | Behavior, explanation, frequency, comprehension, physical fit, field reliability, or trust |
| Method 1 | The method that shows the most direct evidence |
| Method 2 | A second method that explains or bounds the first method |
| Signals | Logs, events, device states, firmware versions, or support tags needed for interpretation |
| Boundary | Roles, contexts, devices, and conditions the finding does not cover |
| Next action | Requirement, prototype change, support change, pilot gate, or stop condition |
8.15 Micro-Exercise: Reject the Mismatch
This section: Micro-Exercise: Reject the Mismatch — A survey asks whether users would trust automatic unlocking, but no one observes setup, proximity, or shared-access behavior.
For each plan, name the mismatch and a better method:
A survey asks whether users would trust automatic unlocking, but no one observes setup, proximity, or shared-access behavior. A field pilot records MQTT drop-offs but never interviews users or support staff about what the failures meant. A polished prototype test uses only happy-path device states even though the release decision depends on offline recovery.
8.16 Method Planning Checklist
This section: Method Planning Checklist — the design decision is specific.
Before starting research, confirm:
the design decision is specific. the method matches the evidence gap. primary, secondary, affected, and excluded roles are named. context constraints are included in the plan. consent and data boundaries are clear. observation and interpretation will be recorded separately. the team knows what evidence would change the design. telemetry or survey data will not be overclaimed. failure, maintenance, support, and shared-use states are included where relevant. evidence boundaries, requirements, owners, validation needs, and change conditions will be recorded.
8.17 Common Defects
This section: Common Defects — Method mismatch: using a survey when the team needs field observation.
Watch for:
Method mismatch: using a survey when the team needs field observation. Convenience sampling: recruiting only coworkers, early adopters, or available users. Leading questions: asking participants to agree with the intended feature. Happy-path testing: testing setup success but not failure, maintenance, support, or shared use. Telemetry overclaim: treating logs as proof of intent without interpretation. Prototype theater: testing a polished flow after the decision has already been made. No evidence boundary: writing conclusions that sound broader than the research supports. Stale conclusion: keeping research conclusions after the product, context, sensing, or policy changes.
8.18 Concept Check: Pick the Research Plan
This section: Concept Check: Pick the Research Plan
8.19 Concept Check: Match Methods to Evidence
This section: Concept Check: Match Methods to Evidence
8.20 Concept Check: Order the Method Plan
This section: Concept Check: Order the Method Plan
8.21 Combine Field Notes With Setup Events
This section: Combine Field Notes With Setup Events — When leak-sensor setup fails in occupied homes, shadow the task with consent and note where people pause, what the device shows, and how they recover.
When leak-sensor setup fails in occupied homes, shadow the task with consent and note where people pause, what the device shows, and how they recover. Pair each note with the matching setup event and firmware version so a failed scan is not confused with a refusal to grant permission. Ask a follow-up question after the task about the participant’s interpretation, then compare across homes with different network conditions. Put the resulting claim, counterexample, and design action in one evidence row.
8.22 Explain the Method Mix and Its Limits
This section: Explain the Method Mix and Its Limits — Observation can show where setup stopped; an interview can explain a participant’s reasoning; event logs can locate a technical failure in the flow.
Observation can show where setup stopped; an interview can explain a participant’s reasoning; event logs can locate a technical failure in the flow. None alone establishes prevalence in the wider population. A field pilot can test whether the revised handoff survives repeated use, but recruitment and device mix still bound the claim. The chapter’s mixed-method plan should specify which event fields can be joined to notes, who may see them, and when they are removed. This preserves the useful connection between behaviour and system state without over-collecting household data.
8.23 Practice the Decision
This section: Practice the Decision
8.24 Summary
This section: Summary — Research methods help IoT teams make better design decisions when they are matched to the evidence gap.
Research methods help IoT teams make better design decisions when they are matched to the evidence gap. Observation shows behavior and context. Interviews explain meaning. Diary studies show repeated events. Prototype tests reveal comprehension and recovery problems. Surveys and telemetry help estimate scale after patterns are understood. Field pilots test product, context, service, and maintenance together.
The best research plan is not the largest plan. It is the plan that provides enough evidence for the decision, states its boundaries, protects participants and affected roles, and creates a record that the team can revisit.
8.25 Key Takeaway
This section: Key Takeaway — Research methods should be selected for the question, context, risk, and evidence needed to guide IoT design decisions.
Research methods should be selected for the question, context, risk, and evidence needed to guide IoT design decisions.
8.26 See Also
This section: See Also — User Research Fundamentals explains why research starts with real behavior.
Research methods connect to the people/context sequence:
User Research Fundamentals explains why research starts with real behavior. Context-of-Use Analysis identifies the constraints that field methods need to capture. Personas and Journey Maps for IoT synthesizes method findings into artifacts. Pitfalls and Ethics for IoT User Research reviews consent, privacy, sampling, and automation risks. People and Context Assessment for IoT checks whether you can apply the full review sequence.
8.27 What’s Next
This section: What’s Next — User Research Fundamentals, which explains the evidence principles behind these methods.
Continue with:
User Research Fundamentals, which explains the evidence principles behind these methods. Context-of-Use Analysis, which helps turn method findings into context requirements. Personas and Journey Maps for IoT, which shows how to synthesize research findings. Pitfalls and Ethics for IoT User Research, which helps review method quality and participant risk.
8.28 Continue Your Route
This section: Continue Your Route — This is the last part of this chapter.
This is the last part of this chapter. Return to IoT Research Methods: Evidence and Selection. See Choose a UX Design Module.
Find help
3 reviewed answers.
Where should I start in a module?
Open the module page from the sidebar to see its chapters in order. Use the module map to return to a topic you need.
Modules and pathsReviewed
What can I try when a project does not work?
Check the symptom, then work through the diagnostic steps. Keep the error message and the smallest example that reproduces it.
When you are stuckReviewed
How do interactive examples work?
Use the interactive guide to check how examples and simulations work before changing your project.
Interactive examples guideReviewed