Analytics & ML · Study deck
Data Preprocessing Workflow
A warehouse sensor reports a sudden temperature jump.
Data Dora is your guide for this deck.

After studying this chapter
Learning objectives
You will be able to:
- Design a Data Quality Pipeline: Architect a validate-clean-transform workflow for IoT sensor streams
- Compare Preprocessing Techniques: Evaluate validation, imputation, and normalization methods based on sensor type and data characteristics
- Implement Edge-Side Preprocessing: Build and test resource-efficient data quality checks that run on constrained devices
- Calculate Data Quality Impact: Quantify the cost of poor data quality versus the investment in preprocessing using the 1-10-100 rule
Major section
Start With the Story
A warehouse sensor reports a sudden temperature jump.
- It may be a real door opening, a loose probe, a missing sample, or a unit change.
- A cleaning step that silently smooths the jump can erase the very event the operator needs.
- If no safe repair exists, keep the gap.
- Preprocessing can make data easier to use.
Major section
The Data Quality Problem in IoT
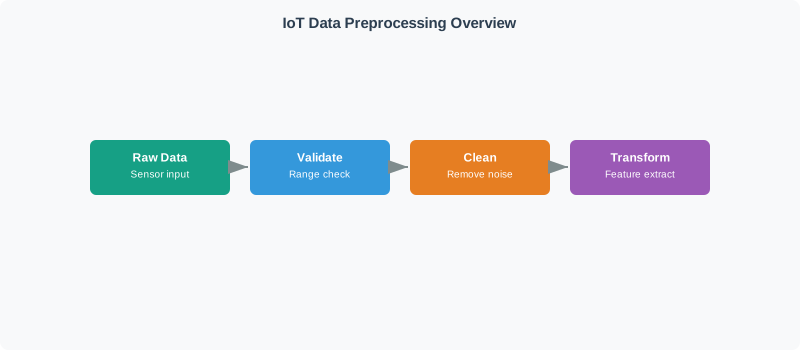
Validation marks impossible or malformed evidence before it is rewritten; cleaning applies recorded rules to gaps, duplicates, or noise; transformation prepares consistent units, windows, and features for a named consumer.
- Each stage can change what later analytics see.
Major section
The Three-Stage Pipeline
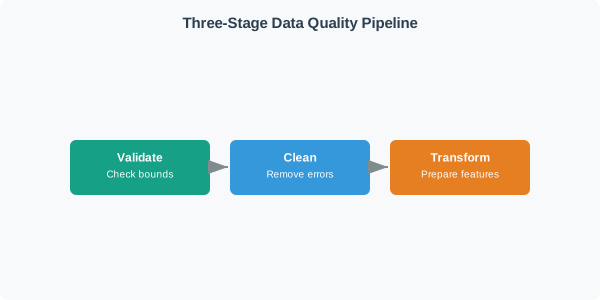
Preprocessing decisions are easier to audit when validation, repair, and feature preparation remain separate.
- Validate asks the physical-bounds question before any value changes: Clean can remove proven errors or fill bounded gaps: Transform prepares features only after accepted and repaired states are known.
Major section
Cost of Poor Data Quality
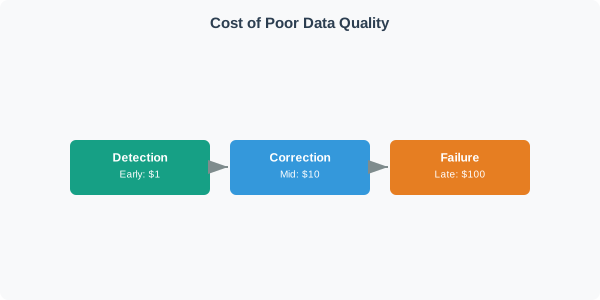
Understanding why data quality matters requires quantifying the cost of getting it wrong.
- The 1-10-100 labels are a relative heuristic, not a universal invoice: they show how contaminated evidence accumulates reprocessing, diagnosis, and decision costs as it travels.
- The meaning is the direction and compounding effect.
Major section
Smart Building Temperature Pipeline
Scenario: You are deploying 200 temperature sensors across a commercial building for HVAC optimization.
- Each sensor reports every 30 seconds.
- You need clean, analysis-ready data for the building management system.
- Step 2 -- Design Cleaning Strategy: That gives the building team a contract: every later interpolation, filter, and feature sees data that has already survived the deployment-specific rules.
Major section
Normalization Throughput Calculator
The cleaning stage interpolates only bounded short gaps; longer gaps remain flagged as missing.
- Experiment with different temperature readings, zone bounds, and sensor configurations to see how min-max normalization works and how pipeline throughput scales.
- Result: With the default settings, the pipeline processes 24,000 readings per hour (200 sensors x 2 readings/min x 60 min).
- The three-stage pipeline is illustrated in the data quality pipeline figure above. -->.
Major section
Common Pitfalls in IoT Data Quality
Skipping validation because "the sensor is reliable": Even high-quality sensors fail.
- A $500 industrial temperature sensor can still produce garbage readings when its wiring corrodes, its power supply fluctuates, or firmware bugs cause buffer overflows.
- Validation rules must be context-specific.
- A sudden temperature spike might be a genuine HVAC failure, not noise.
Major section
Common Pitfalls in IoT Data Quality (continued)
Over-smoothing the signal: Aggressive noise filtering (large window moving averages, very low alpha in EMA) removes real events along with noise.
- Ignoring sensor drift: A sensor that reads 0.5 degrees Celsius too high on day 1 might read 3 degrees too high by month 6.
- Without periodic recalibration or drift detection, your "clean" data slowly becomes systematically wrong.
- Normalizing before cleaning: If you normalize data that contains outliers, the outliers distort the scaling parameters (min, max, mean, standard deviation), making all your normalized values wrong.

Major section
Summary and Key Takeaways
Balance filtering with responsiveness: Over-smoothing removes real events.
- Data quality preprocessing is not optional in IoT systems -- it is the critical foundation that determines whether your analytics, ML models, and automated decisions can be trusted.
- Skipping or reordering stages causes compounding errors.
- Under-smoothing leaves noise that corrupts analysis.
Deck summary
Key takeaways
A warehouse sensor reports a sudden temperature jump.
- Validation marks impossible or malformed evidence before it is rewritten; cleaning applies recorded rules to gaps, duplicates, or noise; transformation prepares consistent units, windows, and features for a named consumer.
- Preprocessing decisions are easier to audit when validation, repair, and feature preparation remain separate.
- Understanding why data quality matters requires quantifying the cost of getting it wrong.
- Scenario: You are deploying 200 temperature sensors across a commercial building for HVAC optimization.
Retrieval practice
Recall check 1 of 5
Data Dora says: answer from memory, then check your reasoning.
Q1In the validate-clean-transform pipeline, why must validation run before cleaning?
Show answer
Answer: B Validation must reject impossible values first, or cleaning algorithms will smear those errors into good data.
Retrieval practice
Recall check 2 of 5
Data Dora says: answer from memory, then check your reasoning.
Q2A cleaned temperature value is used in an alert review. Which record lets the reviewer tell measurement from repair?
Show answer
Answer: D A cleaned value needs its raw source, quality state, and transformation record to support review.
Retrieval practice
Recall check 3 of 5
Data Dora says: answer from memory, then check your reasoning.
Q3According to the 1-10-100 rule, what is the approximate cost ratio between preventing a data quality issue at the edge versus fixing a wrong decision made from bad data?
Show answer
Answer: B The illustrative 1-10-100 rule assigns a 1:100 prevention-to-failure cost ratio; it is not a measured cost guarantee.
Retrieval practice
Recall check 4 of 5
Data Dora says: answer from memory, then check your reasoning.
Q4Why should you normalize data AFTER cleaning rather than before?
Show answer
Answer: B Outliers and errors can distort fitted normalization parameters (min, max, mean, std) and the scaled values that depend on them.
Q5What flags values beyond a declared physical or statistical boundary without silently deleting them?
Show answer
Answer: D An outlier rule uses a declared physical or statistical boundary rather than deleting surprises silently.
Retrieval practice
Recall check 5 of 5
Data Dora says: answer from memory, then check your reasoning.
Q6Complete the sensor data quality pipeline:
Show answer
Answer: A Sensor data cleaning involves interpolating missing values (not dropping or zeroing), range-checking against physical limits, and smoothing with an exponential moving average to reduce noise while preserving trends.
Print reference
Answers 1 of 2
Answer key.
- B · Validation must reject impossible values first, or cleaning algorithms will smear those errors into good data.
- D · A cleaned value needs its raw source, quality state, and transformation record to support review.
- B · The illustrative 1-10-100 rule assigns a 1:100 prevention-to-failure cost ratio; it is not a measured cost guarantee.
- B · Outliers and errors can distort fitted normalization parameters (min, max, mean, std) and the scaled values that depend on them.
Print reference
Answers 2 of 2
Answer key.
- D · An outlier rule uses a declared physical or statistical boundary rather than deleting surprises silently.
- A · Sensor data cleaning involves interpolating missing values (not dropping or zeroing), range-checking against physical limits, and smoothing with an exponential moving average to reduce noise while preserving trends.