Analytics & ML · Study deck
Big Data Operations
Imagine a factory dashboard whose computers all report "up" while new machine readings are two hours late.
Data Dora is your guide for this deck.

After studying this chapter
Learning objectives
You will be able to:
- Explain: Each label corresponds to a different broken contract, so the operational record must preserve the first failing boundary and the owner response instead of reducing every incident to “the cluster was down.”.
- Explain: The operations question is not "is the cluster up?" It is "can the current pipeline still produce timely, complete, replayable, and cost-bounded decisions from the device evidence?".
- Explain: If Kafka lag grows, the team checks whether producers increased, a consumer slowed, one partition became hot, a sink is throttling, or a schema error is forcing retries.
Major section
Start With the Story
Operate the Decision Path, Not Just the Servers: Imagine a factory dashboard whose computers all report "up" while new machine readings are two hours late.
- The hardware is running, yet the maintenance decision is no longer timely.
- The operations team should follow one fact from the device to the final screen.
- When an alert fires, name the first broken boundary and the decisions it affects.
Major section
Start With the Story (continued)
If a delay does not harm that job, choose a fairer limit.
- If one minute is dangerous, keep the first safe action near the machine.
- The closing note should tell the next shift what was lost, what was replayed, and what still needs watching.
- This simple path does not cover every shared service or cost trade-off.
Major section
Operations Protect Data Contracts
Operating an IoT big-data system means keeping the evidence path reliable after real devices, networks, schemas, workloads, and costs change.
- The operational contract should define service objectives for freshness, completeness, replay, retention, and query performance.
- A healthy system is not one with no alerts.
- FreshnessHow quickly an event becomes usable in alerts, dashboards, features, and reports.
Major section
Operations Protect Data Contracts (continued)
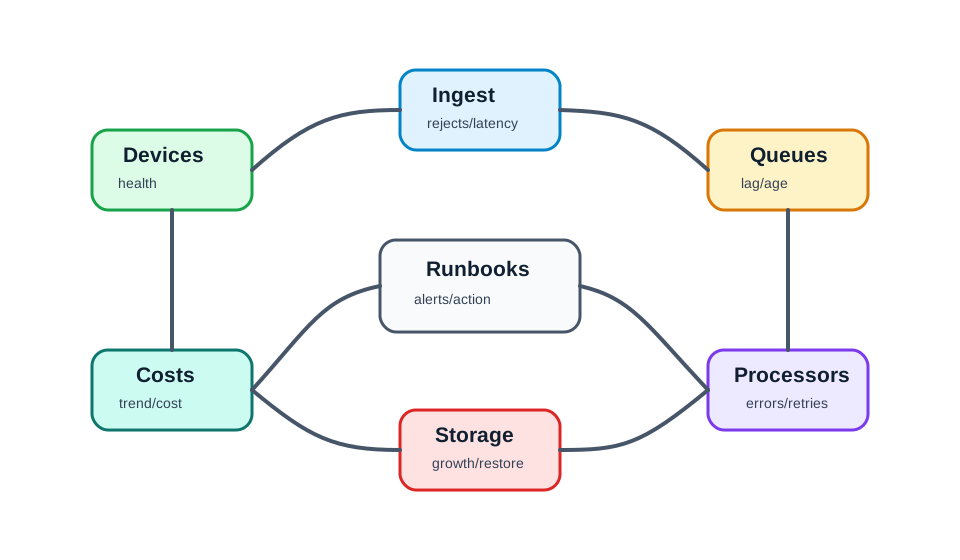
It should also name the metrics that prove the objectives are being met: broker lag, event-time delay, processing rate, validation failure rate, duplicate rate, watermark drops, storage growth, query latency, and recovery time.
- The operations question is not "is the cluster up?" It is "can the current pipeline still produce timely, complete, replayable, and cost-bounded decisions from the device evidence?".
- The path continues through: Storage growth and restore evidence to: Costs trends: Runbooks then turn those signals into alerts and action that feed the loop.
- CompletenessHow many expected devices, events, and windows arrive and pass validation.
Major section
Operations Protect Data Contracts (continued)
Each label corresponds to a different broken contract, so the operational record must preserve the first failing boundary and the owner response instead of reducing every incident to “the cluster was down.”.
- ReplayHow far back the system can rebuild outputs after a bug, schema change, or outage.
- CostHow storage, compute, stream retention, and query scans grow as data volume grows.
- GovernanceWho can change schemas, retention, access rules, quality gates, and serving definitions.
Major section
Runbooks for Lag and Storage
Operational alerts should lead to an action path.
- If Kafka lag grows, the team checks whether producers increased, a consumer slowed, one partition became hot, a sink is throttling, or a schema error is forcing retries.
- If query latency grows, the team checks partition pruning, small files, table compaction, indexing, and retention.
- Runbooks should include numbers.
Major section
Runbooks for Lag and Storage (continued)
Otherwise the restart can erase the evidence needed to explain the incident.
- A lag alert is more useful when it says how fast the backlog is growing and how long until the recovery window is exceeded.
- Each action should preserve evidence before restarting jobs or deleting data.
- Force-accept incompatible payloads into curated tables.
Major section
Reliability Needs Retesting
Long-running IoT data systems fail slowly when retention and lifecycle rules are missing.
- Raw data grows, small files multiply, compaction falls behind, dashboards scan too much history, and backup or replay windows become unclear.
- Operations should separate raw replay retention, curated analytical retention, serving retention, and aggregate retention.
- Reliability also depends on routine retests.
Major section
Reliability Needs Retesting (continued)
Each tier needs an owner, a cost limit, and a retest after policy changes.
- A restore drill proves that checkpoints can restart.
- A replay drill proves that raw events and transformation versions can rebuild a table.
- A schema-compatibility test proves that new firmware does not break downstream jobs.
- Firmware changes silently changing units, fields, or enum meanings.
Major section
Reliability Needs Retesting (continued)
operational implication: Keeping raw data forever is rarely the right control.
- Raw RetentionBounded period for replay, audit, device debugging, and reprocessing after bad code or schema changes.
- Curated TablesCleaned and versioned records for analytics, with quality flags and partition strategy.
- Storage grows faster than forecast or old raw data is needed but missing.
Deck summary
Key takeaways
Operate the Decision Path, Not Just the Servers: Imagine a factory dashboard whose computers all report "up" while new machine readings are two hours late.
- If a delay does not harm that job, choose a fairer limit.
- Operating an IoT big-data system means keeping the evidence path reliable after real devices, networks, schemas, workloads, and costs change.
- It should also name the metrics that prove the objectives are being met: broker lag, event-time delay, processing rate, validation failure rate, duplicate rate, watermark drops, storage growth, query latency, and recovery time.
- Operational alerts should lead to an action path.
Retrieval practice
Recall check 1 of 4
Data Dora says: answer from memory, then check your reasoning.
Q1Which evidence best shows that an IoT big-data system is operationally healthy?
Show answer
Answer: C Operational health is measured against the data contract and decision impact, not only cluster availability.
Retrieval practice
Recall check 2 of 4
Data Dora says: answer from memory, then check your reasoning.
Q2A stream has 420,000 events of lag, producers add 18,000 events/s, consumers process 14,500 events/s, and the critical threshold is 2,000,000 events. About how long until the threshold is hit if nothing changes?
Show answer
Answer: B Time to threshold is remaining lag budget divided by the net lag growth rate.
Retrieval practice
Recall check 3 of 4
Data Dora says: answer from memory, then check your reasoning.
Q3A stream job stalls after a schema rollout. What should the operator capture before restarting it?
Show answer
Answer: B Those records bound safe replay and show which data and decisions the incident may affect.
Retrieval practice
Recall check 4 of 4
Data Dora says: answer from memory, then check your reasoning.
Q4A raw stream stores 69.12 GB/day. Reducing raw retention from 90 days to 30 days changes the raw footprint from about 6.22 TB to about 2.07 TB. What must operations prove before making that change?
Show answer
Answer: B Lifecycle changes must preserve the evidence window needed for replay, audit, and correction.
Print reference
Answers
Answer key.
- C · Operational health is measured against the data contract and decision impact, not only cluster availability.
- B · Time to threshold is remaining lag budget divided by the net lag growth rate.
- B · Those records bound safe replay and show which data and decisions the incident may affect.
- B · Lifecycle changes must preserve the evidence window needed for replay, audit, and correction.